About Talamus
Talamus is a local-first memory MCP server for coding agents, storing decisions and evidence as Markdown and retrieving cited notes in later sessions. It supports time-aware history, provenance checks, and optional LLM engines.
Key features
- 01Markdown-based memory storage
- 02Source-cited retrieval and answers
- 03Time-aware memory queries
- 04Note verification and correction proposals
- 05Support for multiple LLM engines
Use cases
- 01Recovering decision context across sessions
- 02Reviewing project memory as of a date
- 03Checking memory claims against their sources
MCP support
It provides MCP clients with read-only memory access by default. Writes can be enabled by regenerating the server configuration.
Configuration
Local server config is the same for every client. Copy it into your client’s MCP config file.
Tools
16Saved tool list · updated 2w ago
| Parameter | Type | Required | Description |
|---|---|---|---|
| query | string | Yes | |
| smart | boolean | No |
Details
From the project READMETalamus




Your coding agent forgets why a decision was made as soon as the session ends.
Talamus keeps the decisions, evidence, and corrections worth remembering as ordinary Markdown, then gives Claude Code, Codex, Cursor, Gemini CLI, and any MCP agent cited recall in the next session.
No hosted account. No telemetry. No required embeddings. Plain search stays on your machine; LLM-backed actions use only the engine you choose.
Try the whole local retrieval loop first — no persistent install, account,
LLM, or hook, and no files written outside ./talamus-demo:
uvx --from talamus talamus demo --root ./talamus-demo
uvx --from talamus talamus search "embedding" --root ./talamus-demo
uvx --from talamus talamus read "Embedding" --root ./talamus-demo
For a technical evaluation, read the architecture and the measured benchmarks.
Talamus was created and is maintained by Giovanni “Angio” Crapuzzi under Ampres, an independent AI and open-source project. The engineering case study documents the architecture, measurements, and trade-offs behind the project.
Connect an agent
Copy-pasteable arc, with the reproducible version in
scripts/demo/run_magic.py:
-
Set up the project brain.
talamus setupinitializes the brain, chooses an engine, installs MCP for Claude Code, Cursor, Codex, OpenCode, and OpenClaw when detected, asks once before installing the session-capture hook, and can probe the engine with one tiny live call.talamus setup -
Your agent session ends. The consented hook reads the transcript and git diff, applies the worth-remembering gate, writes only useful memory into this brain, and audits the event at
.talamus/logs/capture.log. -
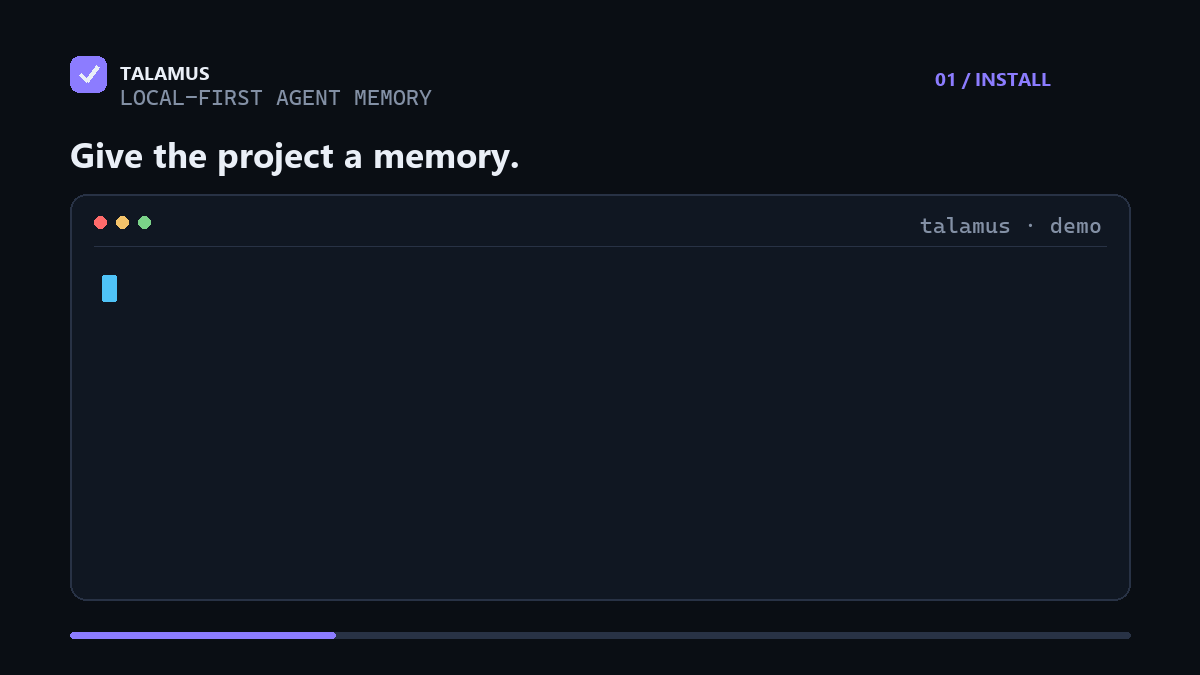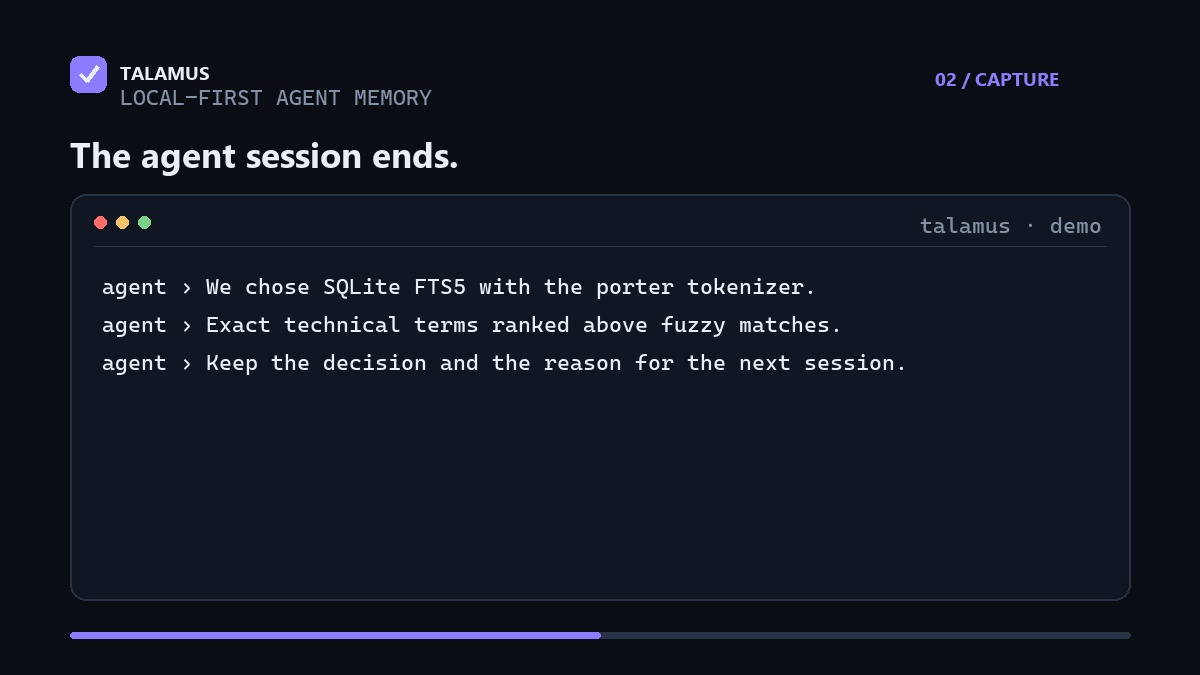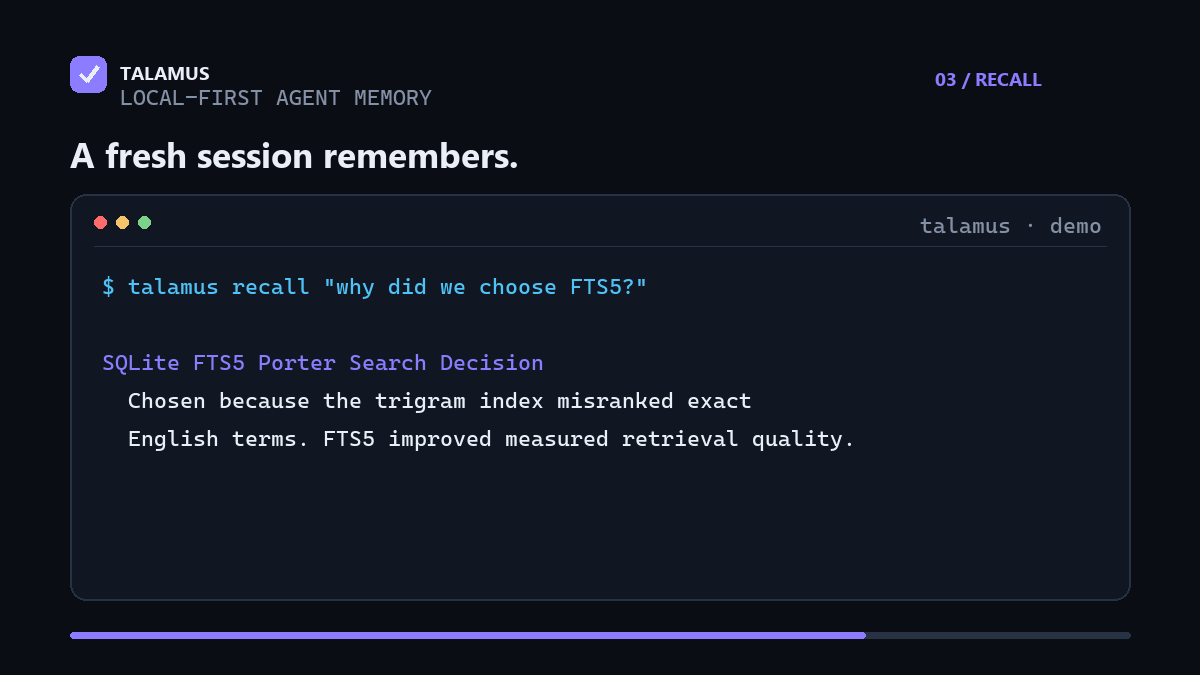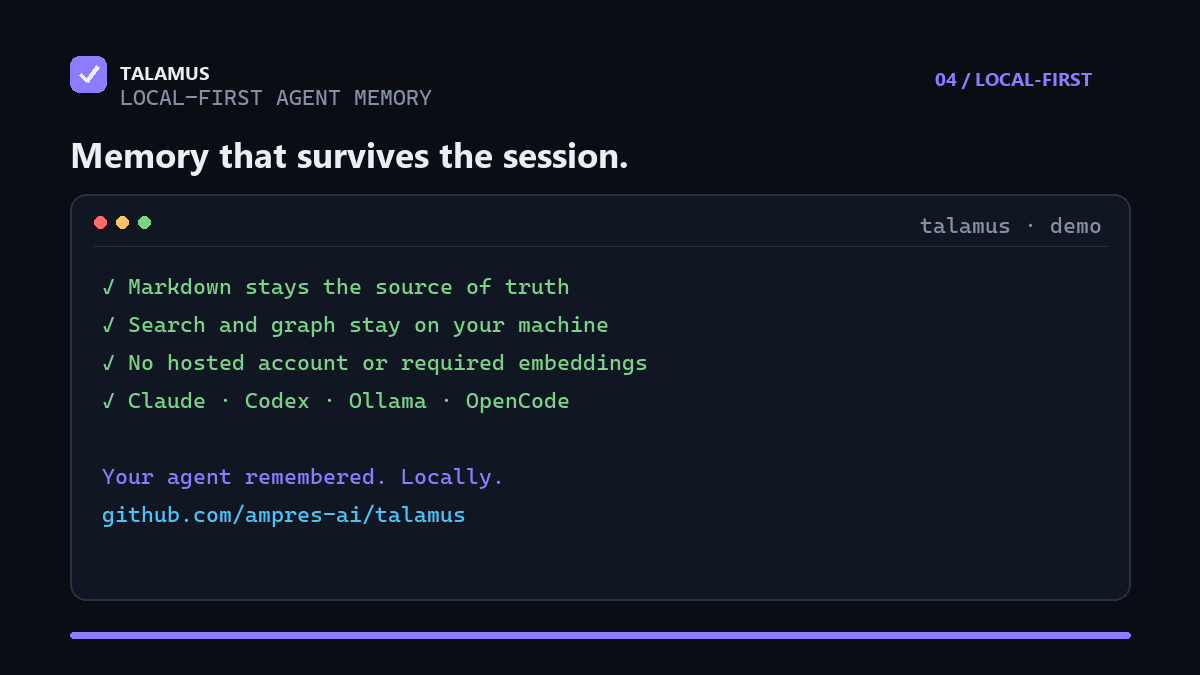
A fresh session asks what happened and gets an answer from real notes, with sources.
talamus recall "why did we choose FTS5?" talamus ask "why did we choose FTS5?" -
Reproduce the scripted demo without spending LLM calls, or run it with your real engine.
python scripts/demo/run_magic.py --fake
python scripts/demo/run_magic.py --keep --engine claude-cli
What is different
TIME: notes have version history, facts have valid-time windows, and talamus ask --as-of 2026-01 answers from the brain as it was.
MEANING: the ontology is induced from evidence, versioned, promoted by measured rules, and used to cluster and route the brain.
VERIFIABILITY: every note carries provenance; talamus verify proposes corrections to review, and answers cite the notes they used.
Measured comparison
The one-screen benchmark is rendered in the
benchmark guide and committed
as one-screen.md.
Every number below traces to a
committed result artifact.
| corpus | metric | Talamus | BM25 | MiniLM vector DB |
|---|---|---|---|---|
| SciFact, English-only turf | recall@10 | 0.797 | 0.776 | 0.783 |
| SciFact, English-only turf | nDCG | 0.664 | 0.652 | 0.645 |
| Book, cross-language + vague | hit@10 | 0.971 | 0.829 | 0.743 |
| Book, cross-language + vague | recall@10 | 0.929 | 0.771 | 0.700 |
Also measured in committed artifacts: −97.7% tokens per answer versus loading the brain into context, refusal 1.000 on out-of-scope questions, and search latency p95 72.6 ms at 10k notes / p50 624 ms at 100k.
The honest part: retrieval quality tracks the LLM you bring. With a strong expansion engine, talamus-smart leads a strong multilingual dense model (multilingual-e5) on every metric including ranking (nDCG 0.847 vs 0.837); with a weak or free one, e5 leads ranking while Talamus keeps the best hit/recall — and on a slow local engine, plain search beats --smart outright. Every number traces to a committed artifact; the losses stay on the table.
Engines
Bring the LLM you already have: claude-cli, codex-cli, antigravity-cli (agy), opencode, ollama, or anthropic-api.
Quickstart
pipx install "talamus[mcp]"
talamus setup
talamus ingest ./notes && talamus ask "what should I remember?"
Run talamus for the status dashboard, talamus quickstart for essential commands, or talamus ui for the local React workbench.
Agent MCP connections are read-only by default. To let an agent deliberately
update this project brain, regenerate its configuration with talamus mcp install --enable-writes; central-brain writes require the additional
--enable-central-writes flag.
Install the consent-aware Talamus agent skill from skills.sh:
npx skills add ampres-ai/talamus --skill talamus-memory
OpenClaw can install the same standalone skill directly from ClawHub:
openclaw skills install @ampres-ai/talamus-memory
Installing the standalone skill does not install Talamus automatically. If the CLI is missing, the skill explains the isolated installation choices and asks before running one.
Gemini CLI can install Talamus directly from its extension gallery or from this
repository. The extension starts the pinned PyPI release through uvx, so it
does not modify the cloned source tree:
gemini extensions install https://github.com/ampres-ai/talamus --auto-update
goose can install the repository as an Open Plugin. This adds the consent-aware memory skill and starts the pinned local MCP server for each new CLI session:
goose plugin install https://github.com/ampres-ai/talamus.git
The plugin requires uv on PATH; uvx downloads Talamus and its MCP
dependencies into an isolated cache on first use.
Containerized MCP (the brain remains in the mounted local folder):
docker run --rm -i -v "$PWD:/data" ghcr.io/ampres-ai/talamus:1.1.3
Links
Docs: quickstart, local-first agent memory, agent install guide, commands, agent tool calling, configuration, benchmarks, architecture, design principles, evaluation, multi-brain, ontology.
Project: security, contributing, roadmap, changelog.
Source code, issue tracking, and release history live at ampres-ai/talamus.
Development
pip install -e ".[dev,mcp]"
python dev.py
python dev.py runs ruff, format check, mypy, and unittest. Product behavior changes should update user docs in the same change.
License
Apache-2.0.
Comments
New to MCP?
From what the protocol is to installing your first server, these answers cover most first questions.
An open protocol that defines how AI applications connect to external tools and data in a uniform way. Clients talk to the model; MCP servers provide tools, resources and prompt templates. They exchange standard messages, so one server can be reused by many clients.