About poordjaevin
poordjaevin is a local-first decision layer for AI engineers and QA engineers, offering typed answers with confidence scores. It supports local NLI and Devin ACP backends, with an MCP server for agent decisions.
Key features
- 01Typed classification, scoring, and yes/no decisions
- 02Batched questions in one model pass
- 03Calibrated confidence with source labels
- 04Local offline NLI backend
- 05CLI, Python library, and MCP server
Use cases
- 01Classify and route support tickets
- 02Gate risky agent actions
- 03Score text on an ordinal scale
MCP support
Its MCP server exposes tools for gating, judging, classifying, rating, and answering typed questions. Backends include Devin ACP, VS Code LM, and offline NLI.
Configuration
Local server config is the same for every client. Copy it into your client’s MCP config file.
uvx poordjaevinPOORDJAEVIN_BACKENDBackend: 'acp' (Devin's own model), 'local' (offline NLI) or 'auto'Local servers need a runtime on your machine (e.g. Node.js 18+). Config file locations differ by client; see your client’s docs.
Tools
Local servers expose tools only once running on your machine, and the maintainer has not provided a tool list.
Details
From the project README





Part of the DEVIN ecosystem
Track: Control · Nature: product
For: AI engineers, QA engineers
Interface: CLI / Python library / MCP server / Bridge
Path: QA engineers · step 3/3 — afterdevin-evals
Where this fits
- Job: Control
- Product:
devin-judge - Packages:
poordjaevin - Mode: read-only
- Ecosystem:
awesome-devin· registry:devin-powerups
poordjaevin
Renamed (Oct 2026): this repository moved from Icaro0310/poordjaevin to Icaro0310/devin-judge. The PyPI package, console script and MCP registry name stay poordjaevin; stars, issues and history are preserved by the redirect.
The poor man's Jev. An open source, local-first "System One" decision layer for LLM apps: typed decisions with provably calibrated confidence. No API key. No waitlist.


Community project. Not affiliated with, endorsed by, or sponsored by Cognition AI. "Devin" is a trademark of Cognition AI.
Linux · Personal Windows · Corporate Windows
Part of the awesome-devin ecosystem: the curated hub for the devin-* tools.
Your model's 0.9 is a vibe. poordjaevin's 0.9 is a measurement.
Every LLM-in-JSON-mode hands you a confidence score and hopes you don't check it. poordjaevin checks it. On the shipped eval set it cuts calibration error (ECE) from 0.156 to 0.072 with zero loss of accuracy, and it runs on your laptop with no API key.
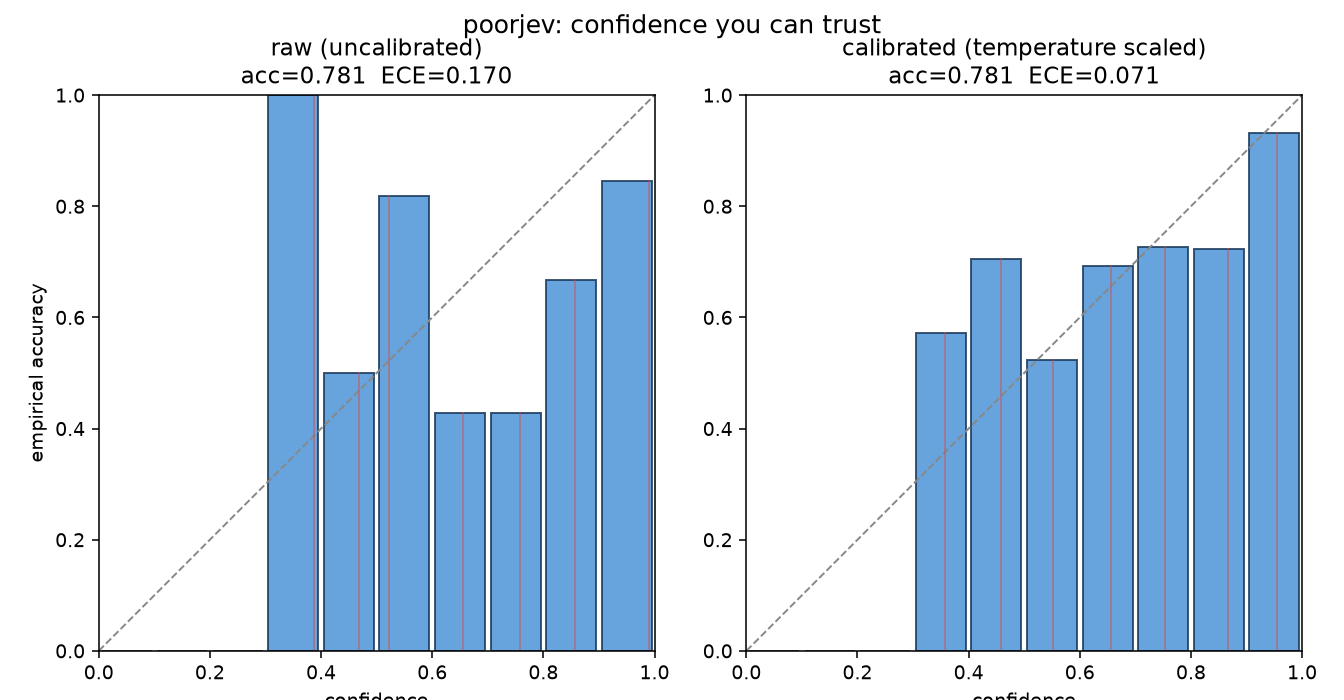
Left: raw confidences, overconfident. Right: calibrated, a stated 0.8 really is right about 80% of the time.
Quickstart
# Linux / macOS
pip install "poordjaevin[local]"
# Windows (PowerShell)
py -m pip install "poordjaevin[local]"
[local] pulls torch + transformers for the offline NLI backend. If you only
plan to use the Devin ACP backend (poordjaevin serve default), a plain
pip install poordjaevin is enough. To install the development version
straight from GitHub, append @ git+https://github.com/Icaro0310/devin-judge.git
to the package spec.
from poordjaevin import Client, Choice, Score, Noul

client = Client()  # local model, no key, offline after one download

result = client.ask(
    state="I've emailed three times and I'm STILL being double-charged. Cancel my account today.",
    questions={
        "topic":        Choice(["billing", "technical", "account", "shipping", "other"]),
        "frustration":  Score(levels=["low", "medium", "high"]),
        "is_urgent":    Noul("The customer needs a response today."),
        "wants_cancel": Noul("The customer wants to cancel their account."),
    },
)

result["topic"].value          # "billing"      always one of your options, by construction
result["topic"].confidence     # 0.86           calibrated, not a vibe
result["frustration"].value    # "high"
result["is_urgent"].value      # True
result["wants_cancel"].value   # True
One call, one model pass, four typed answers. No prompt engineering, no JSON parsing, no "the model returned prose."
Use it with Devin (MCP server, Devin-only)
poordjaevin ships an MCP server, so Devin (or any MCP client) can make fast, calibrated decisions as tools. The obvious use: gate a risky tool call before the agent runs it.
This mode needs nothing but Devin. The default backend (acp) talks to
devin acp through a small packaged Node bridge, so every decision is scored
by the model your Devin plan already provides, with automatic model rotation.
No Ollama, no VM, no tunnel, no second API key: the bridge reads the same
credentials.toml the Devin CLI uses.
# Devin users: no local model needed
uv tool install "poordjaevin[mcp]"
or with pipx (alternative):
pipx install "poordjaevin[mcp]"
Add it to your Devin MCP configuration:
{
  "mcpServers": {
    "poordjaevin": { "command": "poordjaevin", "args": ["serve"] }
  }
}
Requirements for the ACP backend: the devin CLI on PATH (or DEVIN_CLI_PATH),
Node.js >= 18 on PATH, and valid Devin credentials at
%APPDATA%\devin\credentials.toml (Windows) or
~/.local/share/devin/credentials.toml (Linux, override with
DEVIN_CREDENTIALS_PATH).
Backend selection and tuning, all optional:
| Variable | Default | Meaning |
|---|---|---|
POORDJAEVIN_BACKEND | acp | acp = Devin's model via ACP, vscode-lm = VS Code's model via the LM API, nli = fully offline local model |
POORDJAEVIN_ACP_MODEL | auto | pin a specific Devin model instead of automatic rotation |
POORDJAEVIN_ACP_TIMEOUT | 120 | seconds per decision round trip |
POORDJAEVIN_ACP_MAX_COST | unset | fail closed when cumulative ACP cost exceeds this budget |
POORDJAEVIN_VSCODE_LM_ENDPOINT | auto | endpoint file path or direct http(s):// URL override |
POORDJAEVIN_VSCODE_LM_TIMEOUT | 120 | seconds per request to the extension endpoint |
POORDJAEVIN_VSCODE_LM_FALLBACK | unset | nli = fall back to the local model when the extension is unavailable |
POORDJAEVIN_ABSTAIN | off | on = abstain below the calibrated threshold instead of answering |
Honesty note: with acp and vscode-lm the confidence is self_report (the
model's own stated probability, temperature-adjusted), not NLI logprobs. Every
tool response carries a confidence_source field so callers never mistake one
for the other, and model/cost are logged per call for quota monitoring.
The vscode-lm backend scores through whichever chat model VS Code is
serving (Copilot, Codex, BYOK). vscode.lm only exists inside the extension
host, so the icaro0310.judge extension serves a small localhost
endpoint and advertises it via vscode-lm-endpoint.json in the platform data
dir (next to djaevin_log.db). If the extension is not running the backend
fails closed, or falls back to nli when POORDJAEVIN_VSCODE_LM_FALLBACK=nli.
No Devin on the machine? Use the offline path:
uv tool install "poordjaevin[local,mcp]"
or with pipx (alternative):
pipx install "poordjaevin[local,mcp]"
POORDJAEVIN_BACKEND=nli poordjaevin serve # ~400MB one-time model download, then offline
The server also works with Claude Code/Desktop (claude mcp add poordjaevin -- poordjaevin serve), same JSON config shape.
The agent then has these local tools:
| Tool | What it does |
|---|---|
gate(action) | guardrail: should this action be blocked (moves money, deletes data)? |
judge(text, statement) | a yes/no question, with calibrated P(true) |
classify(text, options) | pick one option, with calibrated confidence |
rate(text, levels) | an ordinal score (low / medium / high) |
decide(text, questions) | several typed questions at once, one pass |
Why this beats asking an LLM to judge: on the default NLI backend it is local
(private), free (no tokens), fast, and the confidence is calibrated instead of
made up. On acp or vscode-lm your scoring text goes to whichever model
provider you picked; the confidence stays honestly labeled via
confidence_source, calibrated when a matching calibrator is loaded and raw
otherwise.
Gate your commits (pre-commit hook)
The repo ships a pre-commit hook that runs
poordjaevin gate on an action file before every commit:
# .pre-commit-config.yaml (in the repo you want to protect)
- repo: https://github.com/Icaro0310/devin-judge
  # the hook manifest ships in v0.1.2+; use a tag once cut
  rev: main
  hooks:
    - id: devin-judge-gate
      # optional: point the gate at your own action file
      # args: [--action-file, path/to/action.txt]
Setup is required: the hook fails closed. Without the action file every commit exits 2, so create it once:
mkdir -p .devin
echo "The risky action this commit performs." > .devin/judge-action.txt
Two details worth knowing: pre-commit appends args after the flag
already embedded in entry, so repeat --action-file to override the
default path. And the hook runs on every commit (always_run,
pass_filenames: false), so it needs a working backend: the acp
default, or POORDJAEVIN_BACKEND=nli with the local extra installed.
Why poordjaevin exists
Most production AI work is not chat. It is fast structured decisions: route a ticket, classify an intent, score a sentiment, extract a field, gate a tool call. TypeSafe's Jev named this category ("System One" models) and nailed the thesis — and, per the independent cross-system benchmark below, it currently backs its calibration claims up: it's the strongest model measured here. It's also closed, hosted, and behind a waitlist.
poordjaevin exists for the deployments where "call a hosted API" isn't the answer: private data, offline environments, zero marginal cost, no waitlist. It reproduces Jev's typed-decision interface on a small local model and proves its own calibration honestly (5-fold cross-validated, never graded on what it was fit on). Against the other open local alternatives it leads on the mixed decision-primitive benchmark below, but not on the high-cardinality one, see the real breakdown. It does not beat Jev. That's the honest trade for fully local and free on the NLI backend.
poordjaevin vs the field
Independently measured, not self-reported — see crossbench/ for the full harness, data, and every raw result file.
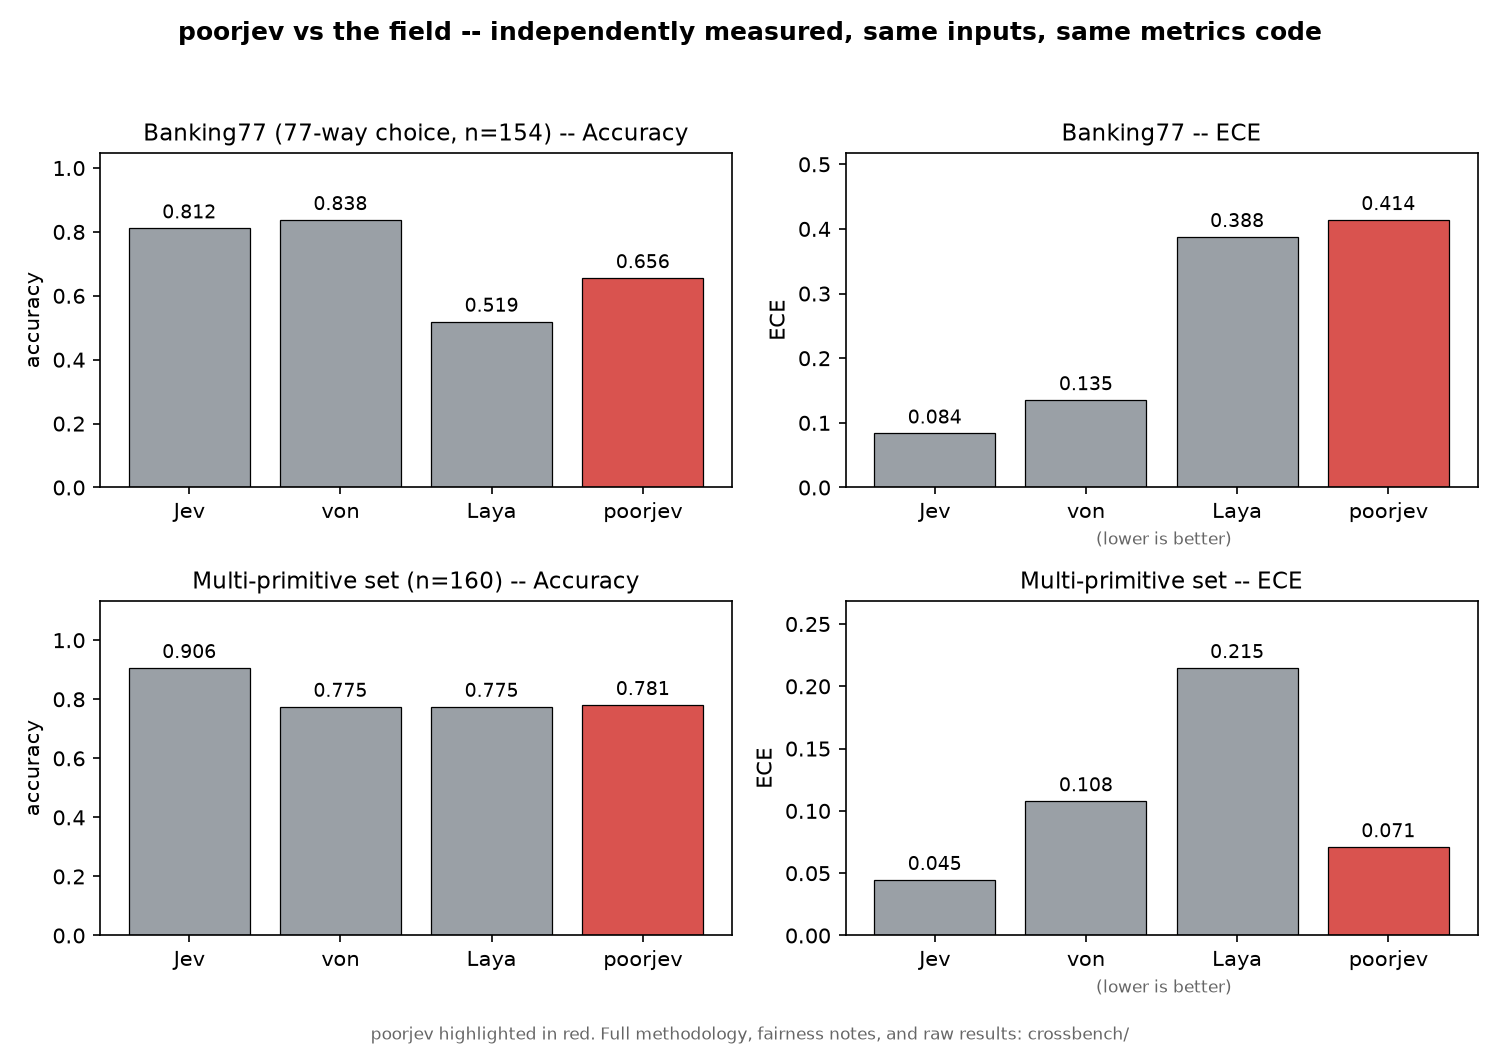
poordjaevin in red. Chart regenerates from crossbench/results/ via crossbench/plot_comparison.py — same numbers as the table below.
| Jev (TypeSafe) | von | Laya | poordjaevin | |
|---|---|---|---|---|
| Interface (typed questions, one pass) | yes | yes | yes | yes |
| Runs locally, no API key | no | yes | yes | yes |
| Your data stays in your environment | no | yes | yes | yes |
| Waitlist / signup | yes | no | no | no |
| Open source | no | yes (Apache-2.0) | yes (Apache-2.0) | yes (MIT) |
| Accuracy, Banking77 (77-way, n=154) | 0.812 | 0.838 | 0.519 | 0.656 |
| ECE, Banking77 (lower better) | 0.084 | 0.135 | 0.388 | 0.414 |
| Accuracy, multi-primitive set (n=160) | 0.906 | 0.775 | 0.775 | 0.781 |
| ECE, multi-primitive set (lower better) | 0.045 | 0.108 | 0.215 | 0.071 |
The multi-primitive rows were measured on the 55-item / 160-decision
snapshot of evalset/tasks.jsonl; the shipped set has since grown to 70
items / 203 decisions (see evalset/README.md). Banking77 numbers are
unaffected; a full four-system re-run on the grown set has not been done.
Read straight, because that's the point of doing this:
- Jev wins the multi-primitive set outright — best accuracy and best calibration, no caveats.
vonwins Banking77 — best accuracy of all four systems (0.838, ahead of even Jev's 0.812), though Jev still calibrates better there (0.084 vs 0.135).- poordjaevin leads the open, local options on the multi-primitive set — best
accuracy and best calibration among Laya/
von/poordjaevin there. That does not carry over to Banking77:vonbeats poordjaevin on accuracy by a wide margin (0.838 vs 0.656), and poordjaevin has the worst calibration of all four systems there (0.414 — even behind Laya's 0.388), not the best.
Nobody sweeps, and poordjaevin specifically does not sweep the open-source field —
it wins one benchmark and loses the other, to von, decisively. Full
methodology, fairness notes, and every raw result file are in
crossbench/ — reproducible for a few cents of Jev API calls
and some CPU time.
poordjaevin is not a Jev clone and makes no claim to beat it, or to beat von
across the board. It reproduces the interface, proves its own calibration
with numbers instead of marketing copy, and is the strongest fully local
option on the mixed decision-primitive benchmark — not on high-cardinality
classification, where von currently leads.
The three primitives
| Primitive | Use it for | Returns |
|---|---|---|
Choice(options) | classification, routing | winning option, per-option probabilities, calibrated confidence |
Score(levels) | ordinal rating, severity | winning level, a continuous score on the scale, confidence |
Noul(statement) | yes/no gates, guardrails | P(true), thresholded to a bool |
The returned value is always drawn from the set you declared. An invalid category is structurally impossible, not "usually avoided." This is tested against adversarial inputs (NaN, infinity, negatives, all-zero score vectors).
How it works
state + typed questions
        |
        v
   one batched pass through a local zero-shot NLI model   (no API key)
        |
        v
   raw probabilities per option
        |
        v
   calibration: temperature scaling + conformal abstention
        |
        v
   typed, schema-valid answers + calibrated confidence
- Local NLI backend (fully offline): one small natural-language-inference model scores every option as an entailment hypothesis, in a single batched forward pass. Fully offline after a one-time ~400MB download. No key, no vendor, your text never leaves your machine. This is the backend used by
poordjaevin eval/calibrateand byClient()in Python; select it forservewithPOORDJAEVIN_BACKEND=nli. - Devin ACP backend (default for
poordjaevin serve): routes scoring throughdevin acp, so decisions use the model your Devin plan already provides, with automatic rotation and per-call cost reporting. No extra model, no extra key. - VS Code LM backend: routes scoring through
vscode.lminside theicaro0310.judgeextension, so decisions use whichever chat model VS Code is already serving (Copilot, Codex, BYOK), with no extra key. Select it withPOORDJAEVIN_BACKEND=vscode-lm. - Calibration (the moat): temperature scaling fits one scalar so predicted confidence matches real accuracy; conformal thresholding turns a target risk budget into an "I don't know, escalate" signal. Calibration is backend-specific: a calibrator fitted on the NLI backend is not applied to ACP scores (the server warns and falls back to raw confidence on a mismatch).
Benchmarks
Reproduce everything with two commands:
poordjaevin eval       --set evalset/tasks.jsonl          # accuracy, ECE, Brier, risk-coverage
poordjaevin calibrate  --set evalset/tasks.jsonl --plots  # before/after ECE + the diagrams
On the shipped eval set (70 hand-labelled items, 203 decisions), local NLI backend, keyless:
| Metric | Raw | Calibrated |
|---|---|---|
| Accuracy | 0.793 | 0.793 |
| ECE (calibration error) | 0.156 | 0.072 |
| Brier | 0.173 | lower |
| Temperature | 1.00 | 2.59 |
Temperature is fit by 5-fold cross-validation, so the "after" number is measured on held-out data, never on data it was fit on. Full tables and the honest limitations are in RESULTS.md.
Against Jev, Laya, and von, on the same inputs, same metrics code: see poordjaevin vs the field above and the full harness in crossbench/. Short version: poordjaevin leads the open options on this mixed decision-primitive benchmark, von leads on high-cardinality classification, Jev leads overall.
Selective prediction: it knows when it doesn't know
Set a risk budget and poordjaevin abstains on its least confident decisions instead of guessing:
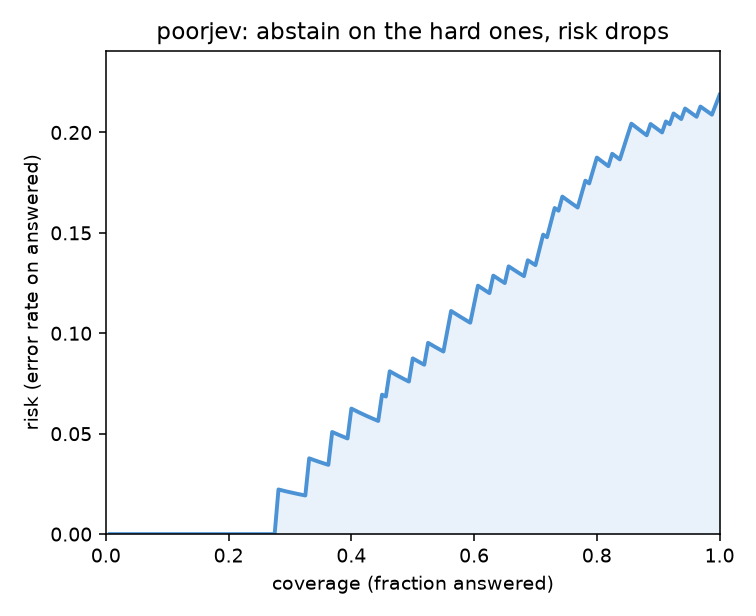
At a 10% error budget it confidently answers 64% of decisions and escalates the rest. That is the natural bridge from System One (fast automatic answer) to System Two (a human, or a bigger model).
Real examples
python examples/ticket_router.py   # full triage on a support ticket
python examples/tool_gate.py       # gate a risky tool call before it runs
python examples/demo.py            # raw vs calibrated, side by side
The tool-gate example encodes a practical lesson: the local model is strong at concrete questions ("this action moves money", "this deletes data") and weak at abstract ones ("this is dangerous"). Ask concrete questions and let a one-line rule apply the policy.
Honest limitations
No hype. Here is what this is not.
- Not as fast as Jev. Jev uses a custom model. poordjaevin uses commodity ones. We report latency, we do not market it.
- The eval set is small (tens of items, one labeller, English, support flavoured). Enough to show calibration direction and schema validity, not a leaderboard.
- After-ECE is 0.072, not below 0.05. That is the real cross-validated number, reported as measured. Per-question temperature would likely push it lower.
- The local model is moderately intelligent. It does real semantic entailment, not deep reasoning. Calibration and abstention are what make that safe.
- Jev is currently ahead, measured, not assumed, and so is
vonon one axis. The cross-system benchmark has Jev winning the multi-primitive set outright and leading Banking77 calibration;vonbeats both Jev and poordjaevin on Banking77 accuracy. poordjaevin's honest position is "best fully local/free option on the mixed decision-primitive benchmark," not "beats Jev" and not "beats every open alternative everywhere." - Temperature scaling doesn't fix everything. At Banking77's 77-way cardinality, a proper cross-validated temperature refit barely moves ECE (0.414 → 0.416) — the miscalibration there is structural to the small NLI backend at high option counts, not a scalar you can fit away. See
crossbench/results/banking77_poordjaevin_recalibrated.json.
FAQ
Is this a Jev clone? No. It reproduces Jev's developer interface and its calibrated-confidence guarantee on open, local models. It does not copy Jev's architecture or its speed.
Can I run Jev locally? Not Jev itself, it is closed and hosted. poordjaevin is the local, open-source alternative: it runs the same typed-decision interface on your own machine, offline, with no API key and no waitlist.
Is there an open-source alternative to Jev? Yes, this is one. poordjaevin is MIT-licensed, reproduces Jev's Choice/Score/Noul interface on commodity models, and proves its calibration with reproducible numbers.
Do I need an API key or GPU? No. Two free paths: serve defaults to the ACP backend, which reuses your existing Devin credentials and model; nli runs on CPU, offline, after one model download.
How is this different from an LLM in JSON mode? Two ways. Output is schema-valid by construction, not by parsing. And the confidence is calibrated and proven, not a number the model made up.
What is a "System One" model? A model for fast, automatic, structured decisions (classify, route, score, gate), as opposed to slow, deliberative chat. The name is from Kahneman's System 1 / System 2.
What is ECE? Expected Calibration Error: the average gap between a model's confidence and its actual accuracy. Lower is better. poordjaevin's whole job is to shrink it.
Can I use my own model? Yes. Backends are pluggable; a backend only implements entail_probs(pairs).
Roadmap
- Typed primitives, schema-valid by construction
- Local NLI backend, single pass, keyless
- Eval set + metrics (accuracy, ECE, Brier, risk-coverage)
- Calibration: temperature scaling + conformal abstention
- MCP server: use poordjaevin as local tools in Claude Code
- Independent cross-system benchmark vs Jev, Laya, von (
crossbench/) - Devin ACP backend: LLM scoring through your existing Devin credentials (the intelligence dial)
- Close the Banking77 accuracy/calibration gap to Jev (bigger backend, per-class calibration)
Platform support
Windows, Linux, and macOS. The ACP bridge resolves Devin credentials and the
devin executable per platform:
| Platform | Devin credentials | Devin CLI |
|---|---|---|
| Windows | %APPDATA%\devin\credentials.toml | devin.exe on PATH |
| Linux | $XDG_DATA_HOME/devin/credentials.toml (default ~/.local/share/devin/credentials.toml) | devin on PATH |
| macOS | ~/Library/Application Support/devin/credentials.toml | devin on PATH |
Override either with DEVIN_CREDENTIALS_PATH and DEVIN_CLI_PATH. The
credential file is read only to authenticate the ACP session; it is never
logged or copied.
Contributing
Issues and PRs welcome, especially new labelled decision tasks for the eval set. If you find a case where the confidence is not honest, that is a bug worth filing.
License
MIT. Use it, ship it, sell it.
poordjaevin: poor in price, rich in honesty. If your model's confidence is a vibe, come check it.
If this saved you debugging time, a ⭐ on the repo helps others find it.
Comments
New to MCP?
From what the protocol is to installing your first server, these answers cover most first questions.
An open protocol that defines how AI applications connect to external tools and data in a uniform way. Clients talk to the model; MCP servers provide tools, resources and prompt templates. They exchange standard messages, so one server can be reused by many clients.