About llmxray
LLMxRay is a local observability and diagnostics tool for Ollama users, including developers and agents. It proxies Ollama requests, visualizes prompts and runs, and offers read-only MCP tools for diagnosing call behavior.
Key features
- 01Ollama-compatible request proxy
- 02Live request and cache inspection
- 03Prompt and run visualizations
- 04Shared model and GPU usage views
- 05Local read-only MCP diagnostics
- 06OpenTelemetry trace export
Use cases
- 01Inspecting prompts sent by local AI clients
- 02Finding cache loss or context truncation
- 03Diagnosing an agent's recent Ollama calls
- 04Comparing model-call performance before and after a change
MCP support
LLMxRay provides seven read-only MCP tools for inspecting recent turns, models, prompt estimates, and service status. The MCP server reads from a running LLMxRay instance over localhost.
Configuration
Local server config is the same for every client. Copy it into your client’s MCP config file.
npx -y llmxrayLLMXRAY_URLThe running LLMxRay server the tools read from (start it with `npx llmxray`).OLLAMA_URLThe Ollama daemon, for the list_local_models tool.Local servers need a runtime on your machine (e.g. Node.js 18+). Config file locations differ by client; see your client’s docs.
Tools
3Saved tool list · updated 4d ago
| Parameter | Type | Required | Description |
|---|---|---|---|
| client | string | No | Part of the client label or id as LLMxRay shows it (for example "VS Code Copilot", "python-requests", or the X-LLMxRay-Client header you sent). Case-insensitive substring. Omit for all clients. |
| since_minutes | integer | No | Only turns from the last N minutes. Omit for every turn LLMxRay has kept. |
Details
From the project README
LLMxRay


See what your local AI is actually doing.
Point VS Code Copilot, Open WebUI, Continue, n8n or your own agent at LLMxRay instead of Ollama, and see every turn:
what was cached, what was read again, what the daemon silently cut, which tool evicted which model. No cloud. No API keys. No cost.



🌐 English • Français • 中文 • العربية • Srpski
Quick Start • What your tools send • Send it on • For agents • Also in the box • Who is this for • Install • Ollama compatibility • Changelog
Quick Start
You need Ollama running with at least one model pulled (ollama pull llama3.2). Then:
npx llmxray
Or with Docker:
docker run -p 5174:5174 -p 11435:11435 djovaneli/llmxray
Now point your tools at http://localhost:11435 instead of Ollama's 11434: VS Code Copilot, Open WebUI, Continue, n8n, your own scripts. It behaves exactly like Ollama and forwards everything. Open http://localhost:5174, go to Live, and watch their turns arrive.
Just want to try a model? Open the Chat page, pick one, and send a message.
What your tools really send
Your editor, your agents and your scripts all talk to the same Ollama. These pages show what each of them sends, what the daemon does with it, and what that costs the others.
Live: what your other tools send
LLMxRay opens a second port, 11435, that behaves exactly like Ollama and forwards everything to it. Point VS Code Copilot, Open WebUI, Continue, n8n or your own script at http://localhost:11435 and every turn they send appears here: client, model, prompt size, how much came from the cache, prefill and generation speed, tool calls.
VS Code Copilot ─┐
Open WebUI ──────┤                                    ┌─ Live page: every turn,
Continue / n8n ──┼─► http://localhost:11435 ─► Ollama ┤  cache hits, prefill speed,
your scripts ────┘        (LLMxRay)                   └─ where the cache broke
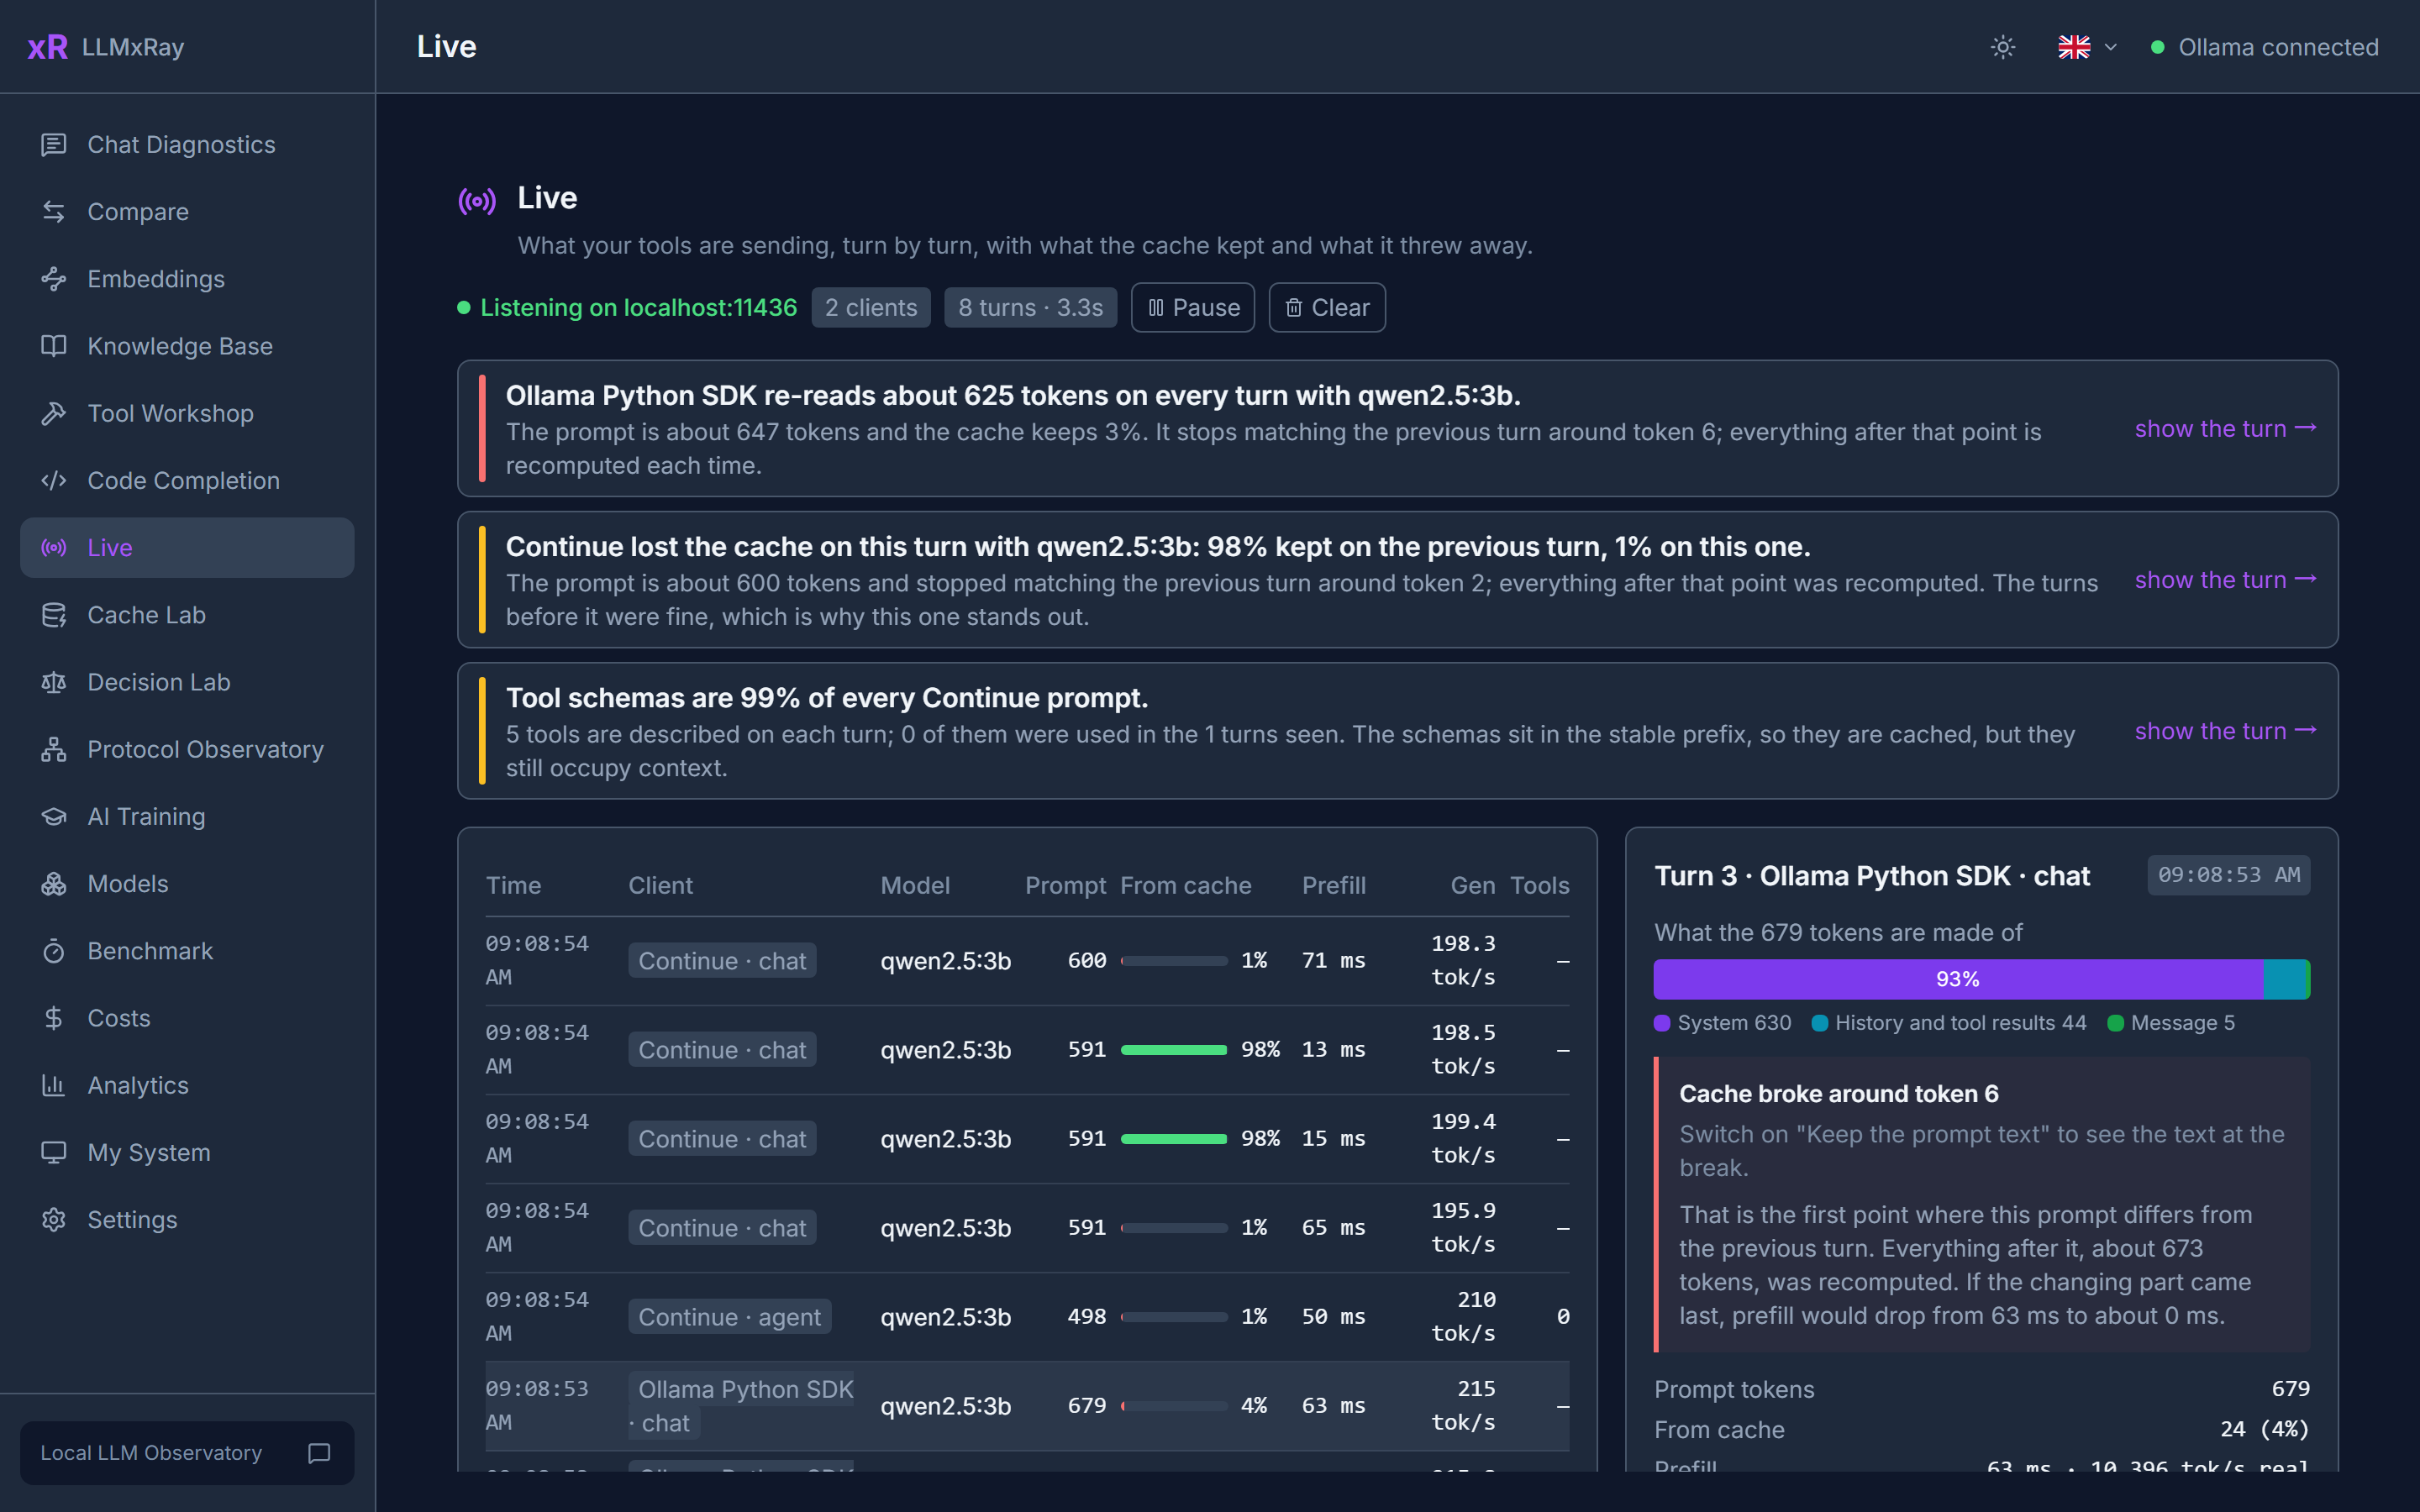
Select a turn to see what the prompt is made of and the exact point where it stopped matching the previous one, which is where the cache broke. Findings are plain sentences, each linked to the turn that proves it: a client re-reading its whole prompt every turn, a prompt the daemon silently cut to fit the context (Ollama keeps the first few tokens and the end, drops the rest, and says nothing), a model running partly on CPU, tool schemas taking 40% of every prompt. Only counts and timings are kept, on this machine for 30 days, so a restart picks up where it stopped. Prompt text is an opt-in that writes to a local file. Nothing leaves your machine unless you send the turns on to your own trace viewer: each model call as an OpenTelemetry span, each run as a trace, for Jaeger, Phoenix, Langfuse or Grafana.
Both ports answer only this machine by default, because the Live log holds whatever your tools sent. Start with npx llmxray --host 0.0.0.0 to let other machines on your network reach them, for a Live page on a second screen or a shared GPU box.
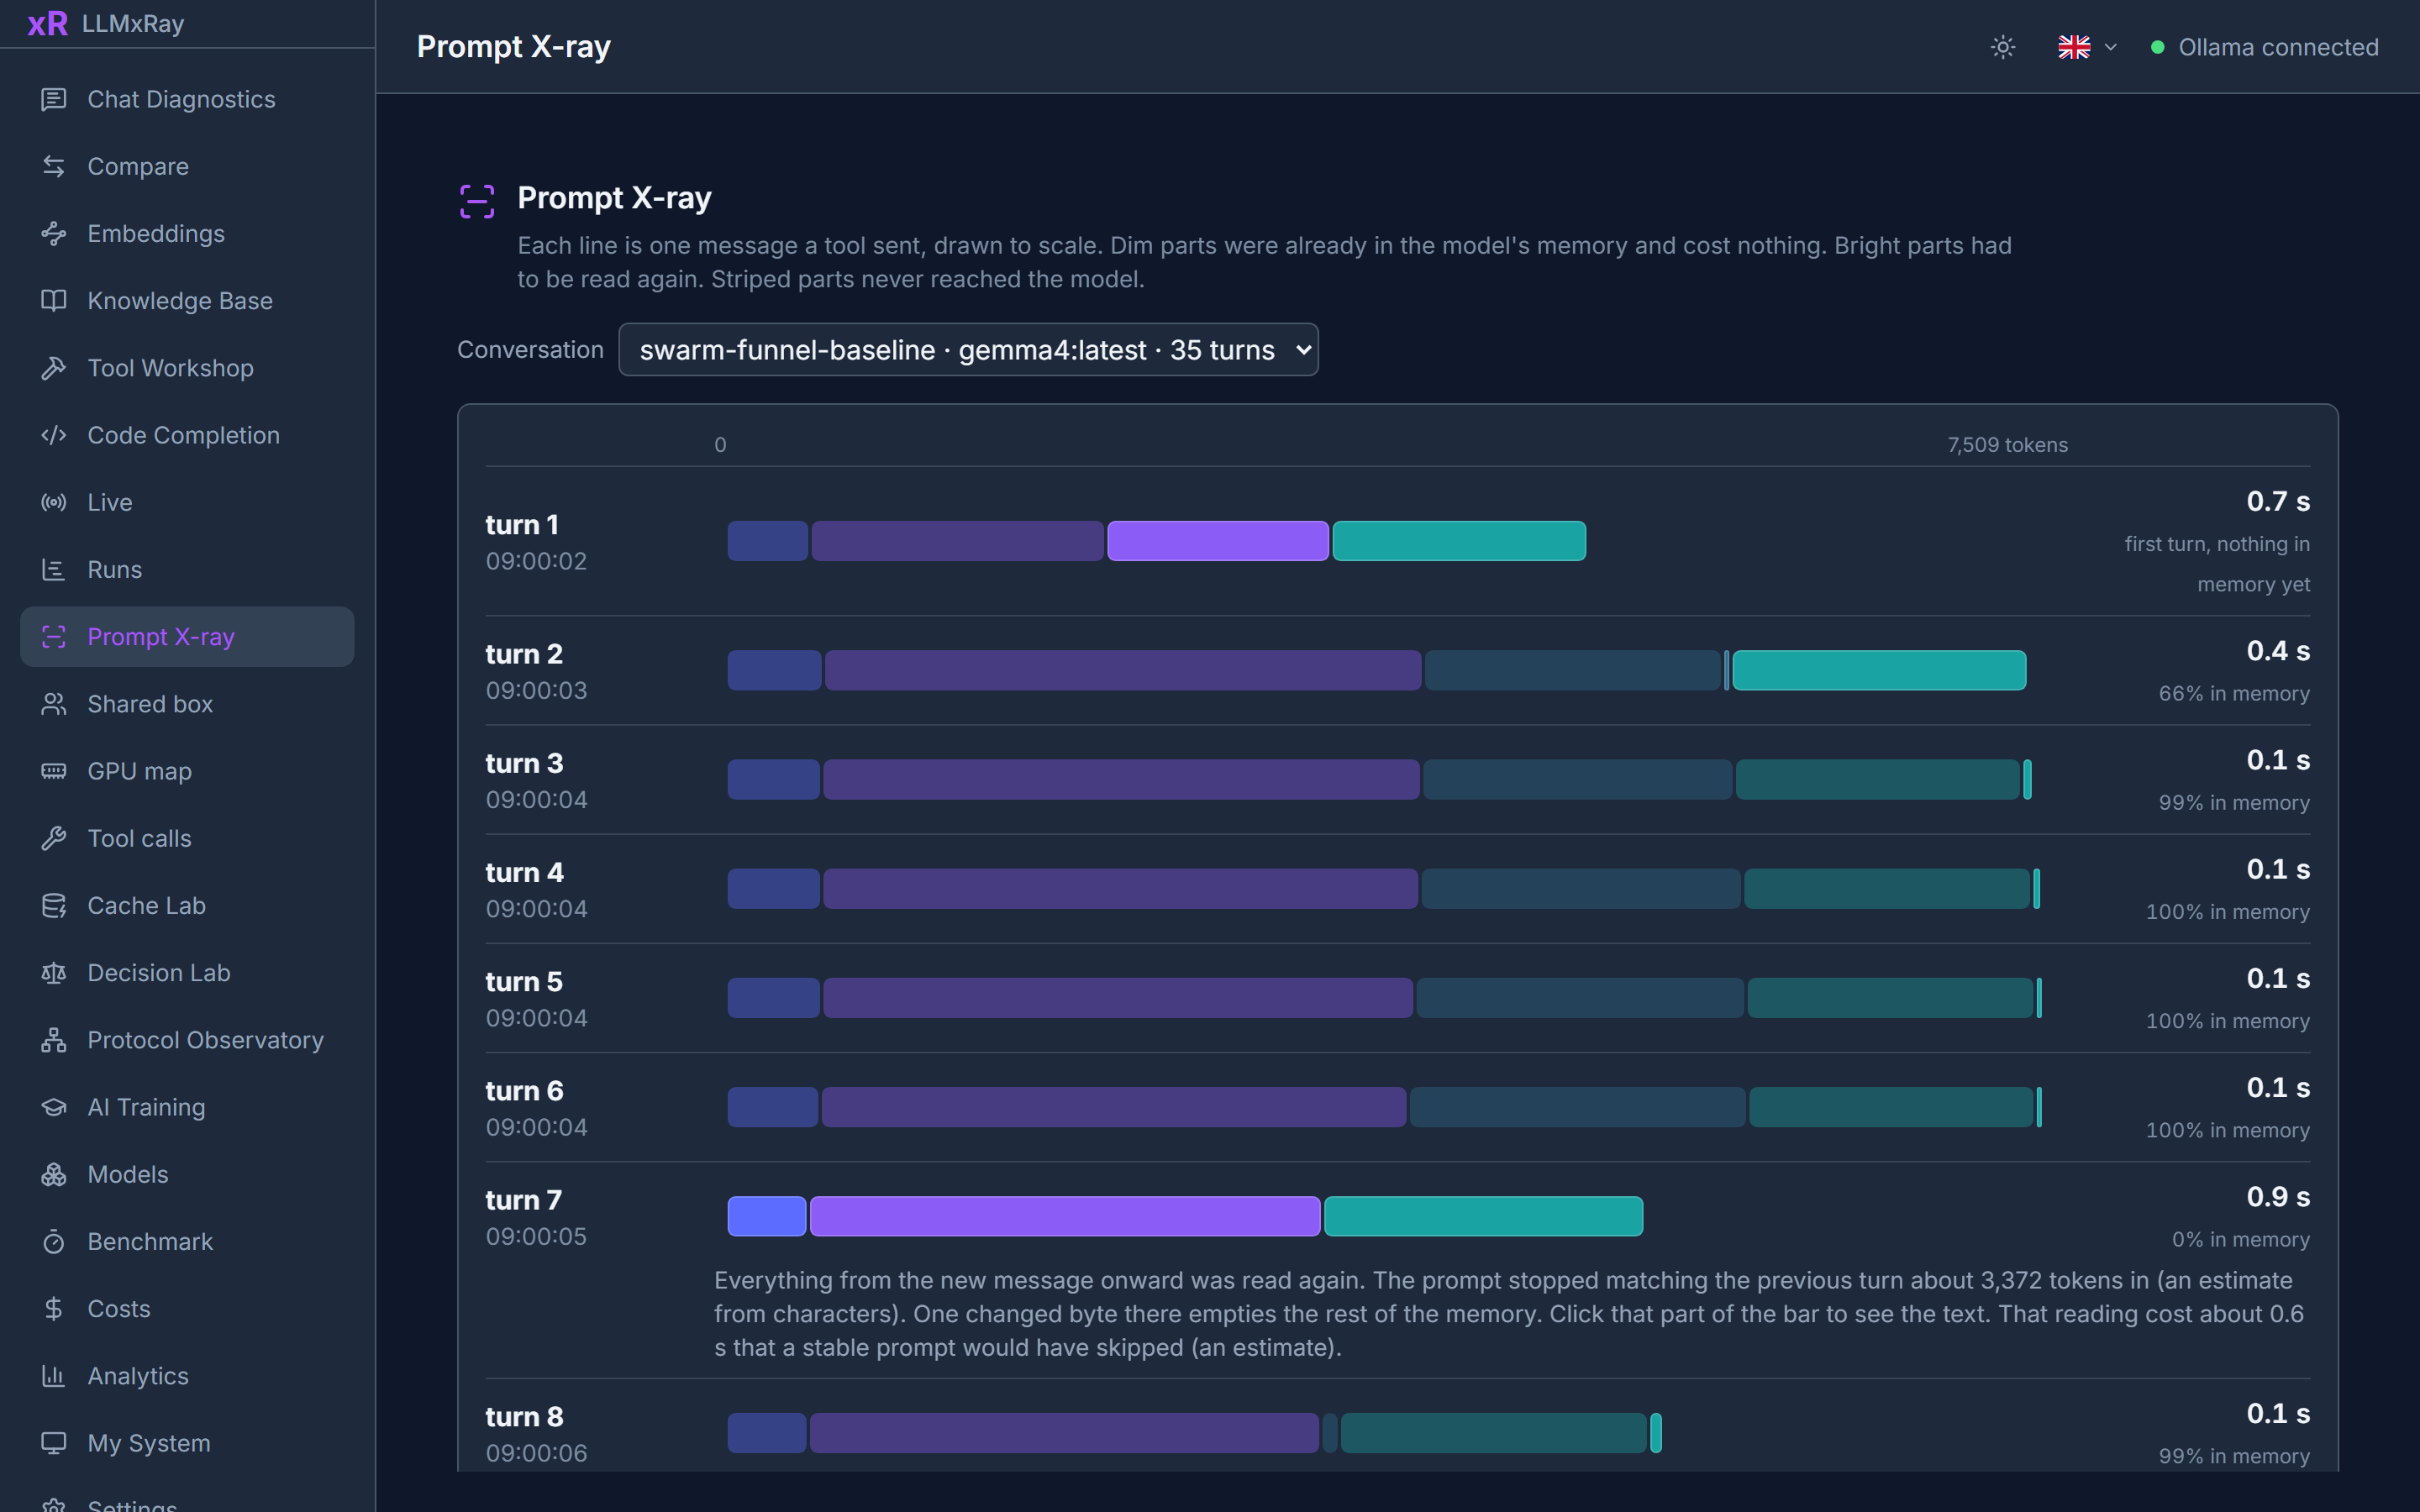
Prompt X-ray: the prompt itself, drawn to scale
Each turn your tool sent, as a bar. Colour is what each part of the prompt was: system prompt, tool schemas, earlier turns, the new message. Brightness is what happened to it: dim was already in the model's memory and cost nothing, bright had to be read again, striped was cut by the daemon and never seen. Stack the turns of a conversation and you watch the cache grow, see the turn where a timestamp in the system prompt emptied it, and the turn where the prompt outgrew the context and Ollama silently dropped the start, system prompt included, and answered anyway. Click a part and the request opens at that place in the text.
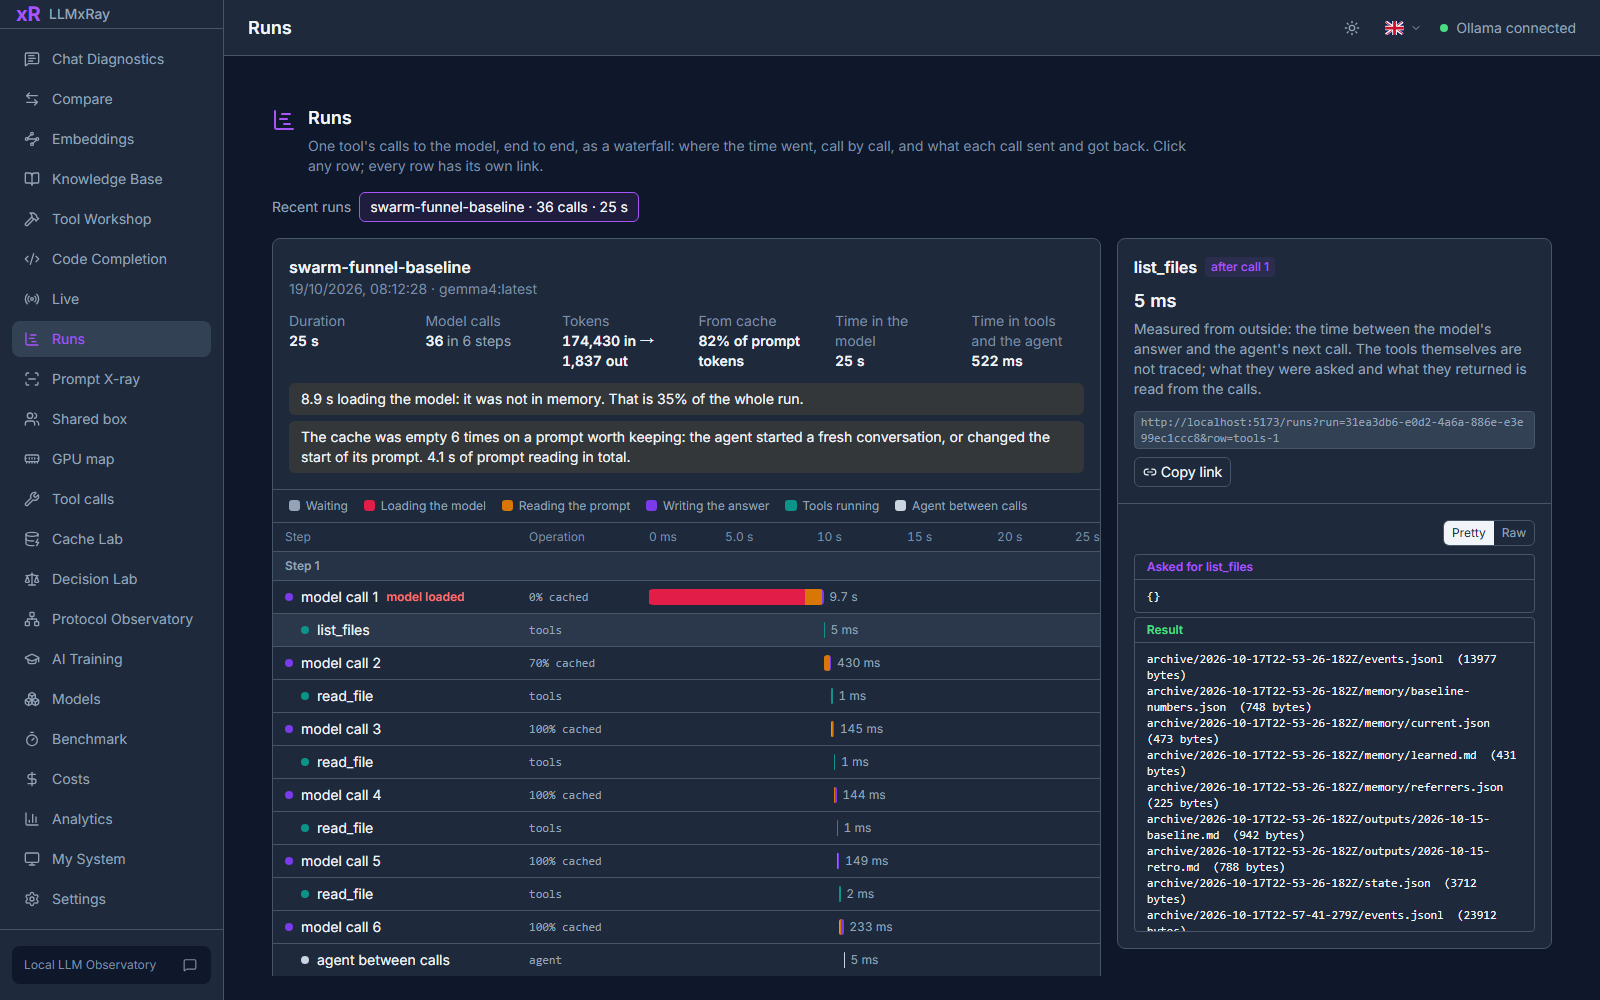
Runs: one tool's work, end to end
One tool's calls to the model laid out in time, as a waterfall. Each call is split into what Ollama reports: waiting, loading the model, reading the prompt, writing the answer. Between calls, the tool's own time, named after the tools the model asked for. Steps start where the tool began a fresh conversation, so an agent that throws its cache away at every step shows it at a glance, and so does a model that was not in memory when the run began. Click any row for what that call sent and what came back, the model's thinking and its tool calls with their arguments included, or for what a tool was asked and what it returned. Every row has its own link. Switch on Keep the prompt text on the Live page to see the text; the timings need nothing.
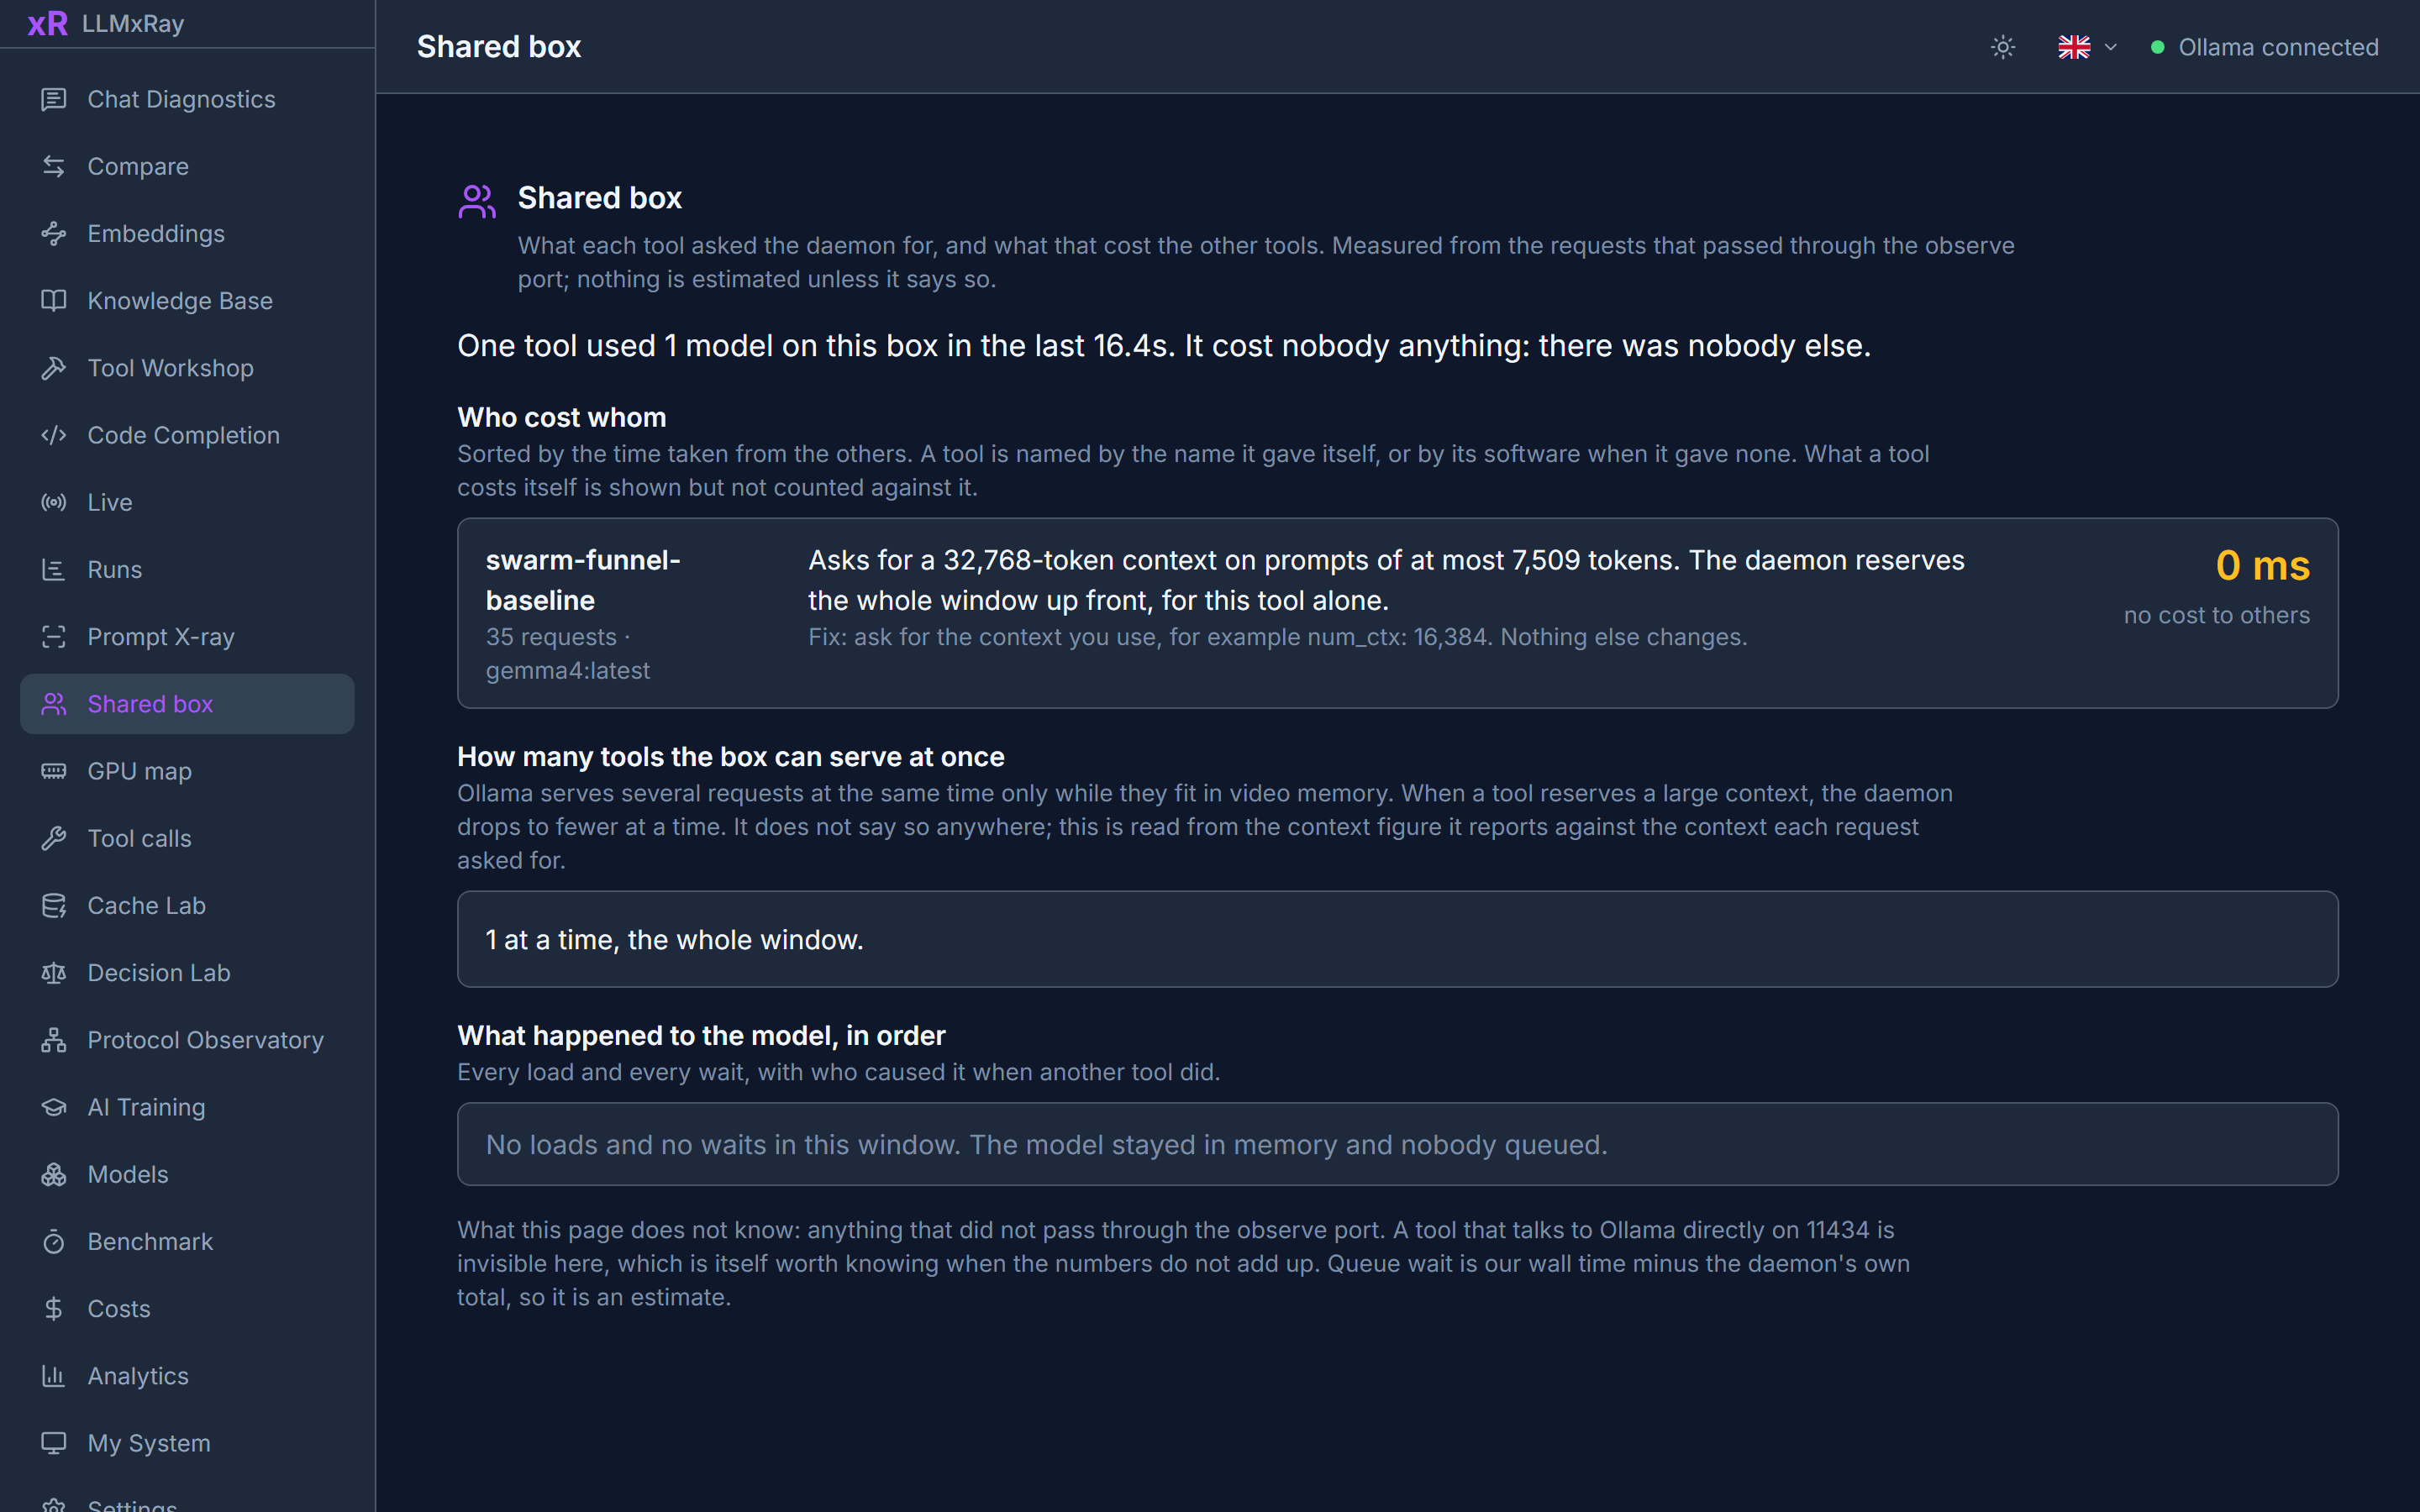
Shared box: why Ollama is slow right now, and which tool did it
One line per tool, sorted by what it cost the others, in seconds: the one that sends keep_alive: 0 and unloads the model after every run, the one that asks for a 128K context on 4K prompts and drops the daemon to one request at a time, the one that waited 22 seconds behind them. Each with the setting to change. A tool that cost nothing is listed too, so you can see what good looks like.
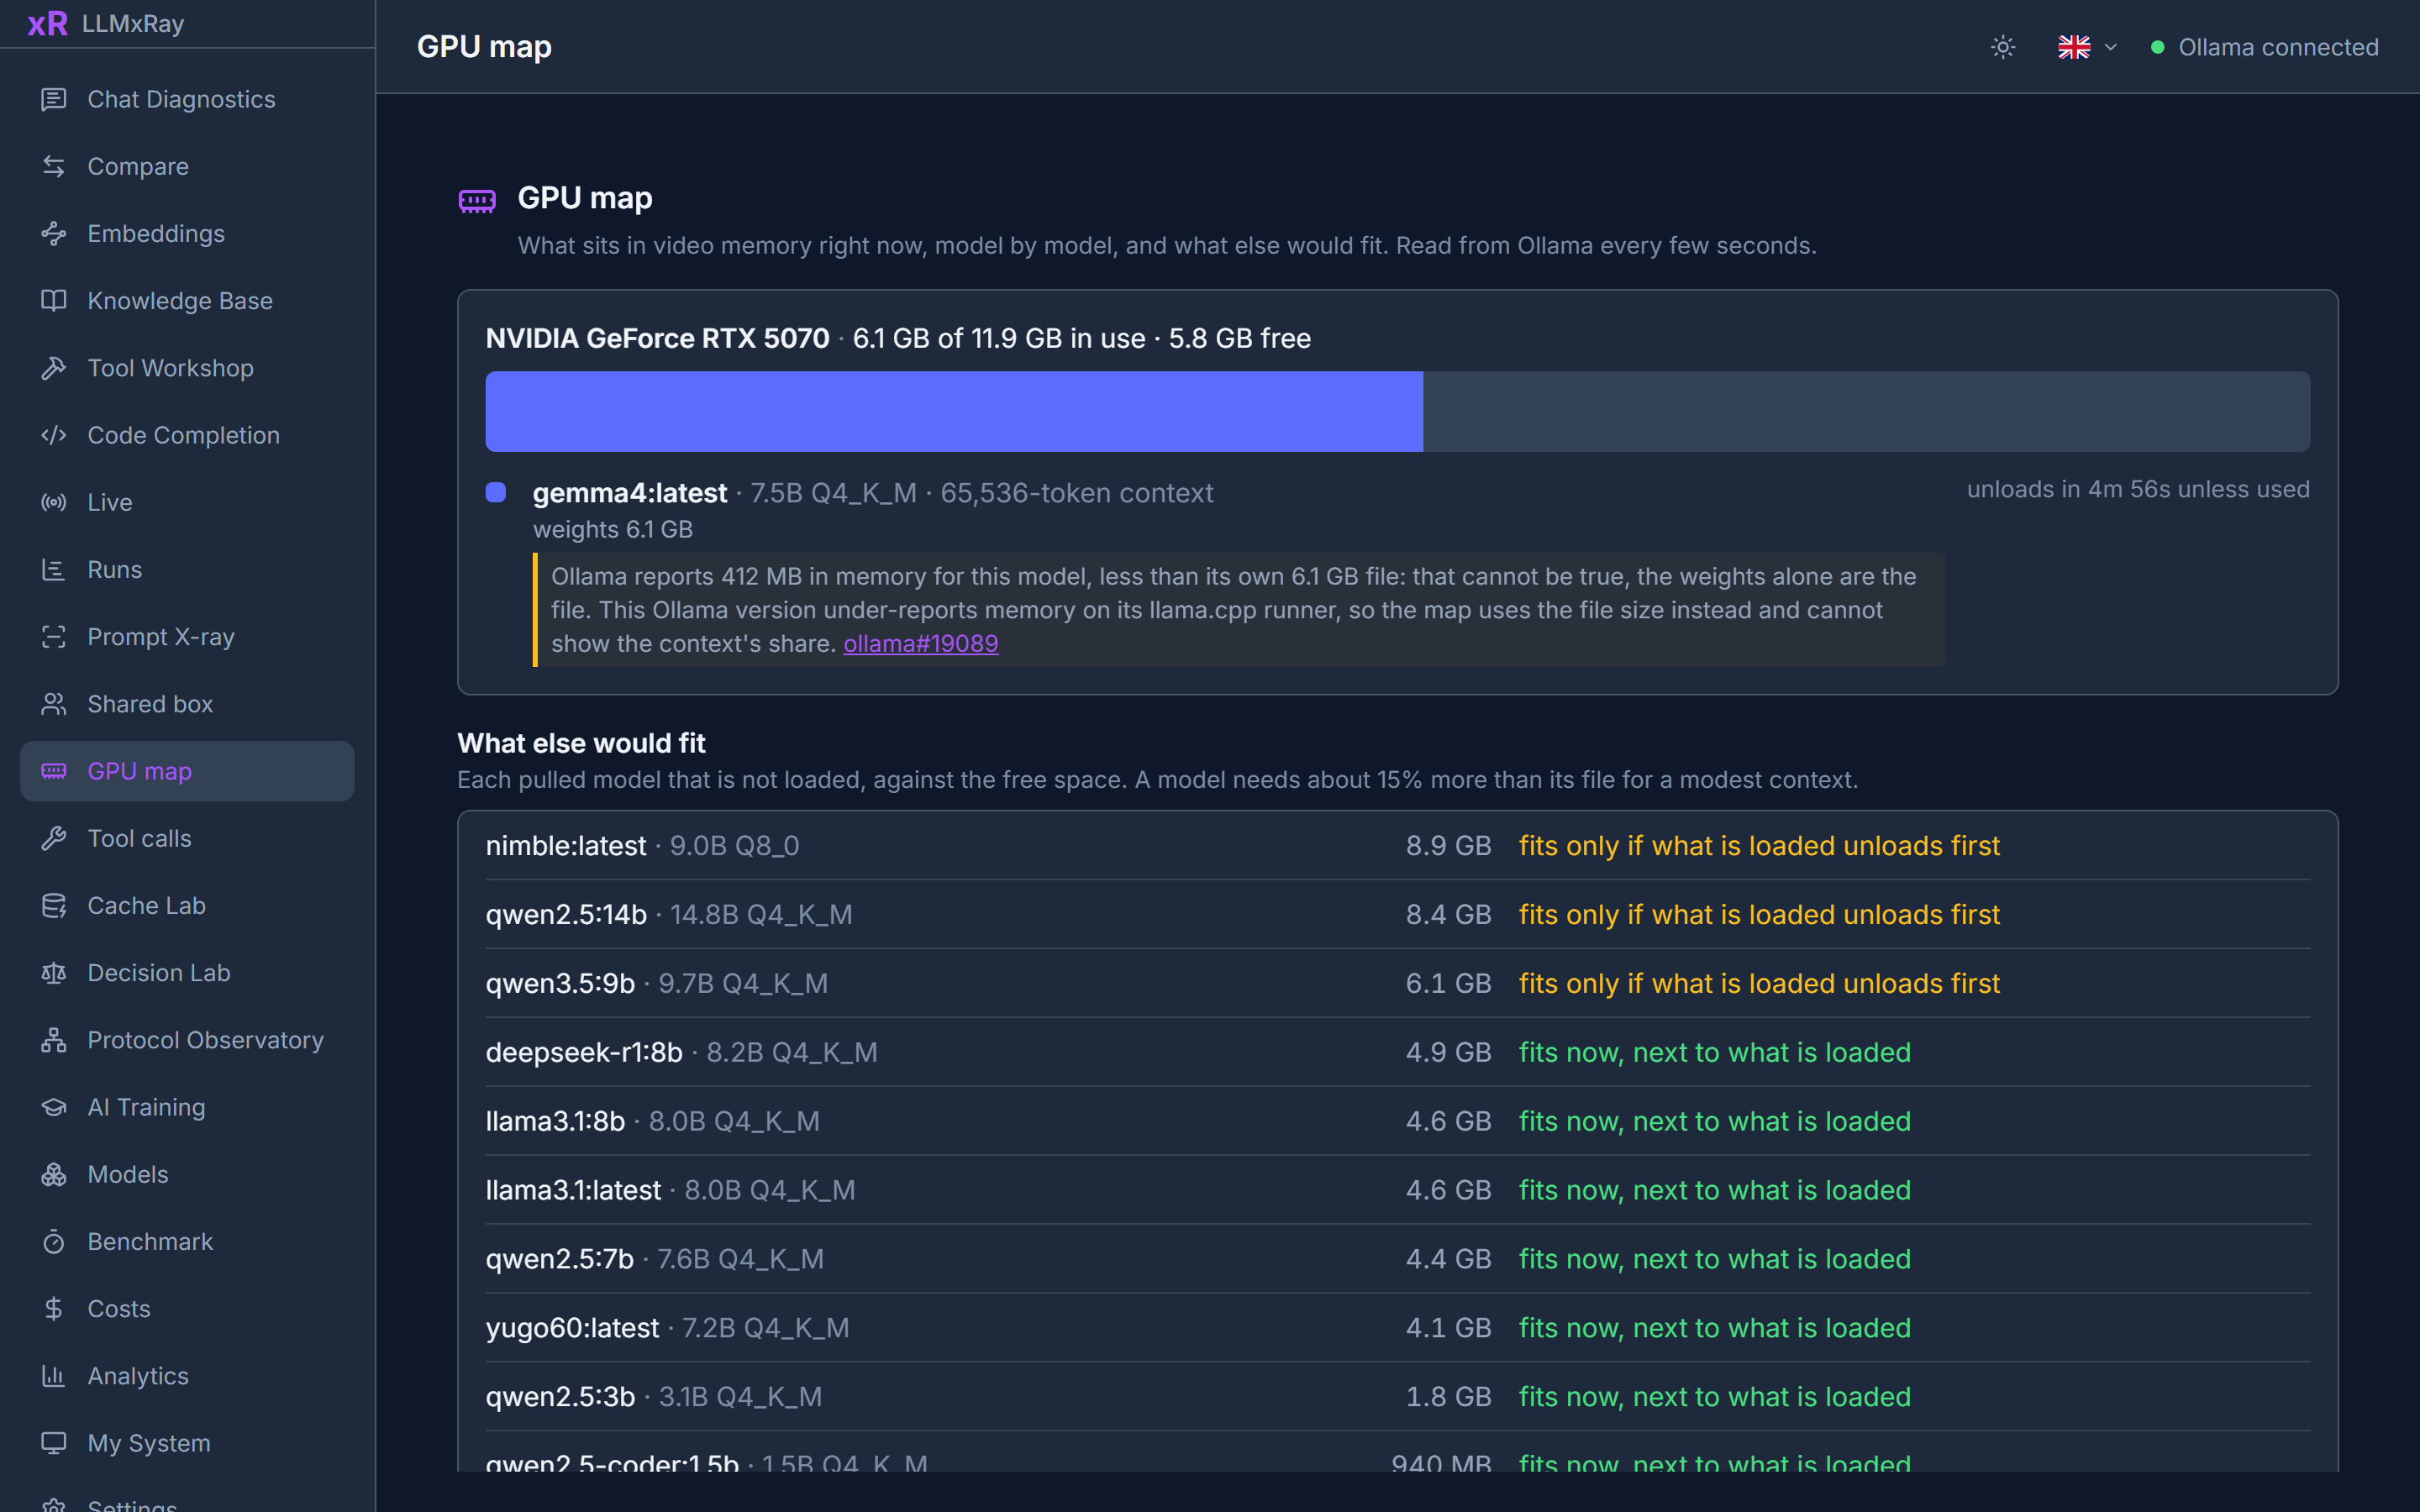
GPU map: what is in video memory, and what else would fit
One bar the width of your card: each loaded model as a block split into its weights and what its context costs on top, then the free space. Under it, every pulled model with one of three verdicts: fits now, fits only if what is loaded unloads first, larger than the card.
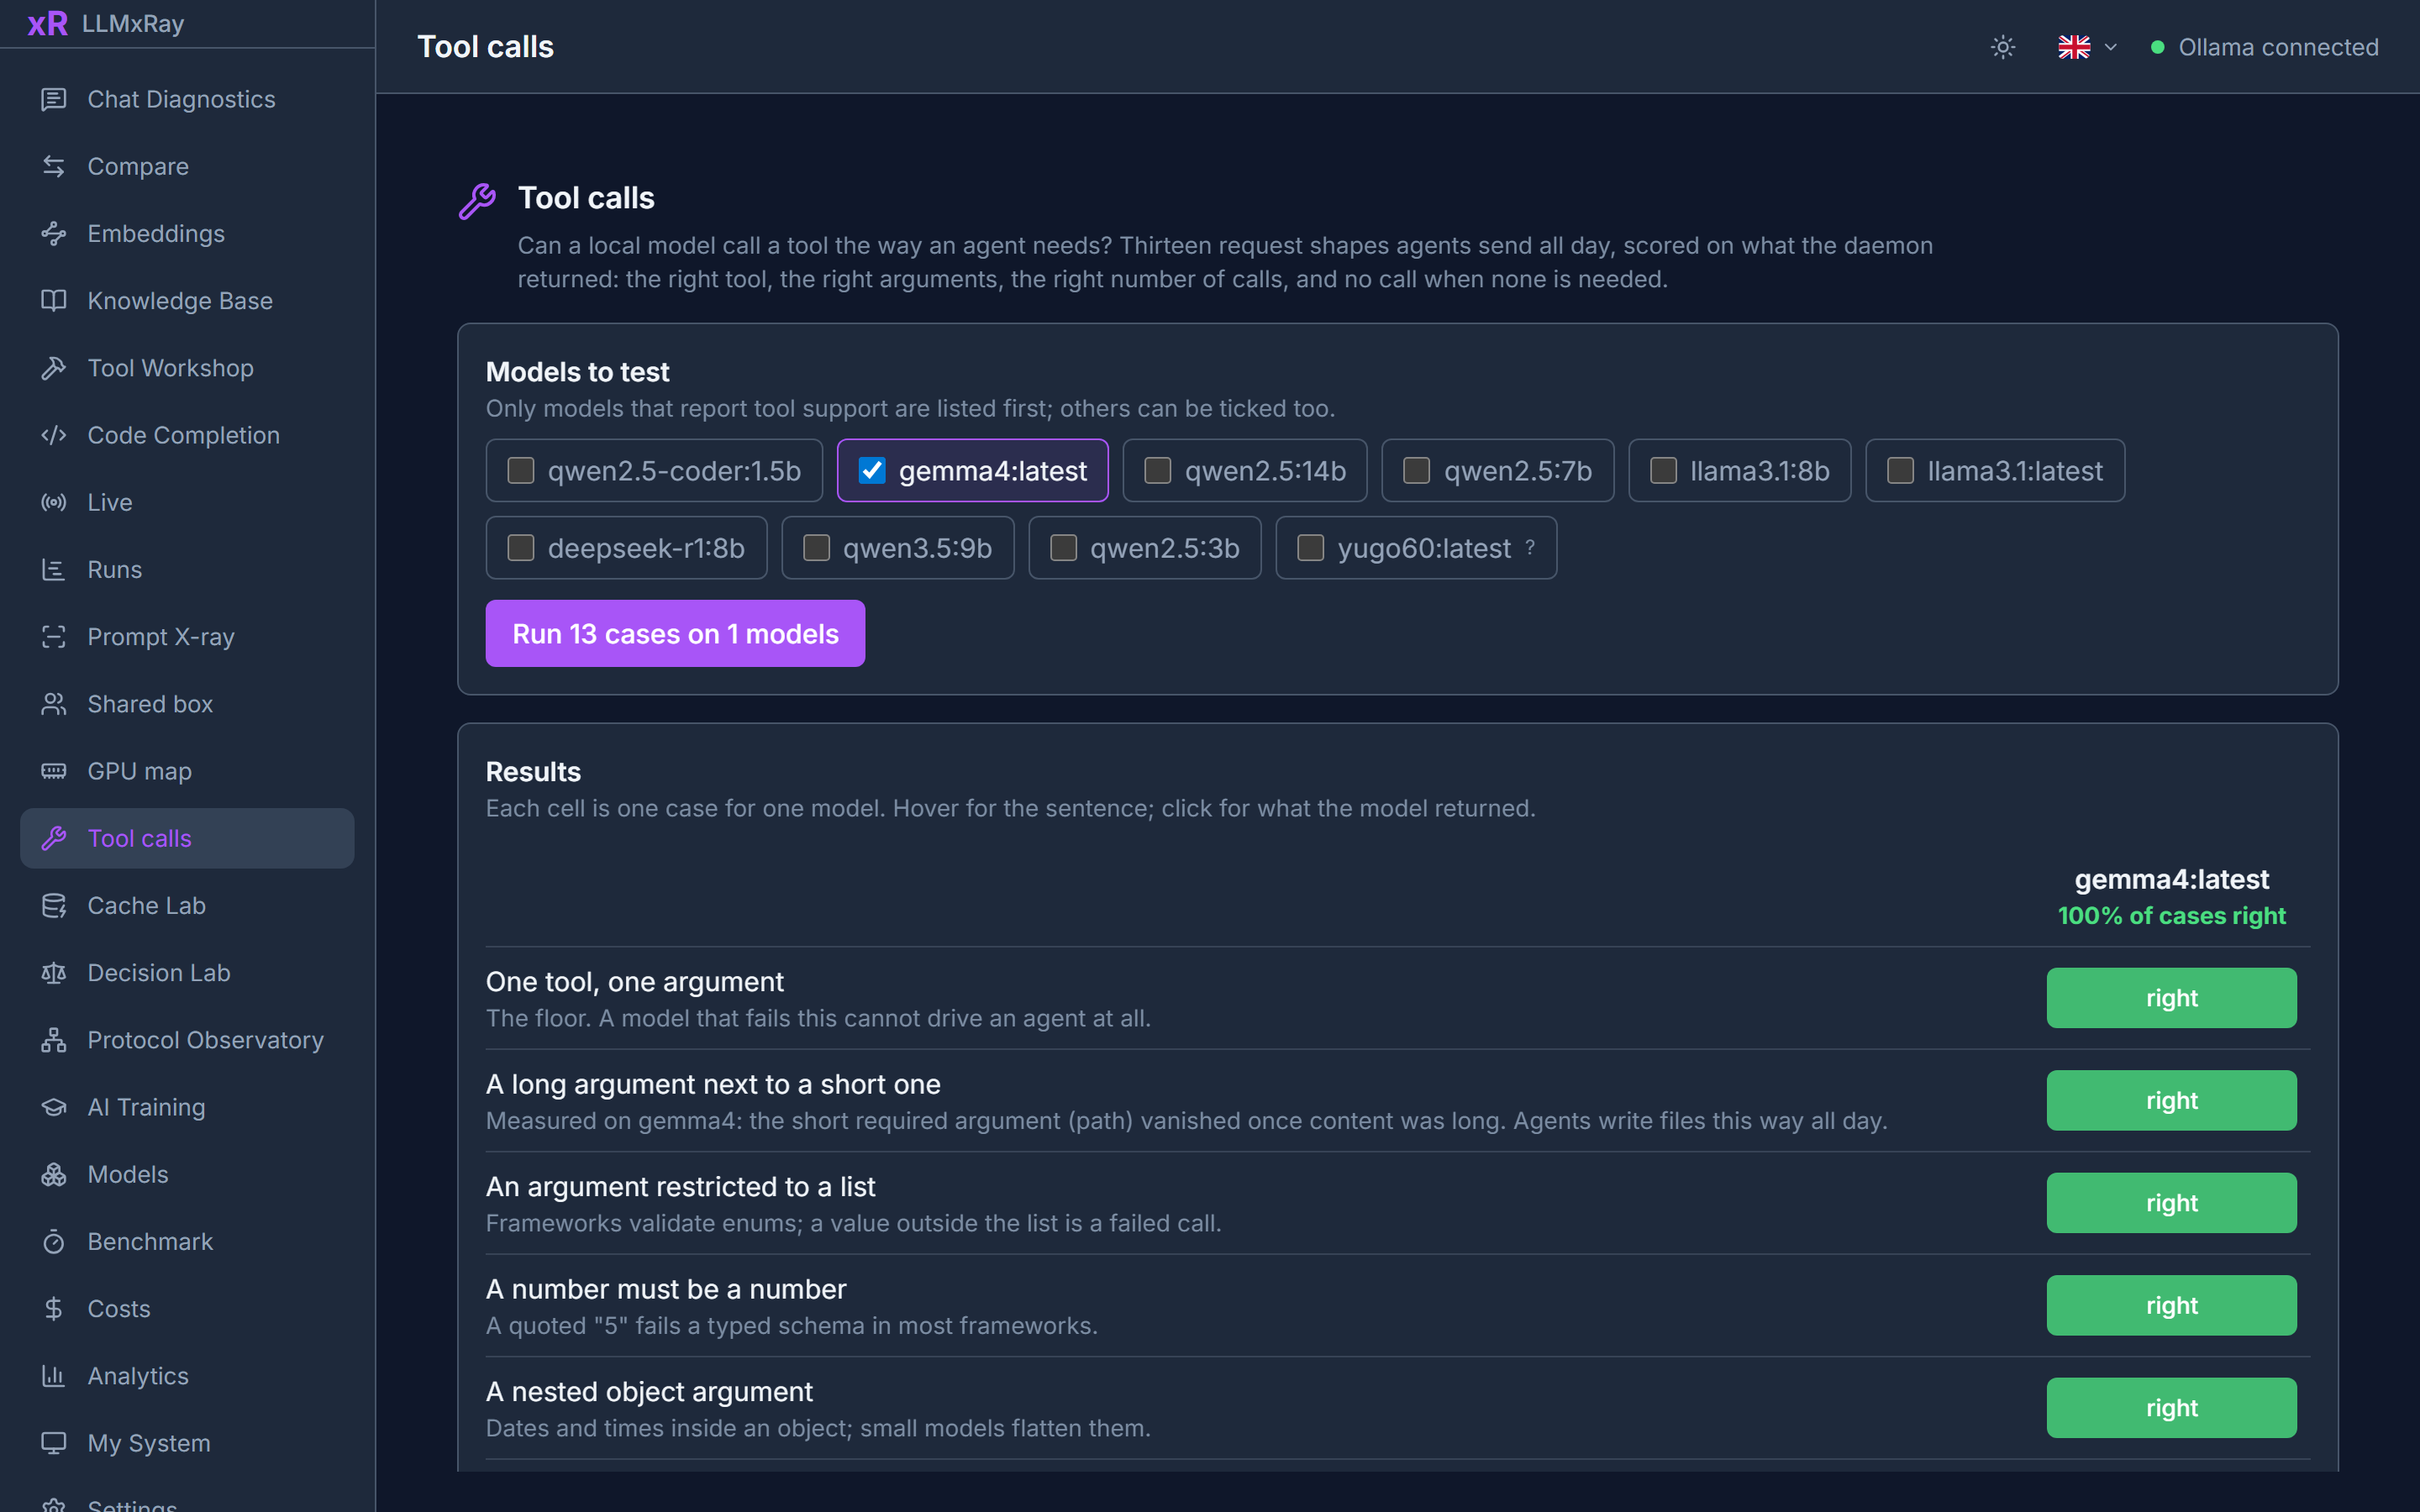
Tool calls: can this model drive an agent?
Thirteen request shapes agents send all day, scored on what the daemon returned: the right tool, the right arguments, the right number of calls, no call when none is needed. Each cell is one sentence: "the path argument is missing", "wrote the call into the answer text", "called search_web when no tool was needed". Click it for what the model returned.
Cache Lab
A local model reuses its prompt cache only while the prompt matches from the very first token. One timestamp near the top forfeits everything below it. Cache Lab finds the values that change between turns, shows where reuse dies, and then measures against your own daemon what moving them to the end saves.
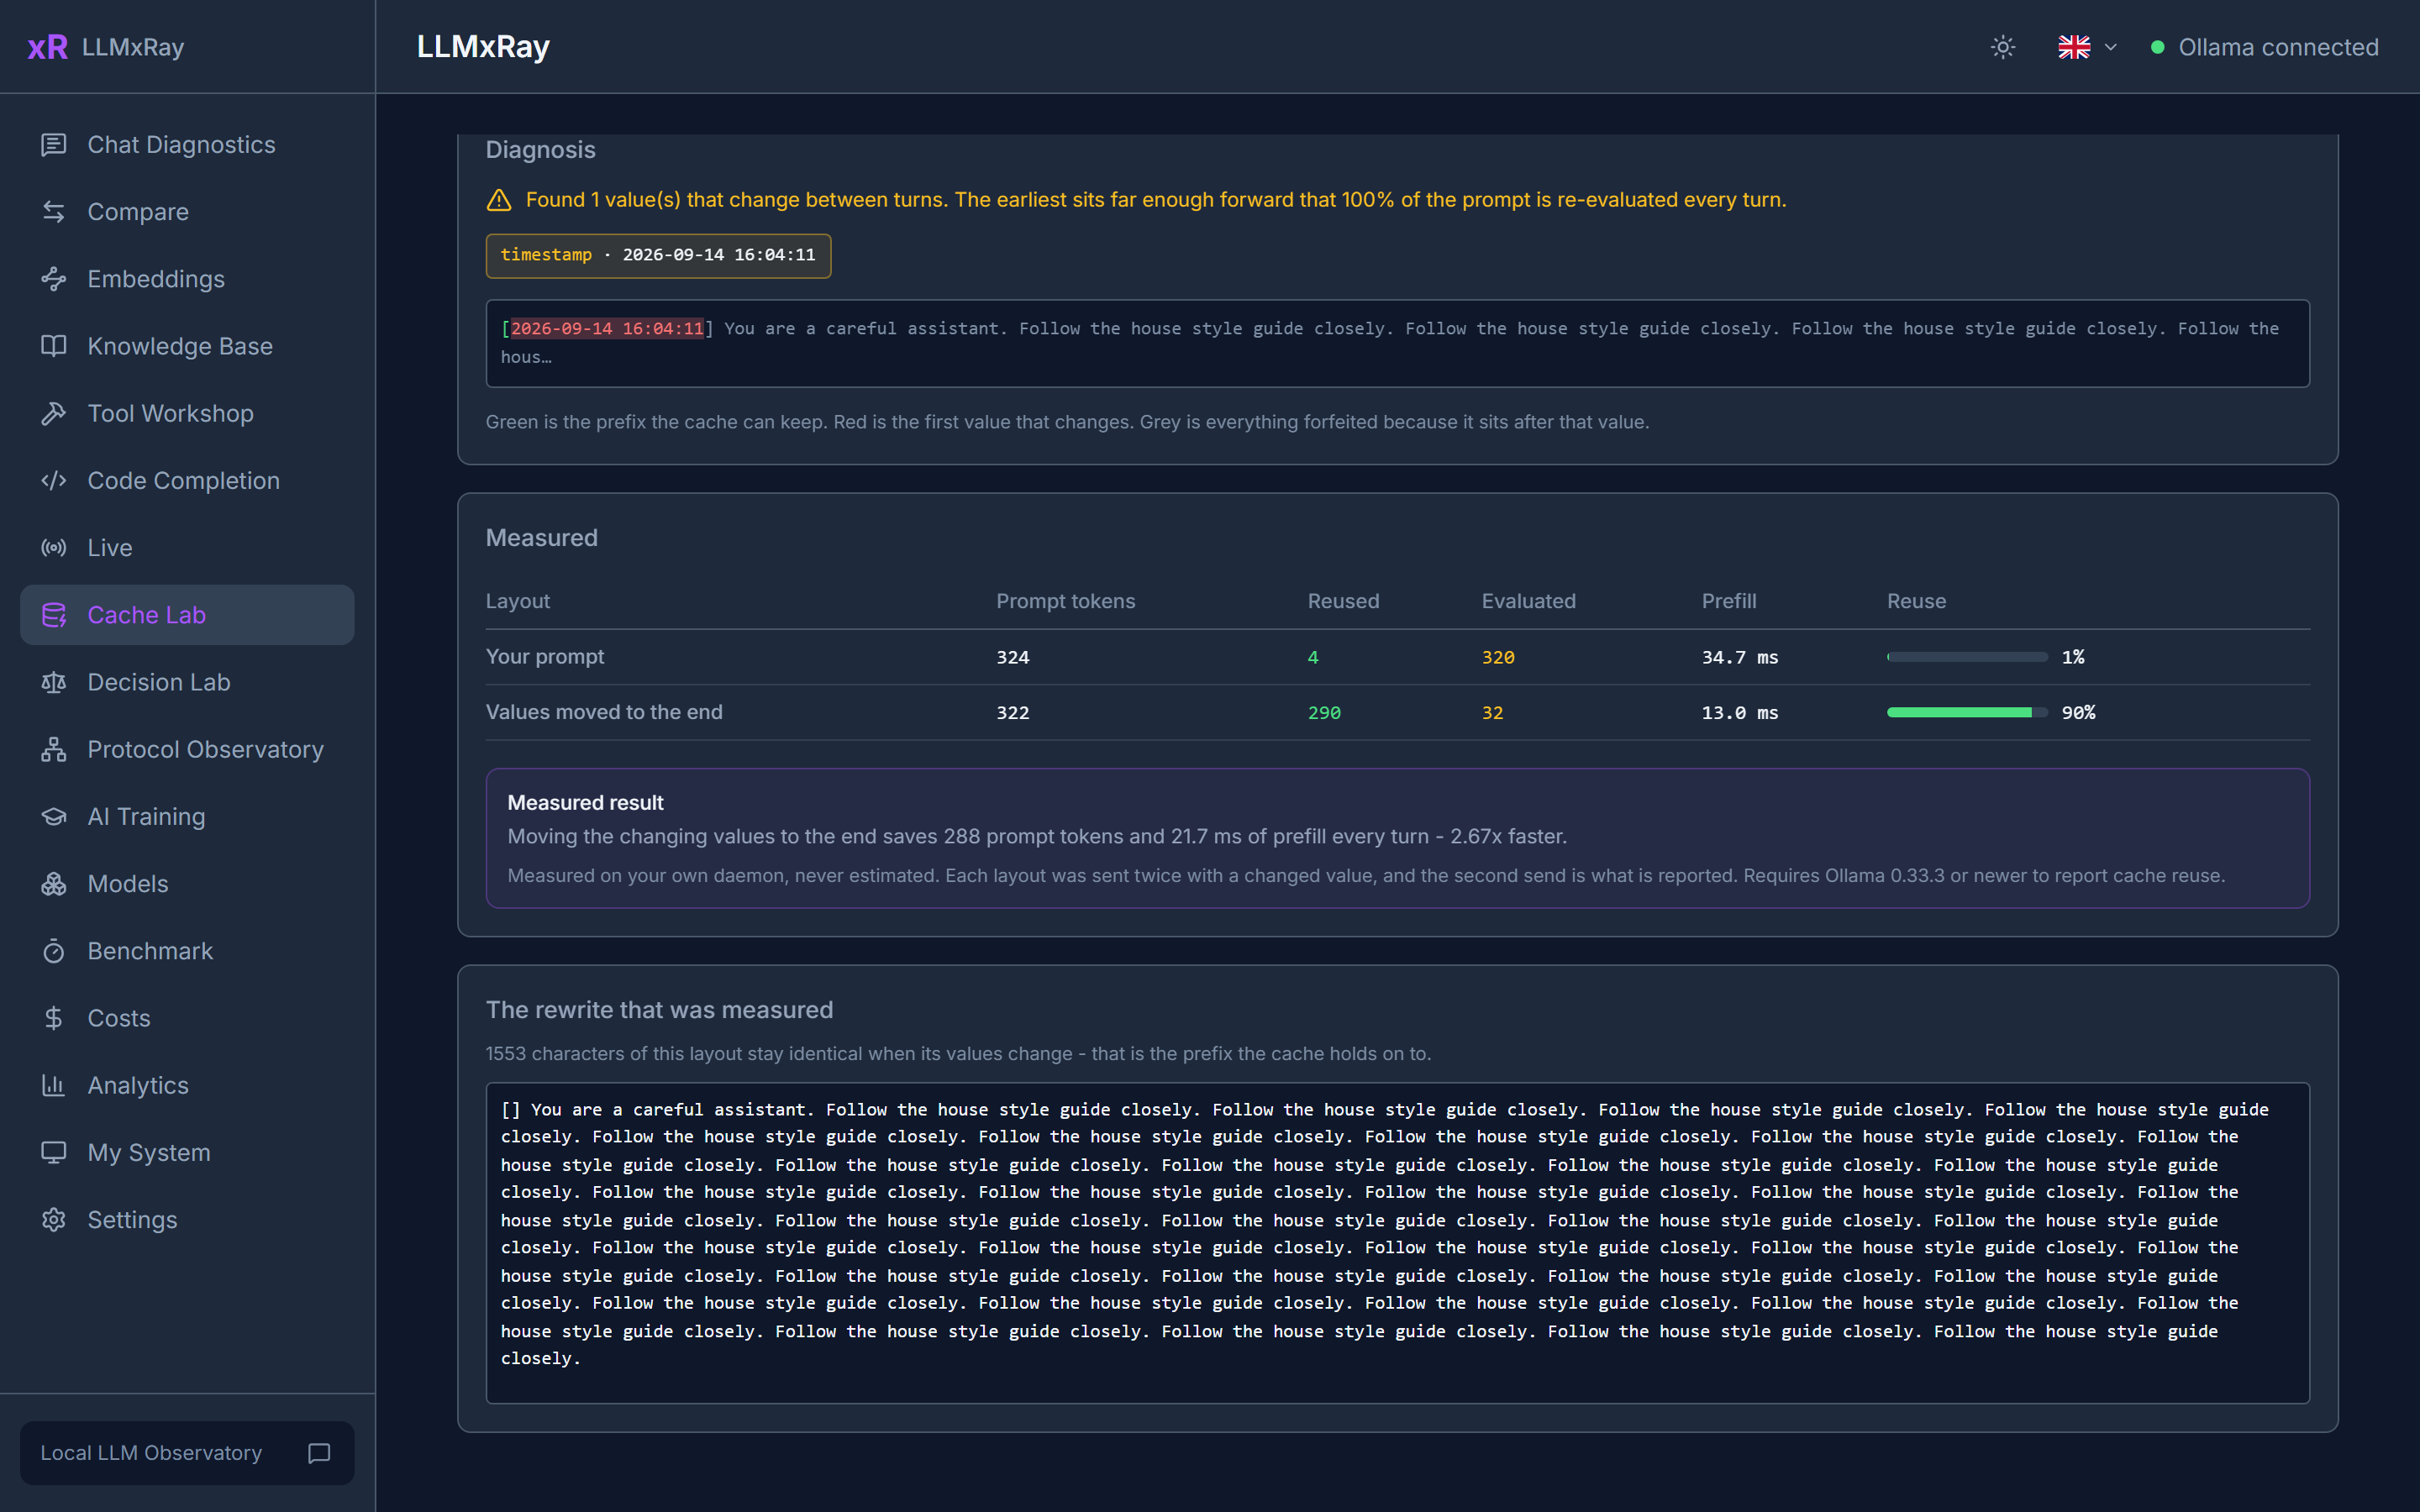
Measured on a real 324-token prompt: 4 tokens reused and 64.6 ms of prefill with the timestamp at the front, 290 reused and 18.6 ms with it at the back. 3.5x faster, same words.
Protocol Observatory
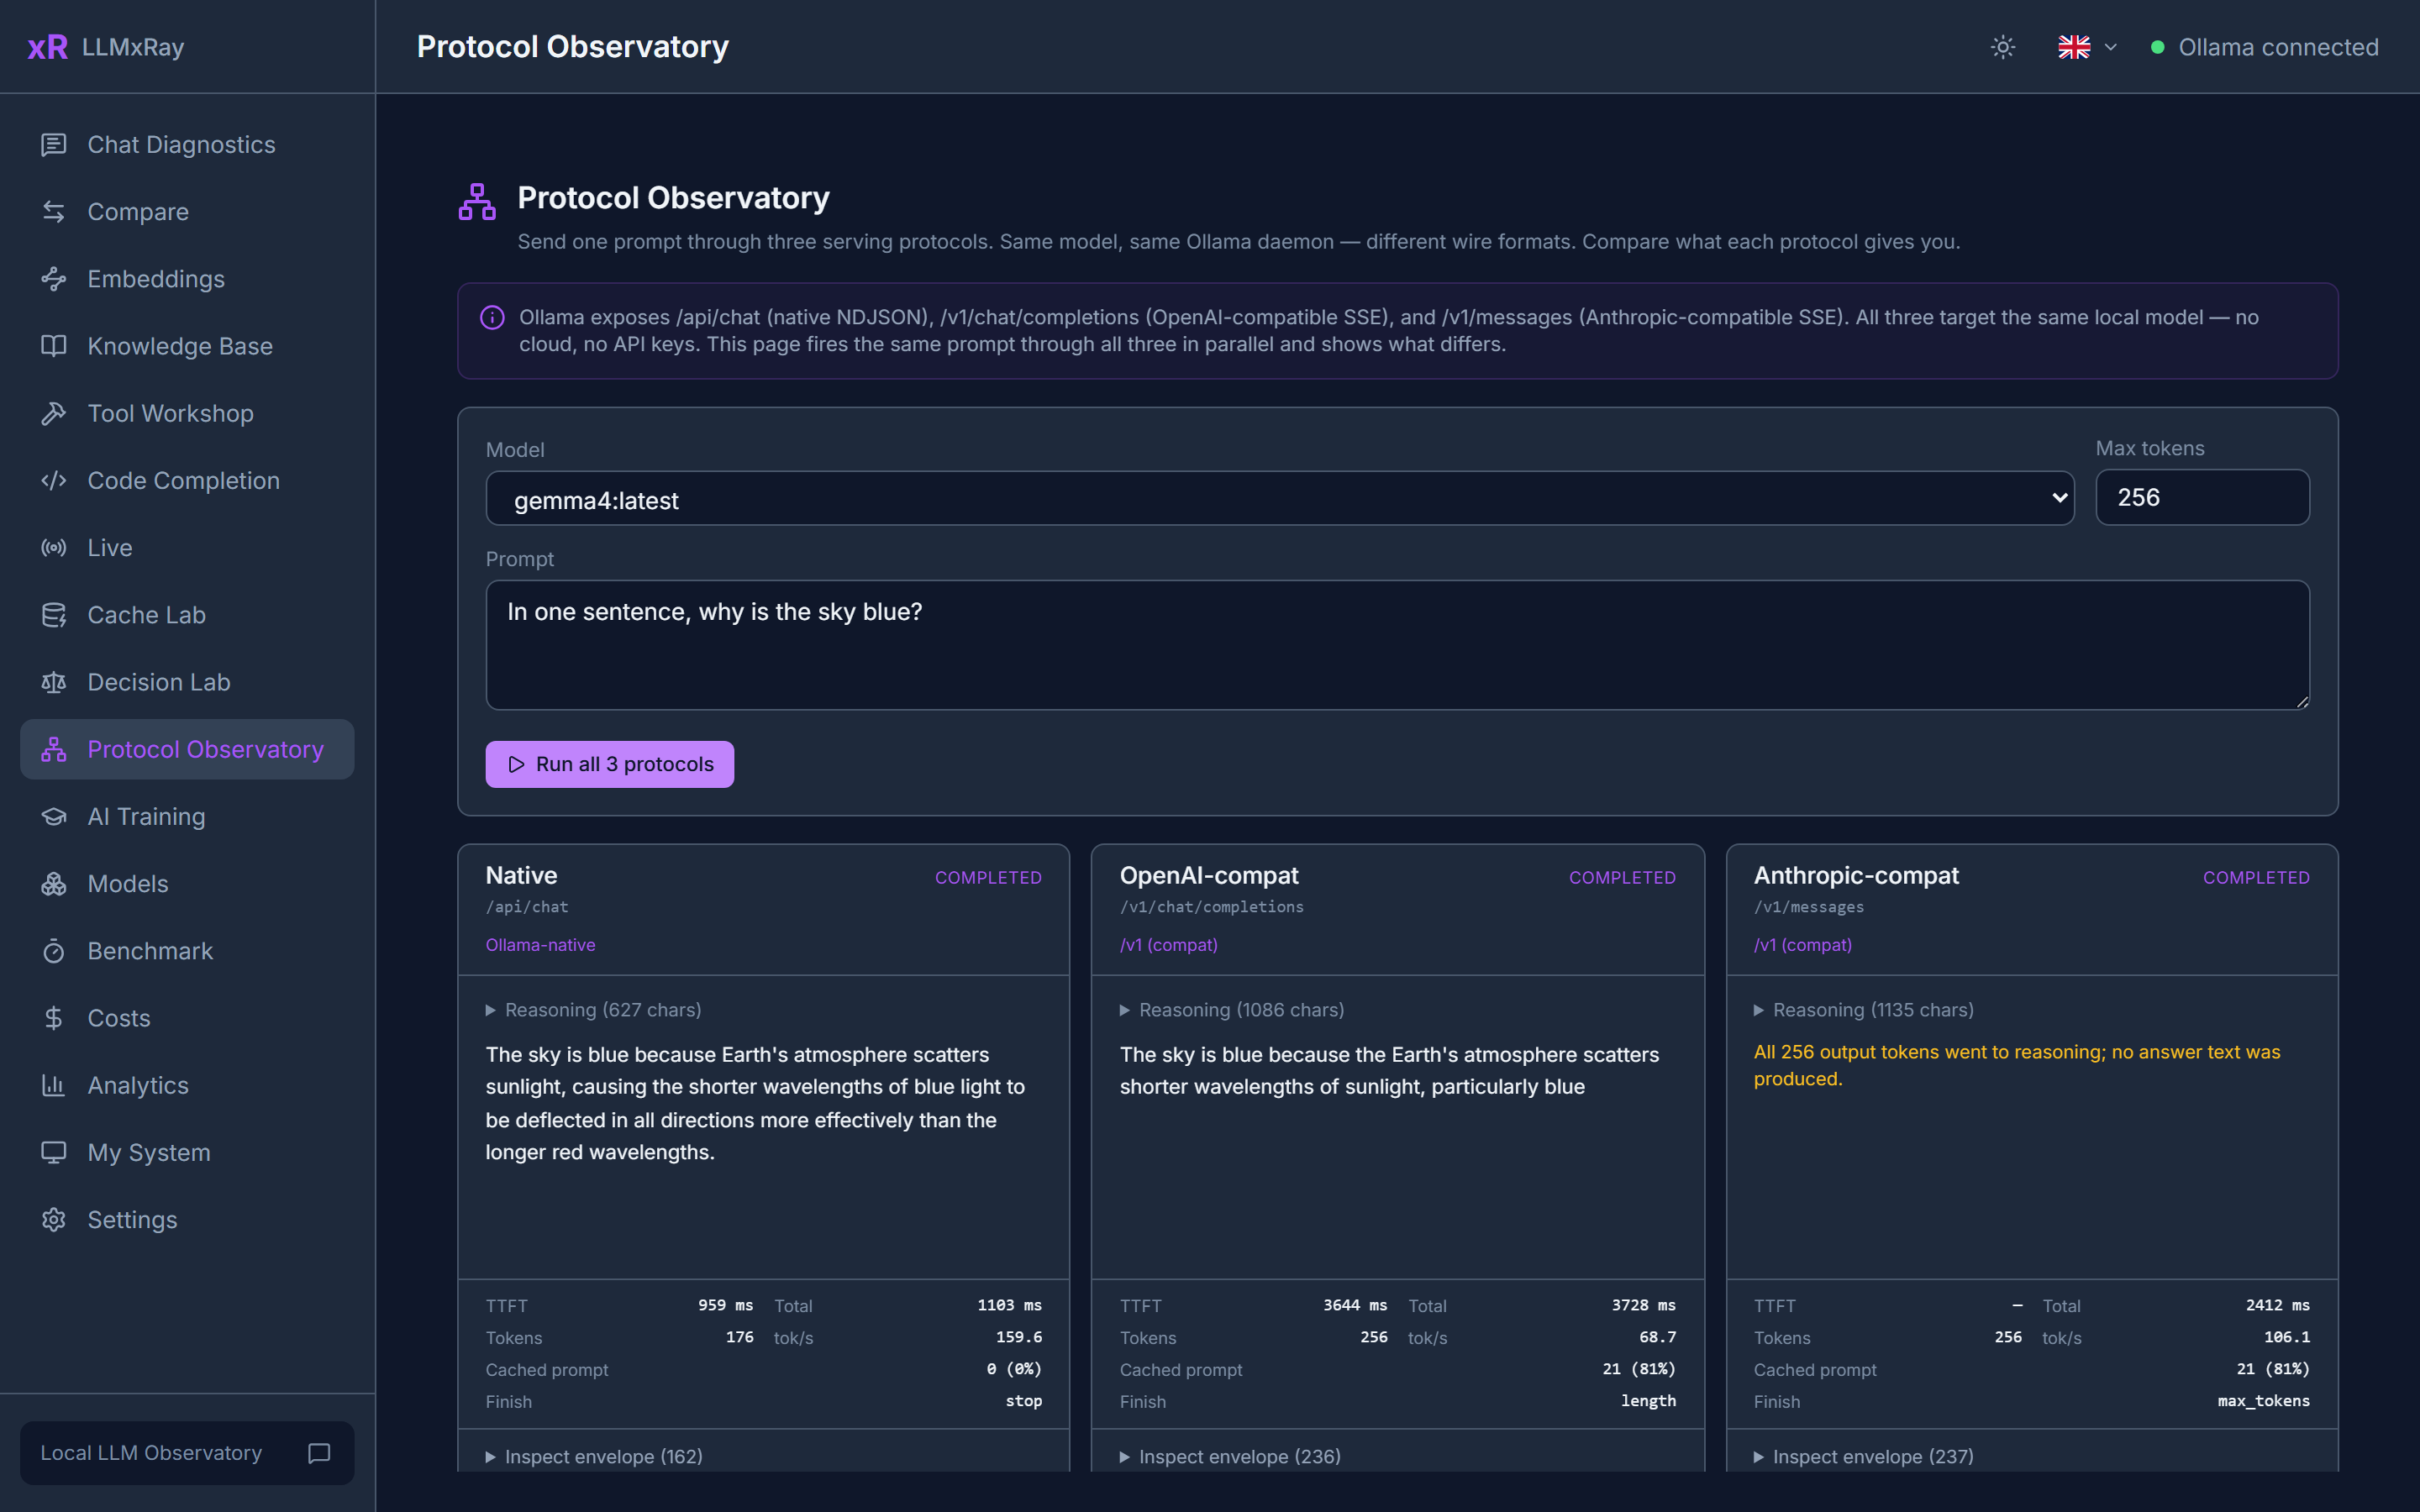
The same prompt through Ollama's three serving protocols in parallel: native /api/chat, OpenAI-compatible /v1/chat/completions, and Anthropic-compatible /v1/messages. Side-by-side streaming, per-protocol metrics, and an envelope diff that shows how each one frames finish reasons, token counts and errors.
Keep it, and send it on
Every turn's record (tokens, cache, timings, client, model, never the text) stays on your machine for 30 days, so a restart picks up where it stopped. Live, Runs, Prompt X-ray and the MCP tools carry on as if nothing happened.
If your team already reads traces, send the turns there: each model call becomes an OpenTelemetry span with the GenAI attributes viewers already read, each run a trace, and the tool time between calls its own span, the same waterfall as Runs. Set an address on the Live page, or OTEL_EXPORTER_OTLP_ENDPOINT.
| Viewer | Address |
|---|---|
Jaeger (docker run -p 16686:16686 -p 4318:4318 jaegertracing/jaeger) | http://localhost:4318 |
Arize Phoenix (docker run -p 6006:6006 arizephoenix/phoenix) | http://localhost:6006 |
| Langfuse | https://cloud.langfuse.com/api/public/otel, with a Basic header from your keys |
| Grafana Tempo, an OpenTelemetry Collector | its OTLP HTTP address, usually port 4318 |
The prompt text goes along only if you switch on both Keep the prompt text and Include the prompt text in each span.
For agents
If you are an agent running on a local model, LLMxRay can tell you what went wrong with your own calls. Two steps.
- Send your Ollama calls to port 11435 instead of 11434. It behaves exactly like Ollama and forwards everything; LLMxRay only records what passes.
- Add the LLMxRay MCP server to your tools:
{ "mcpServers": { "llmxray": { "command": "npx", "args": ["-y", "-p", "llmxray", "llmxray-mcp"] } } }
Seven tools, all read-only, nothing leaves the machine:
| Tool | Answers |
|---|---|
diagnose_my_turns | What stands out in your recent turns, as sentences with the fix: a prompt rejected for exceeding the loaded context, the prompt cache lost on every turn or on one turn, a model running partly on CPU, tool schemas crowding the prompt. |
read_my_last_turn | Your last turn in numbers: prompt tokens and cached share, prefill time and speed, generated tokens and speed, why generation stopped, what the prompt was made of, whether the model fit in video memory. |
list_local_models | Which models are pulled, their size and quantisation, which are loaded now and with what context, and whether each fits in video memory. |
list_my_turns | The history: one line per turn with tokens, cached share, prefill, generation speed, stop reason and flags. |
compare_my_turns | Did a change help: medians of cached share, prefill, speed and prompt size before and after a moment, with a verdict. |
estimate_my_prompt | Before sending: does a prompt of N tokens fit the loaded context, how much headroom is left, does the model sit in video memory, how much the cache would reuse. |
read_llmxray_status | Where LLMxRay runs, the observe port, the Ollama it forwards to, how many turns it keeps. |
LLMxRay itself must be running (npx llmxray). The MCP server reads from it over localhost.
The same procedure, as an Agent Skill your agent can load: npx skills add LogneBudo/llmxray (skills.sh) or clawhub install llmxray-diagnose-ollama-calls (ClawHub). Source: skills/diagnose-ollama-calls/SKILL.md.
Name yourself so your turns are yours: send the header X-LLMxRay-Client: my-agent, or use http://localhost:11435/?client=my-agent as the base URL, and pass my-agent as client to the tools. Where to set the base URL: Ollama SDKs and CLI OLLAMA_HOST=127.0.0.1:11435; OpenAI-compatible clients base_url=http://localhost:11435/v1; Claude Code ANTHROPIC_BASE_URL=http://localhost:11435; Continue apiBase; Open WebUI OLLAMA_BASE_URL.
Also in the box
You run a local model. You chat with it. LLMxRay answers the questions that come next: how fast was each token, what did the prompt cost, did the cache help, which setting was actually better, and what are your other tools sending to the same model.
Every page below is one of those answers.
Chat, token by token
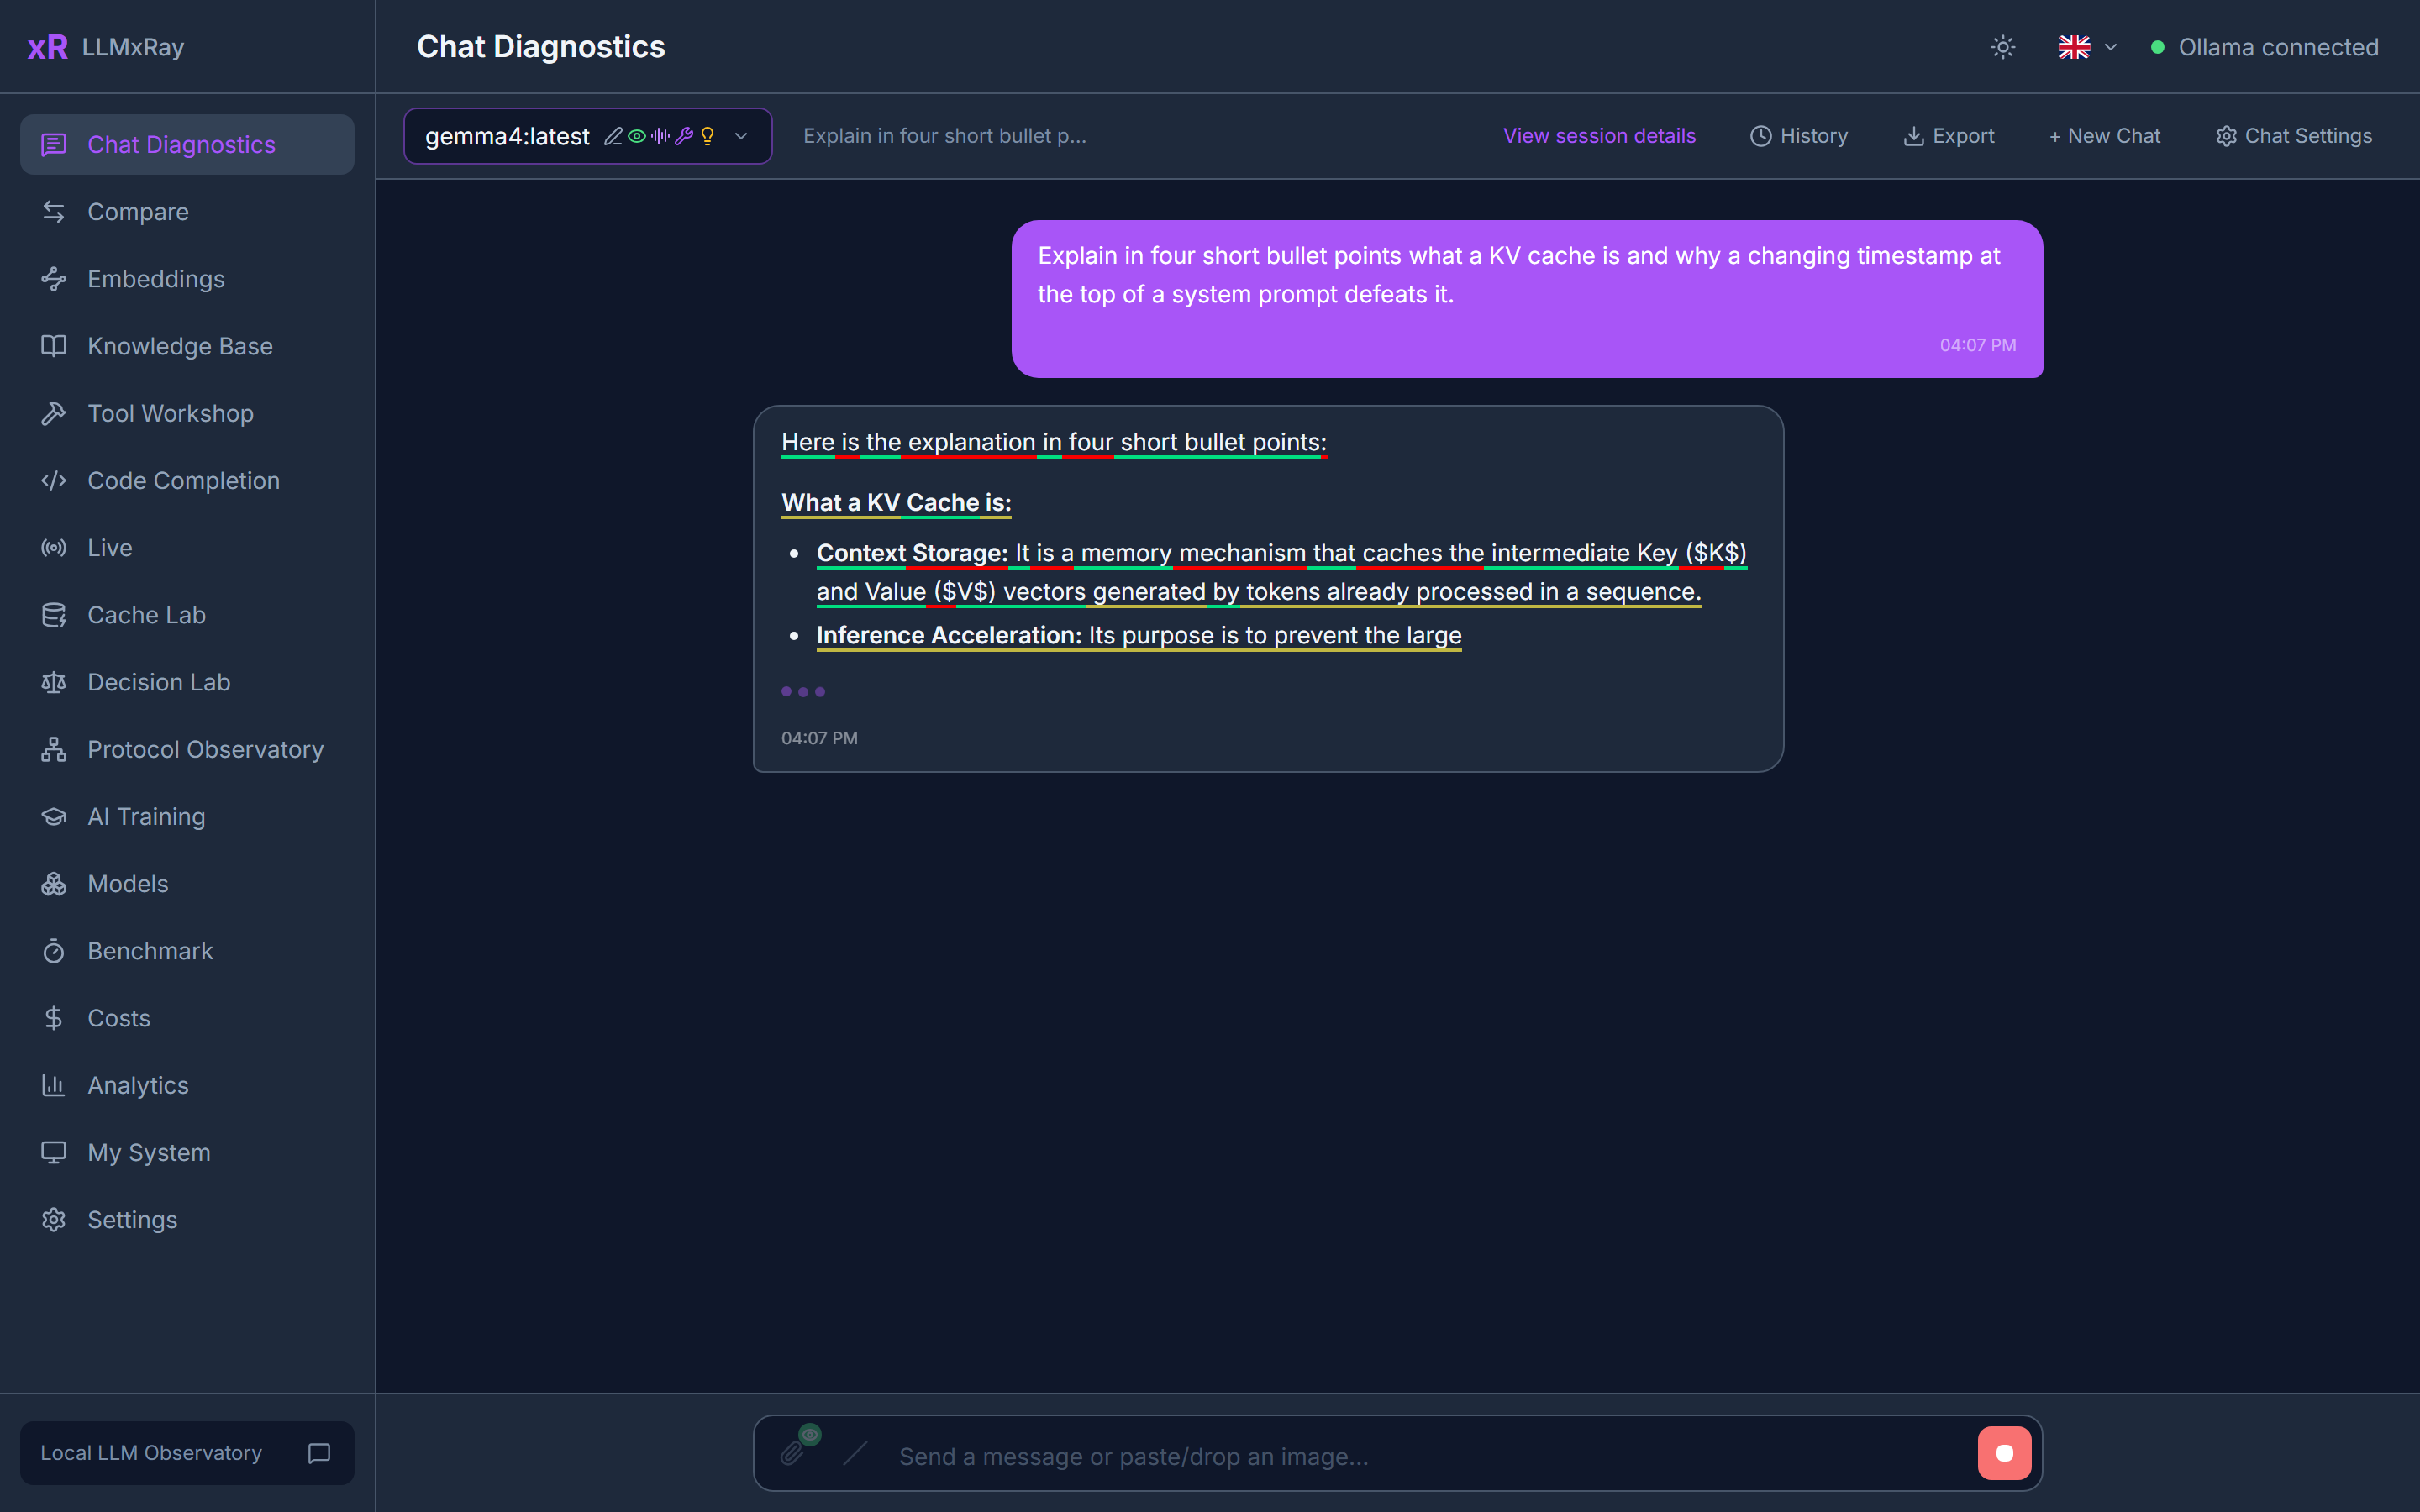
Every token is drawn as it arrives, coloured by the model's own probability for it, from Ollama's logprobs. You see where the model hesitated and where it was sure. Markdown, multi-turn, file and image attachments, slash commands, and a thinking budget for reasoning models (off, model's choice, or low / medium / high / max).
Each response is also checked as it lands. A badge appears only when something is wrong: repetition, a refusal, gibberish, an empty answer, or a reply cut off at the token limit.
Screenshot
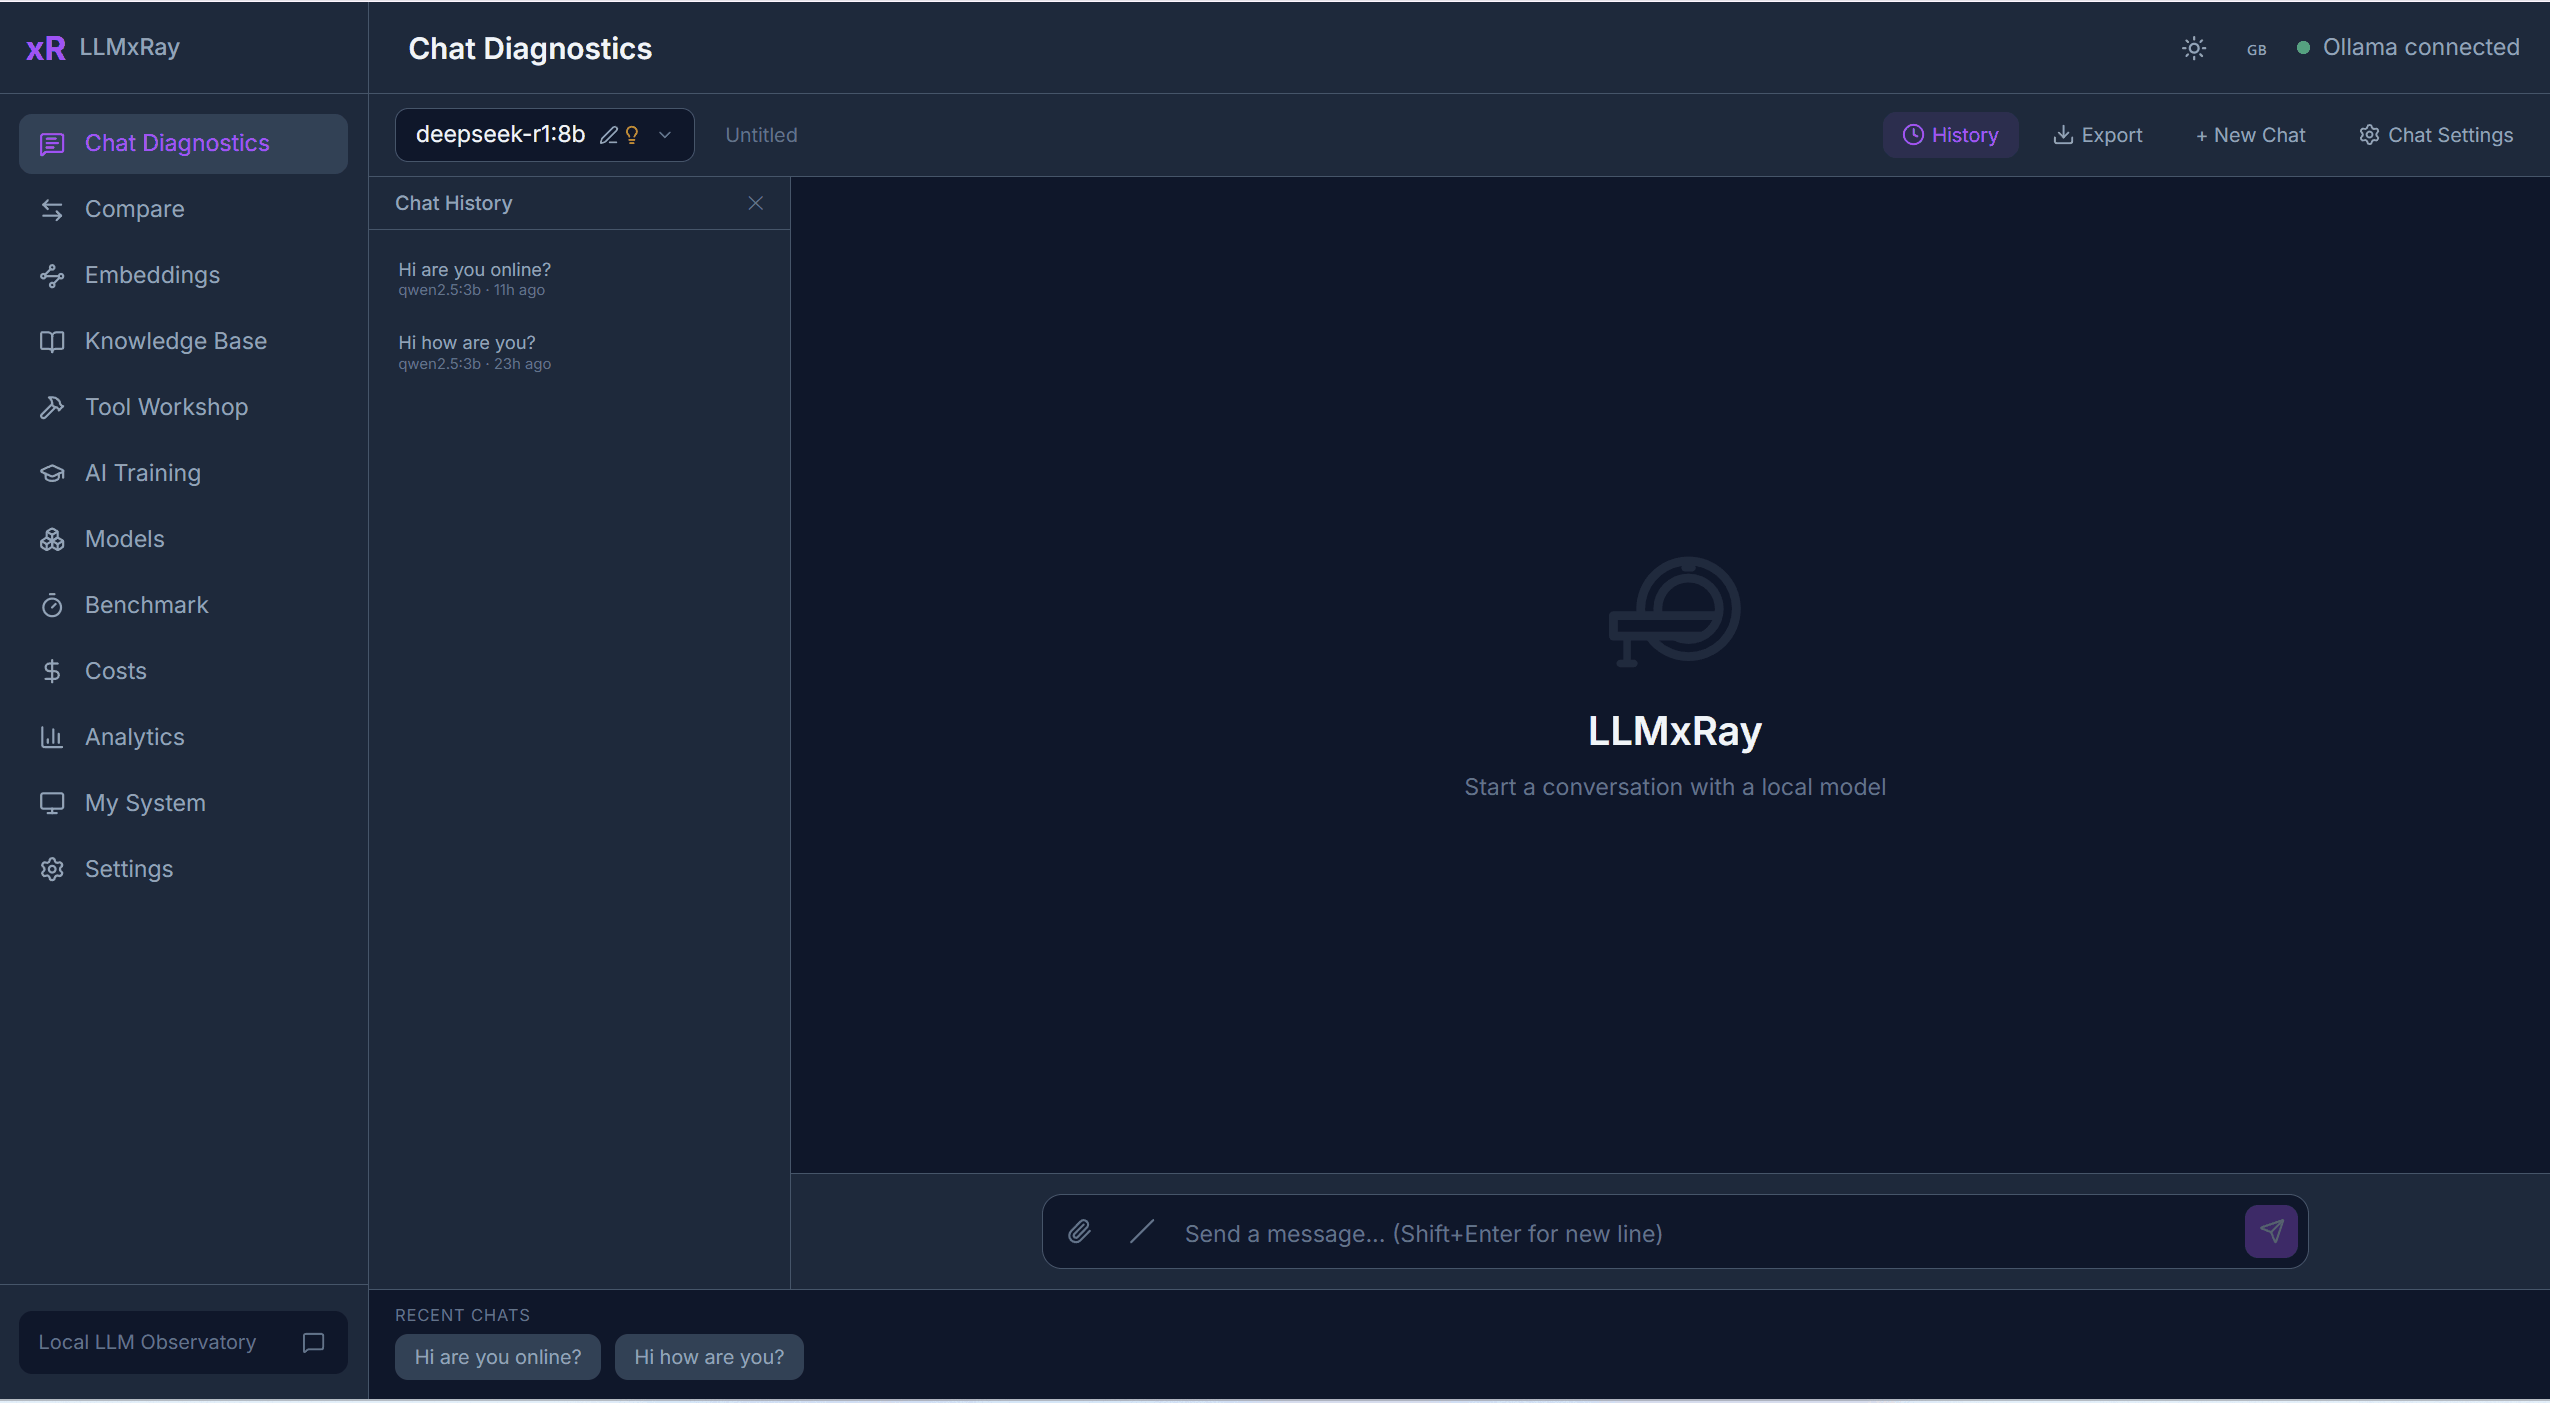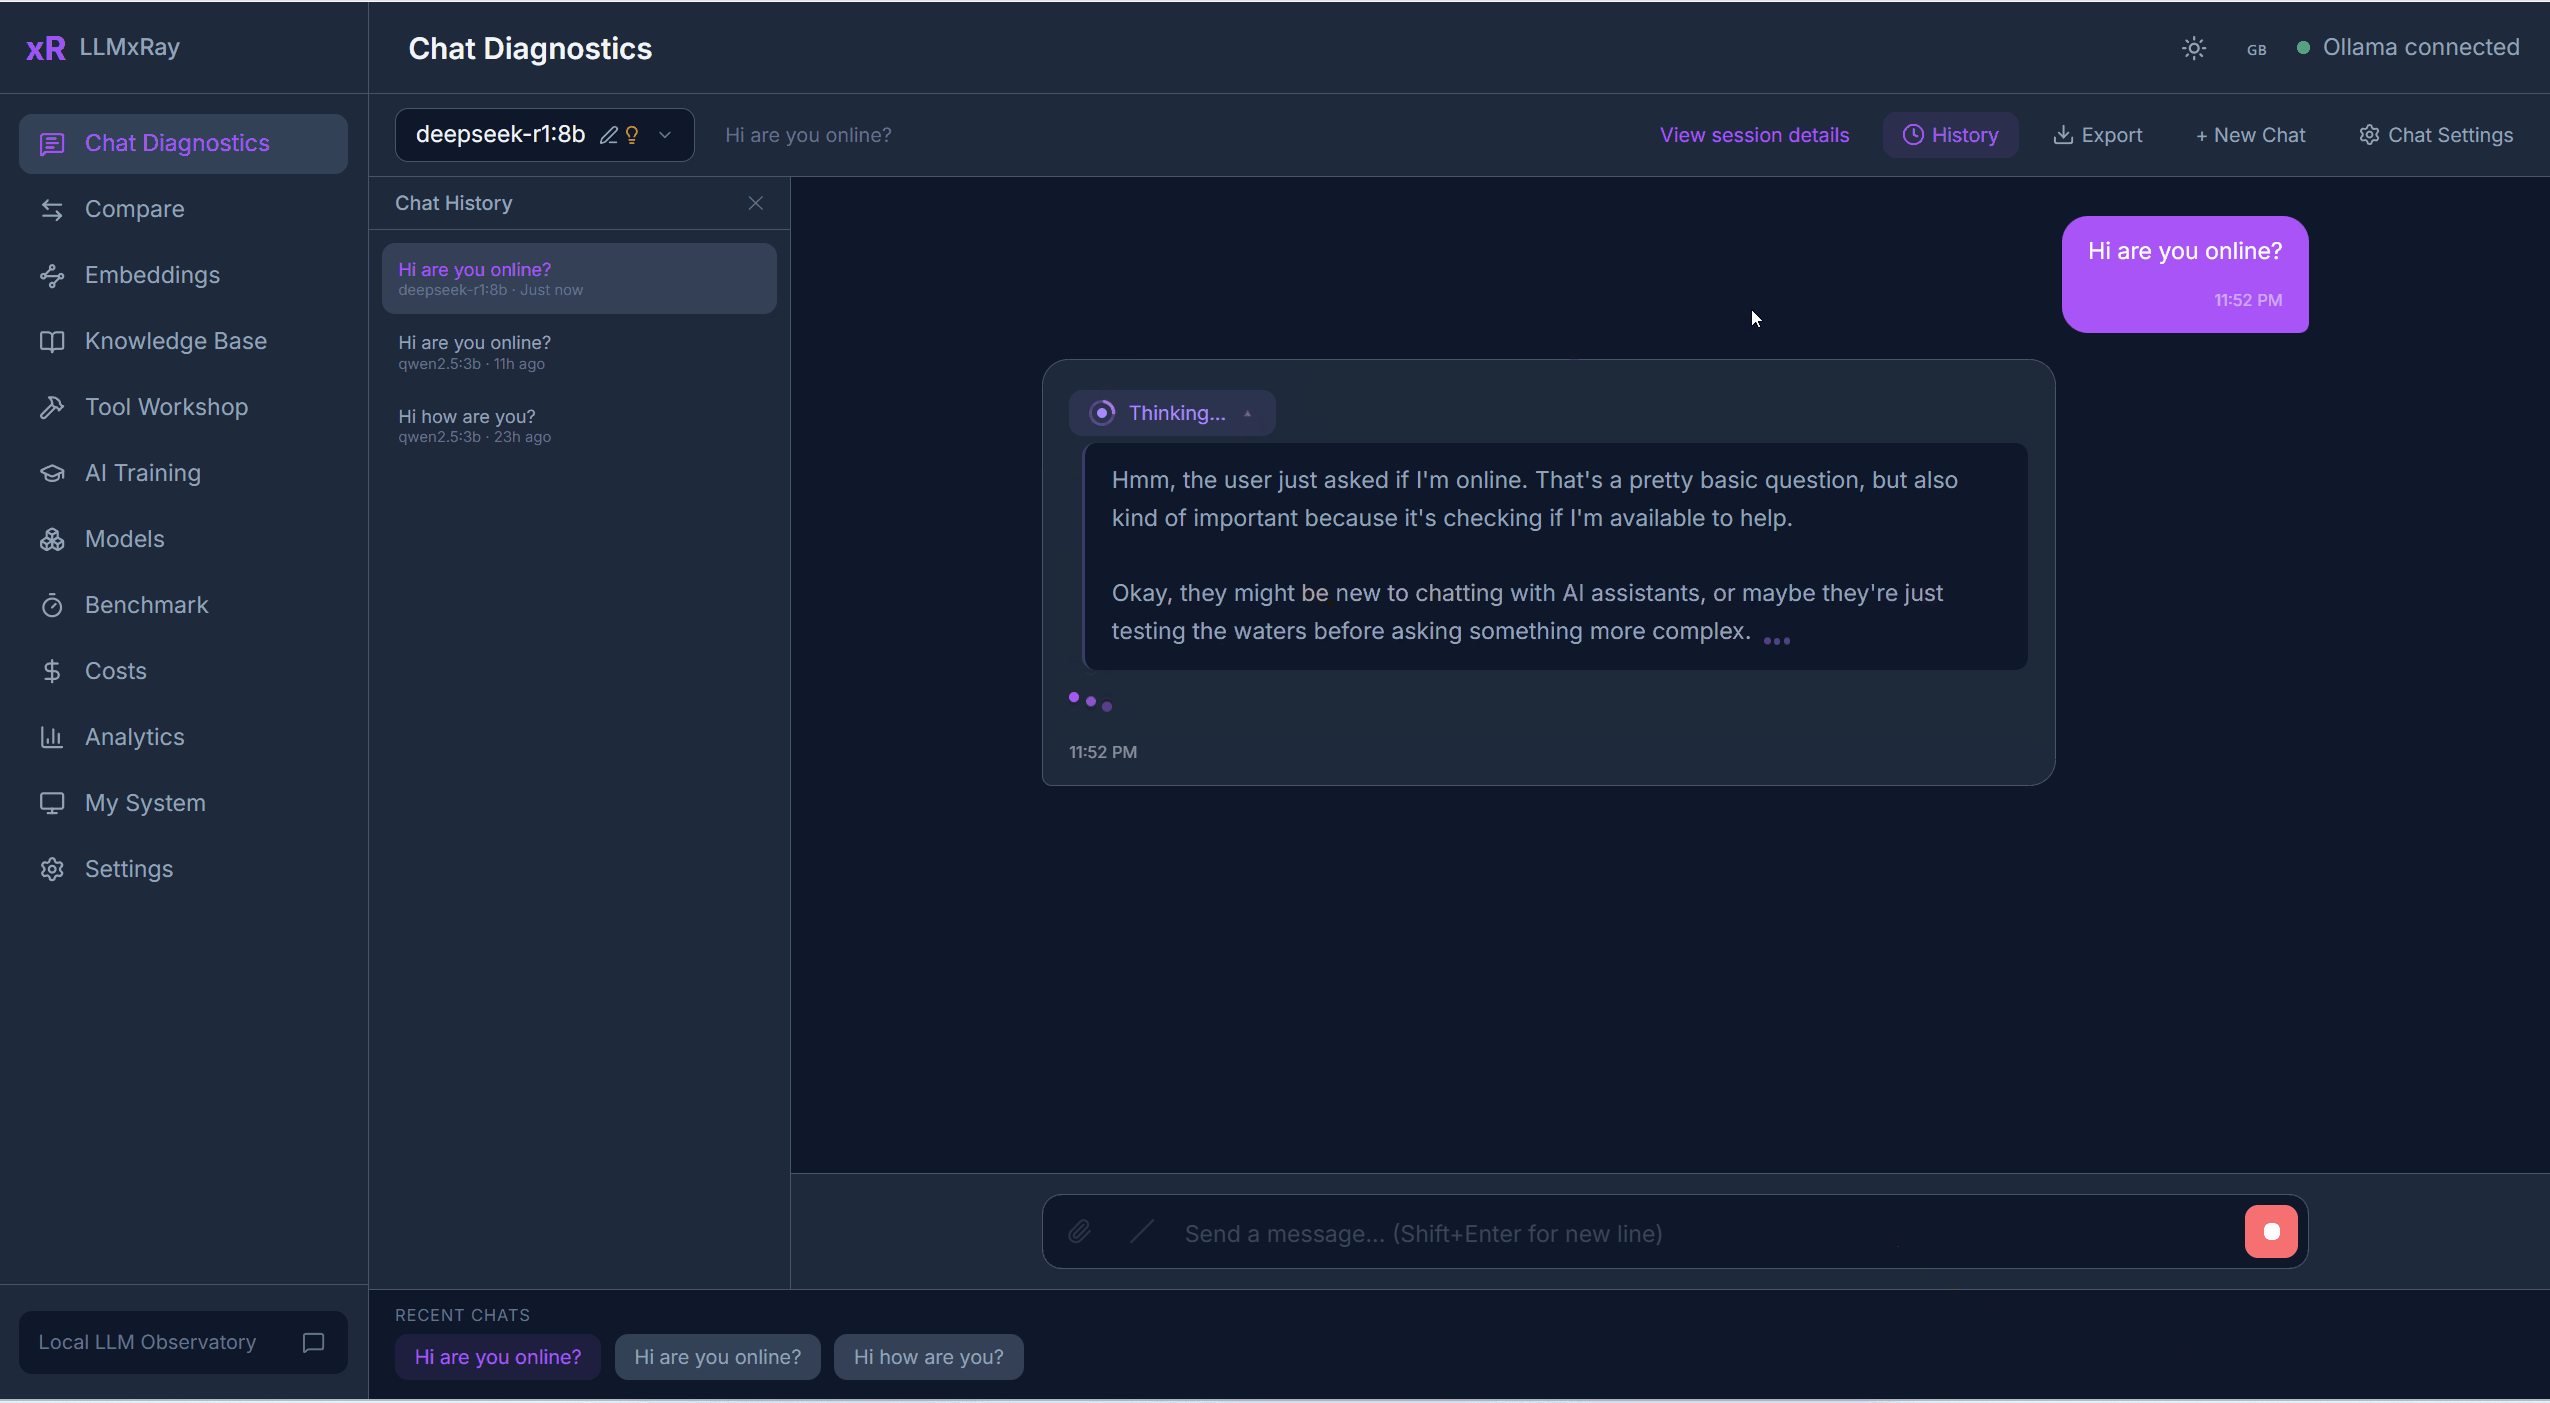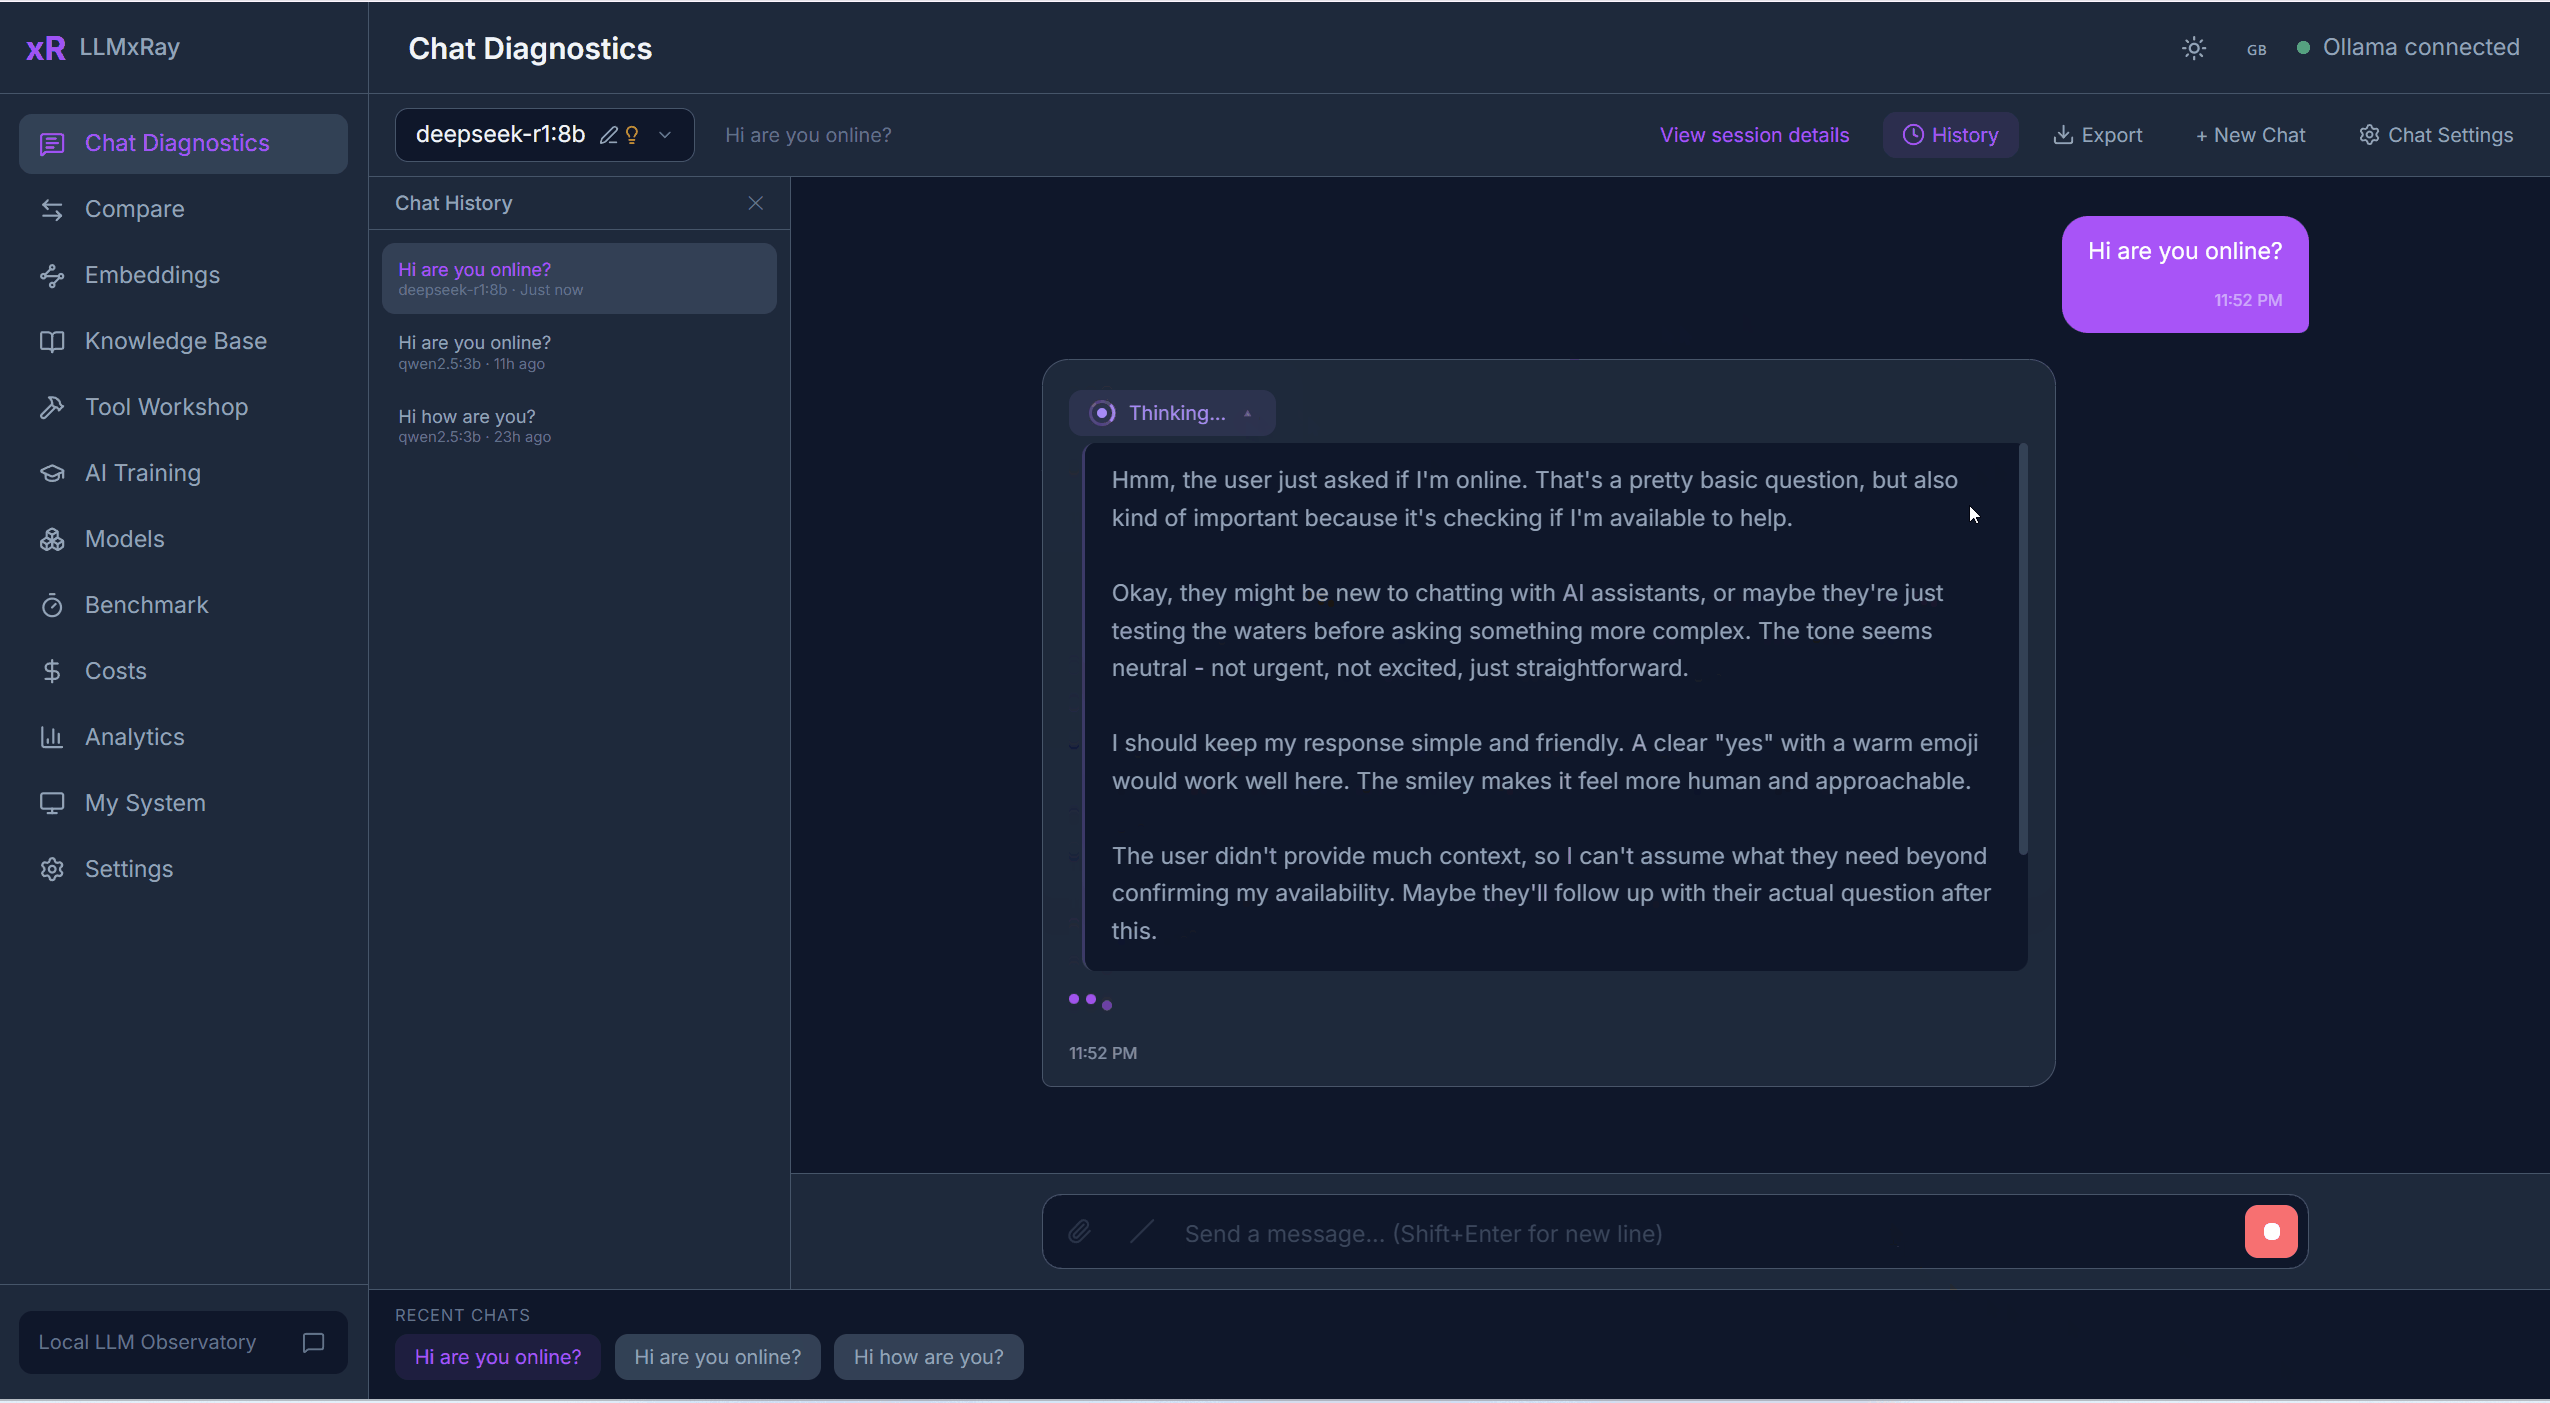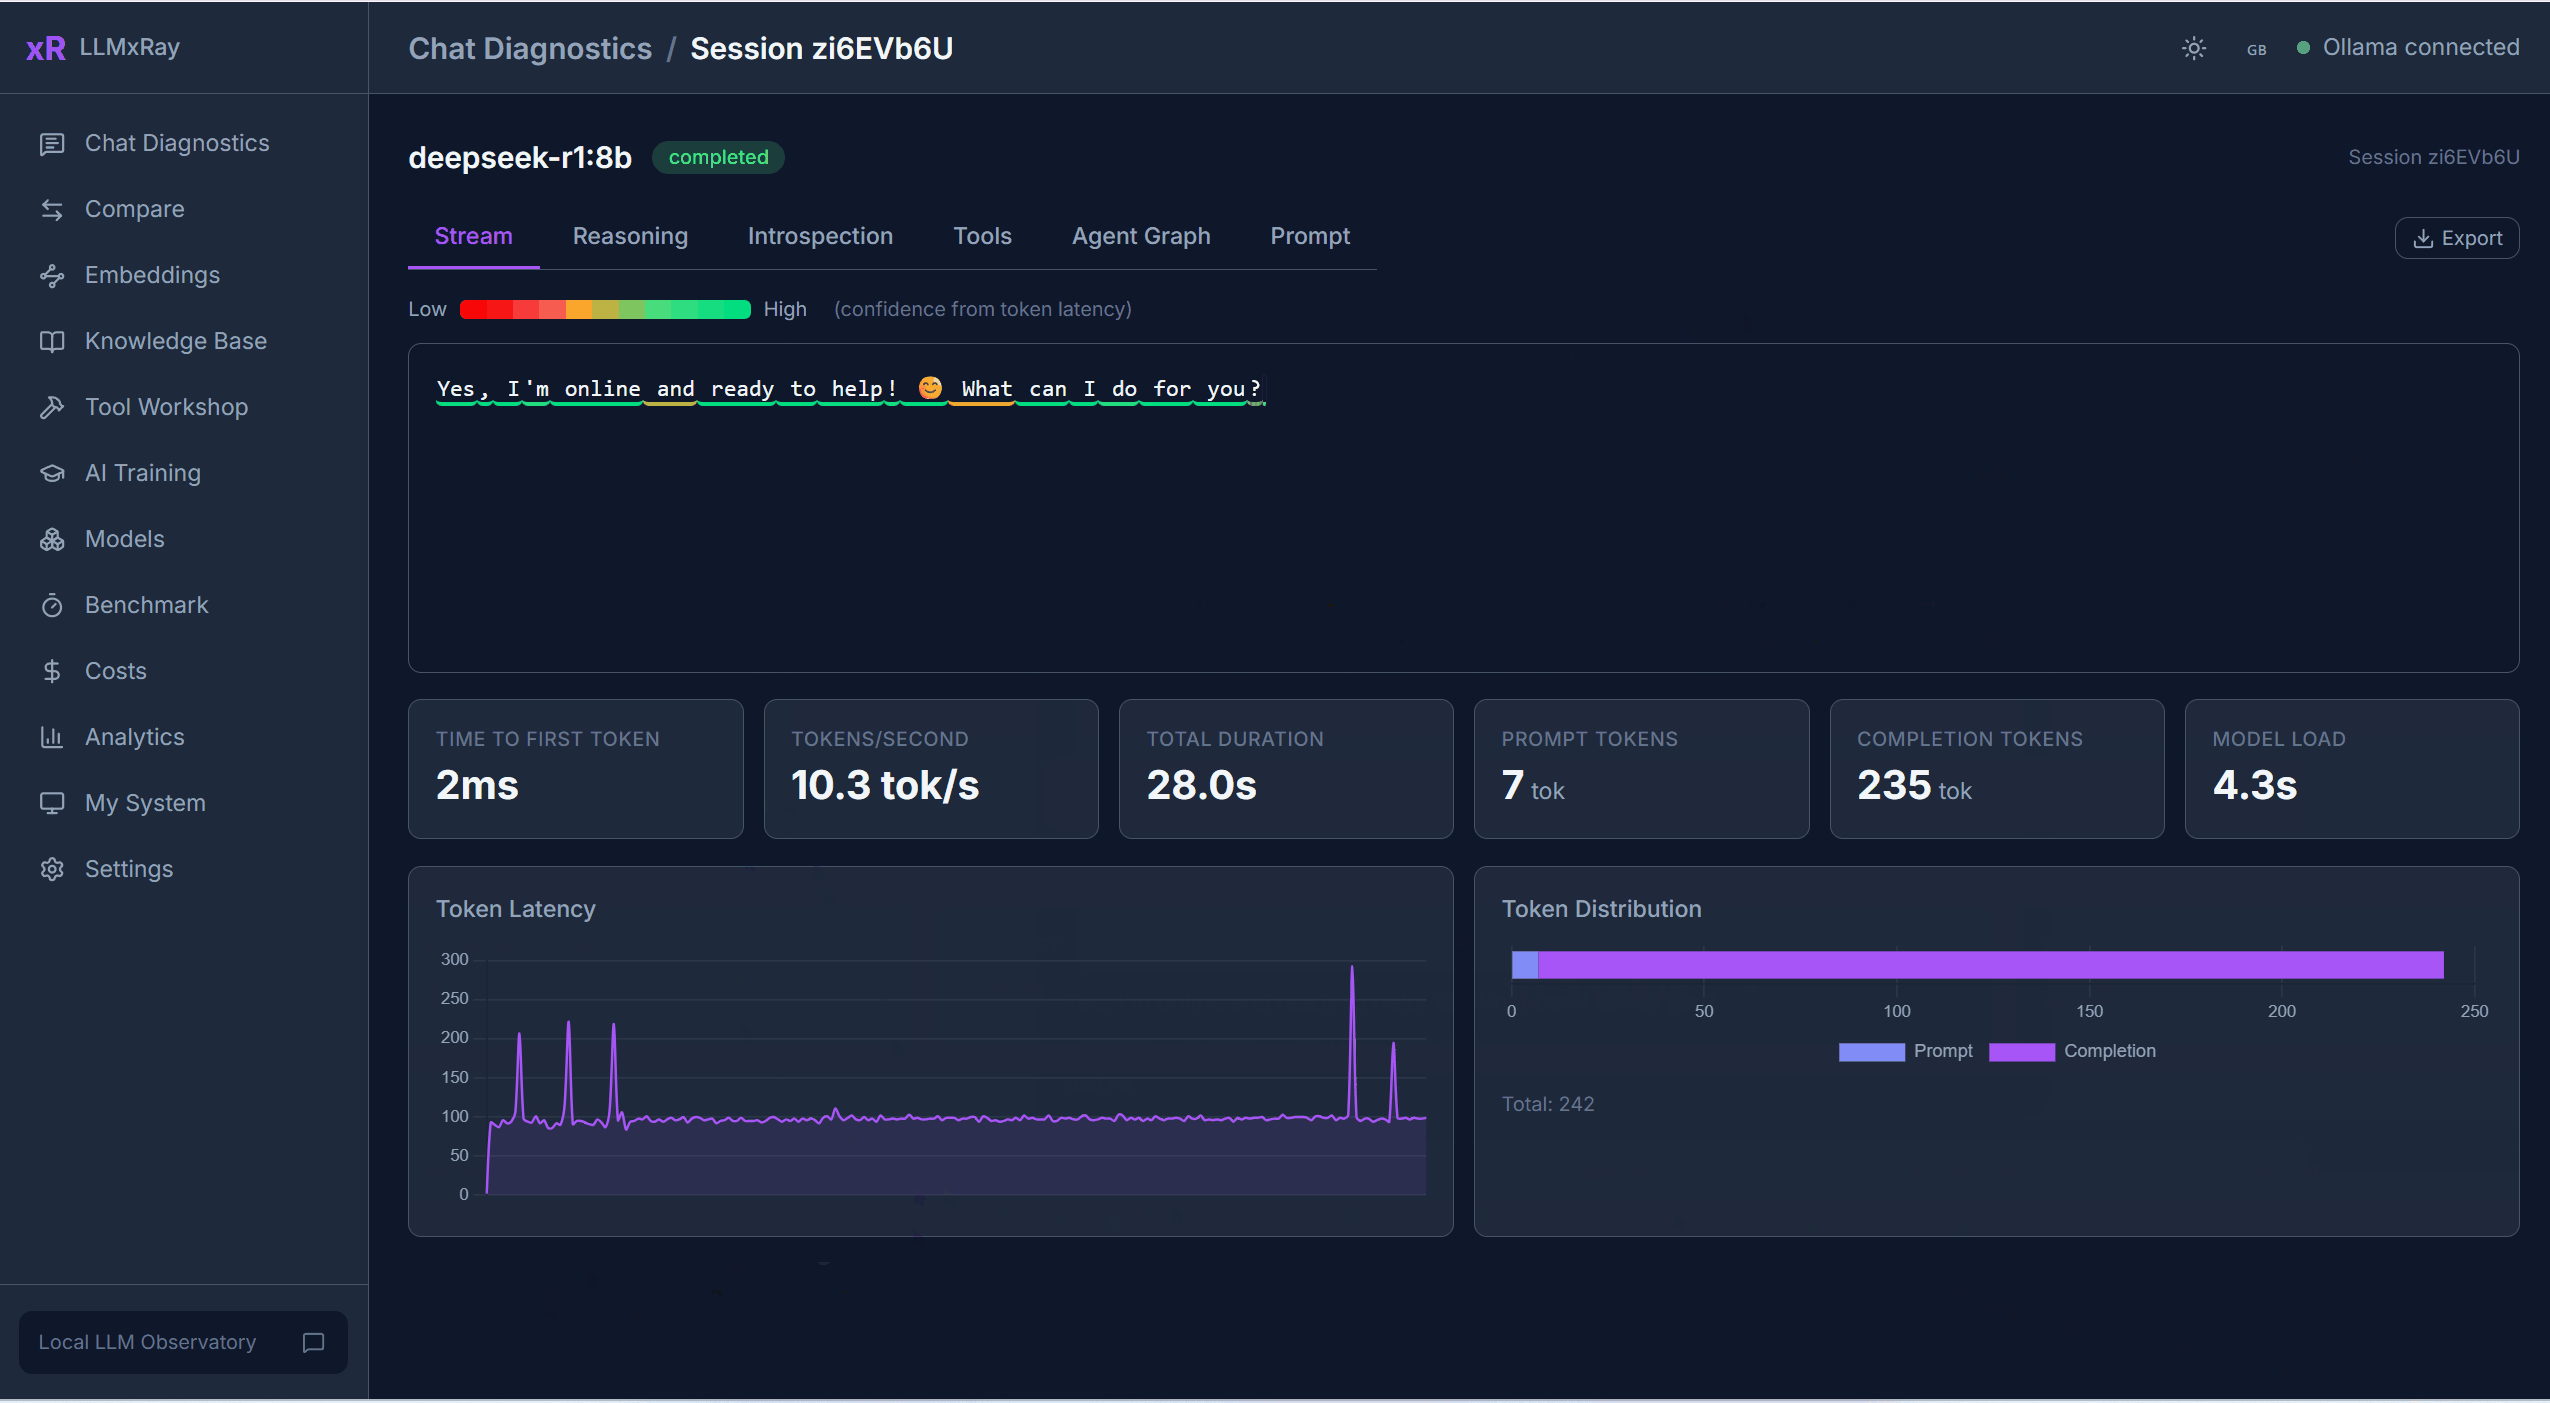
Session deep dive
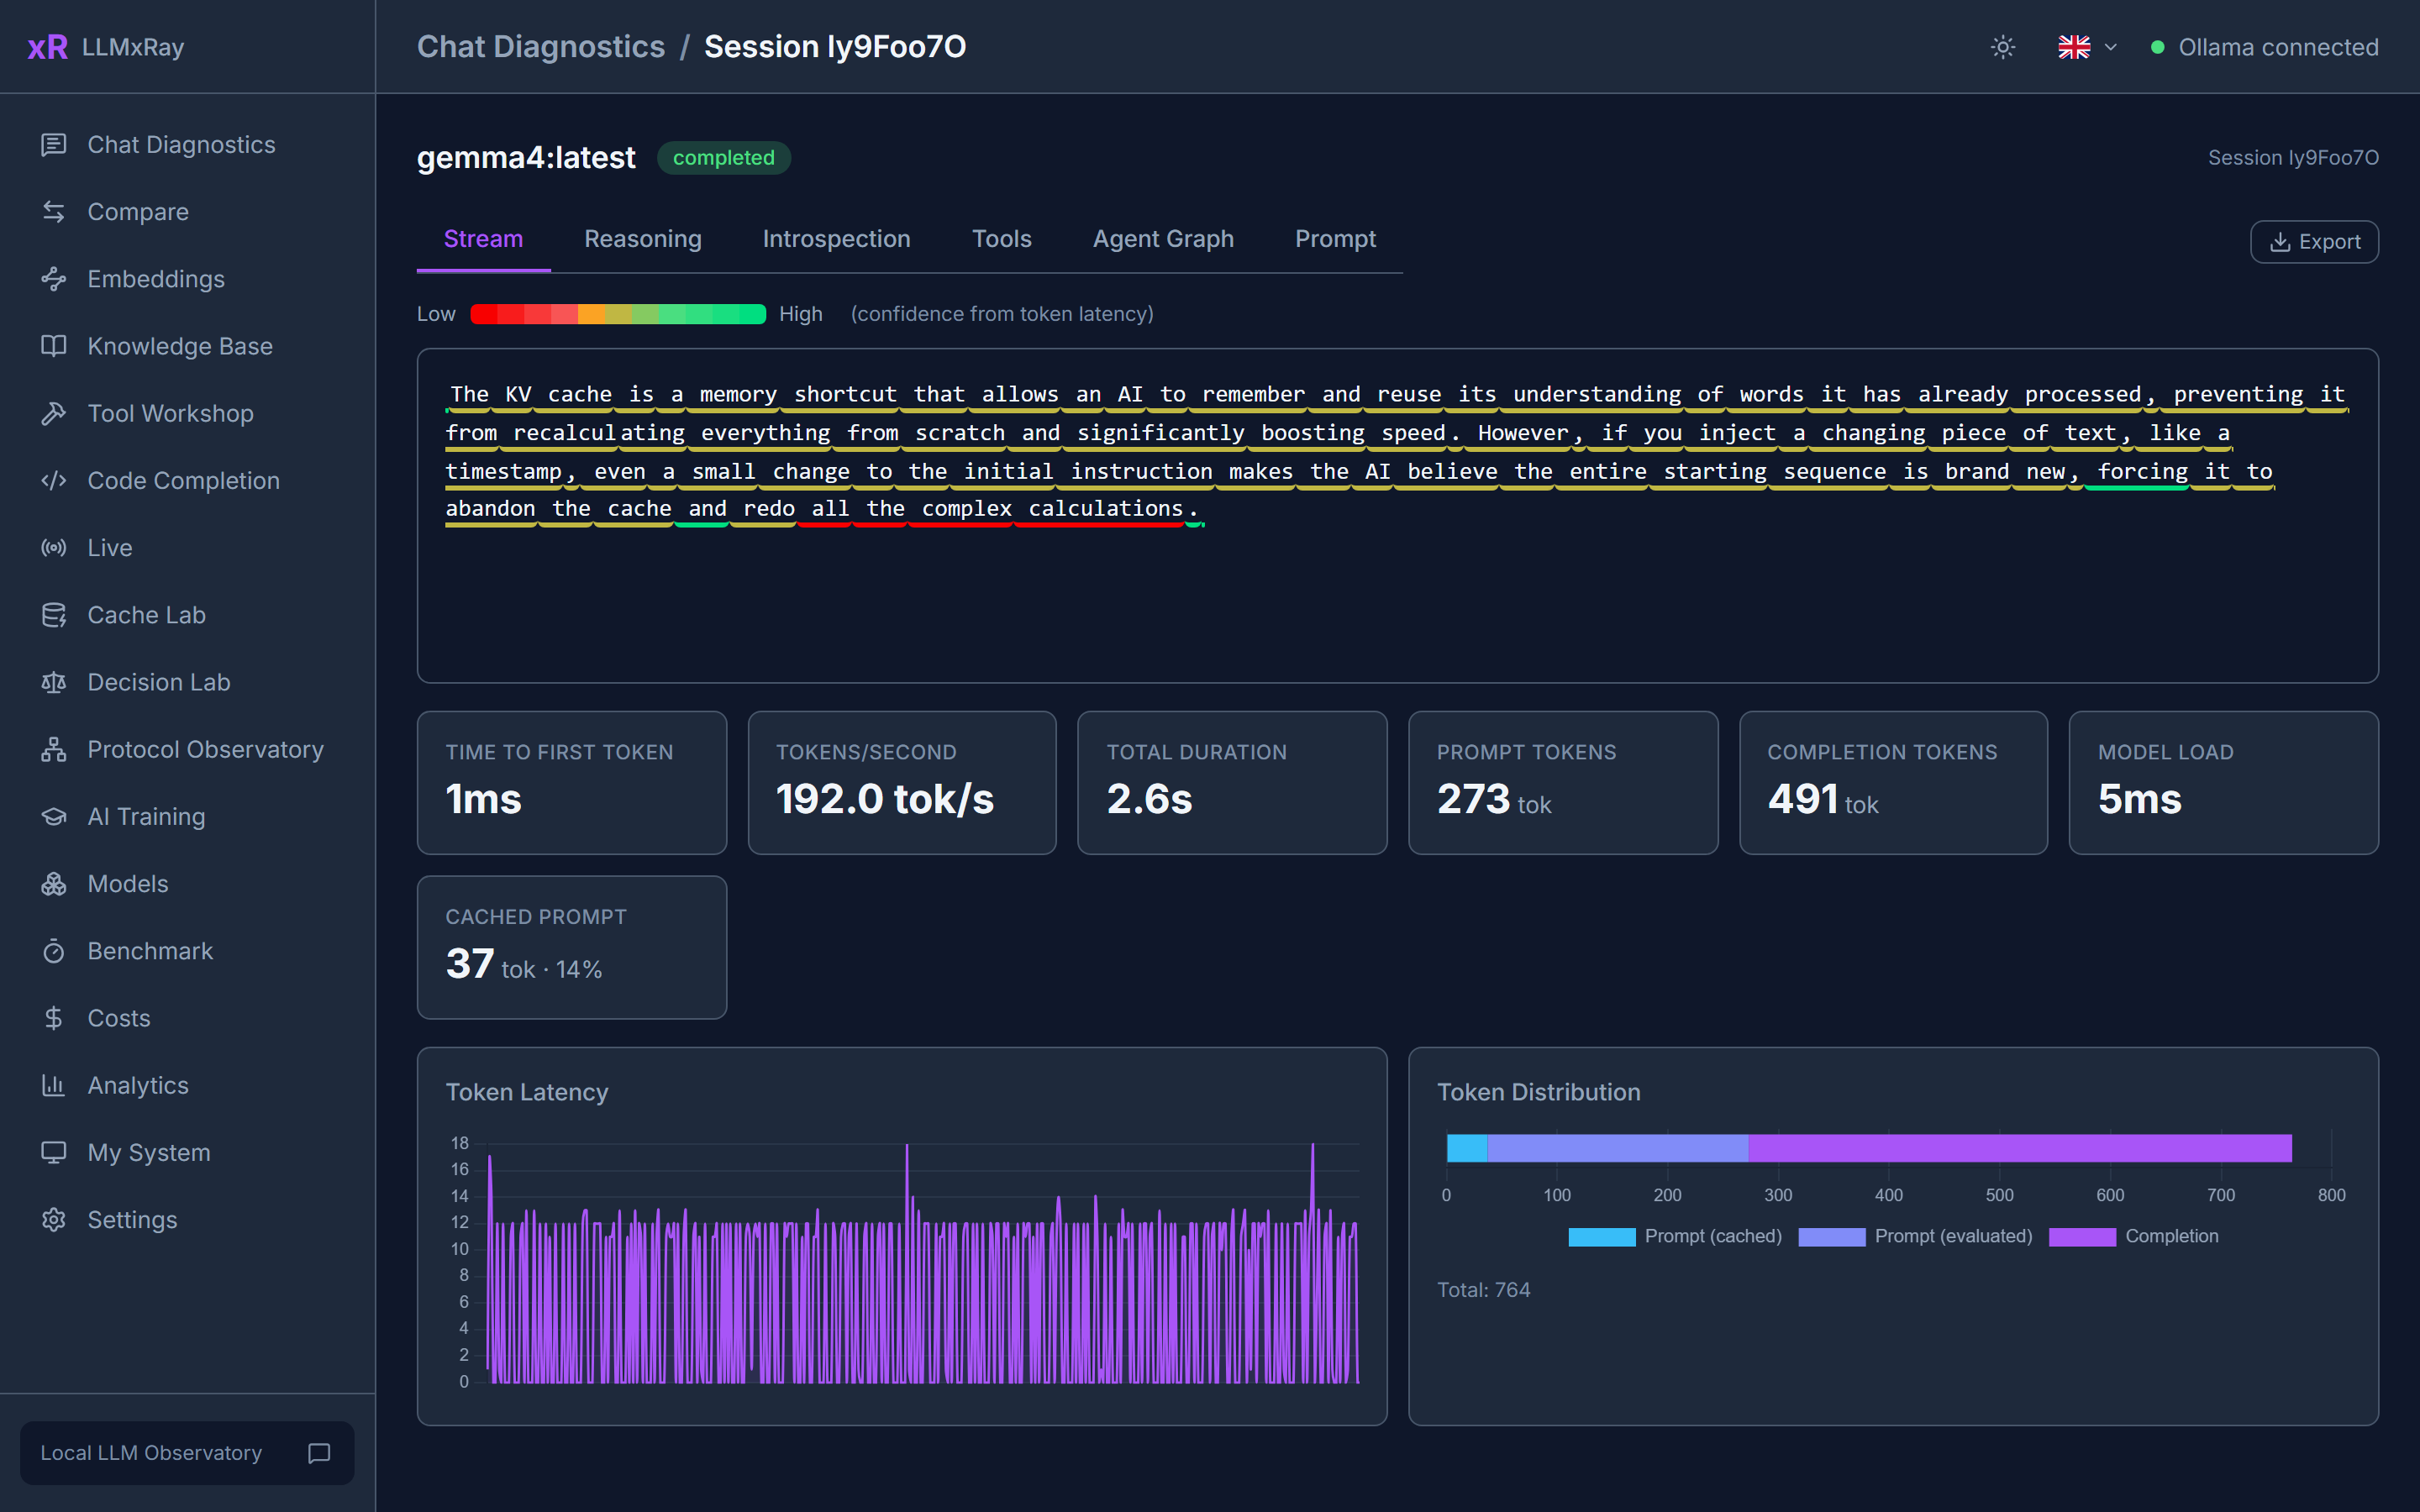
Open any turn to see it as a timeline: time to first token, inter-token gaps, the reasoning block if there was one, tool calls, and the exact prompt that was sent.
Screenshot
Compare
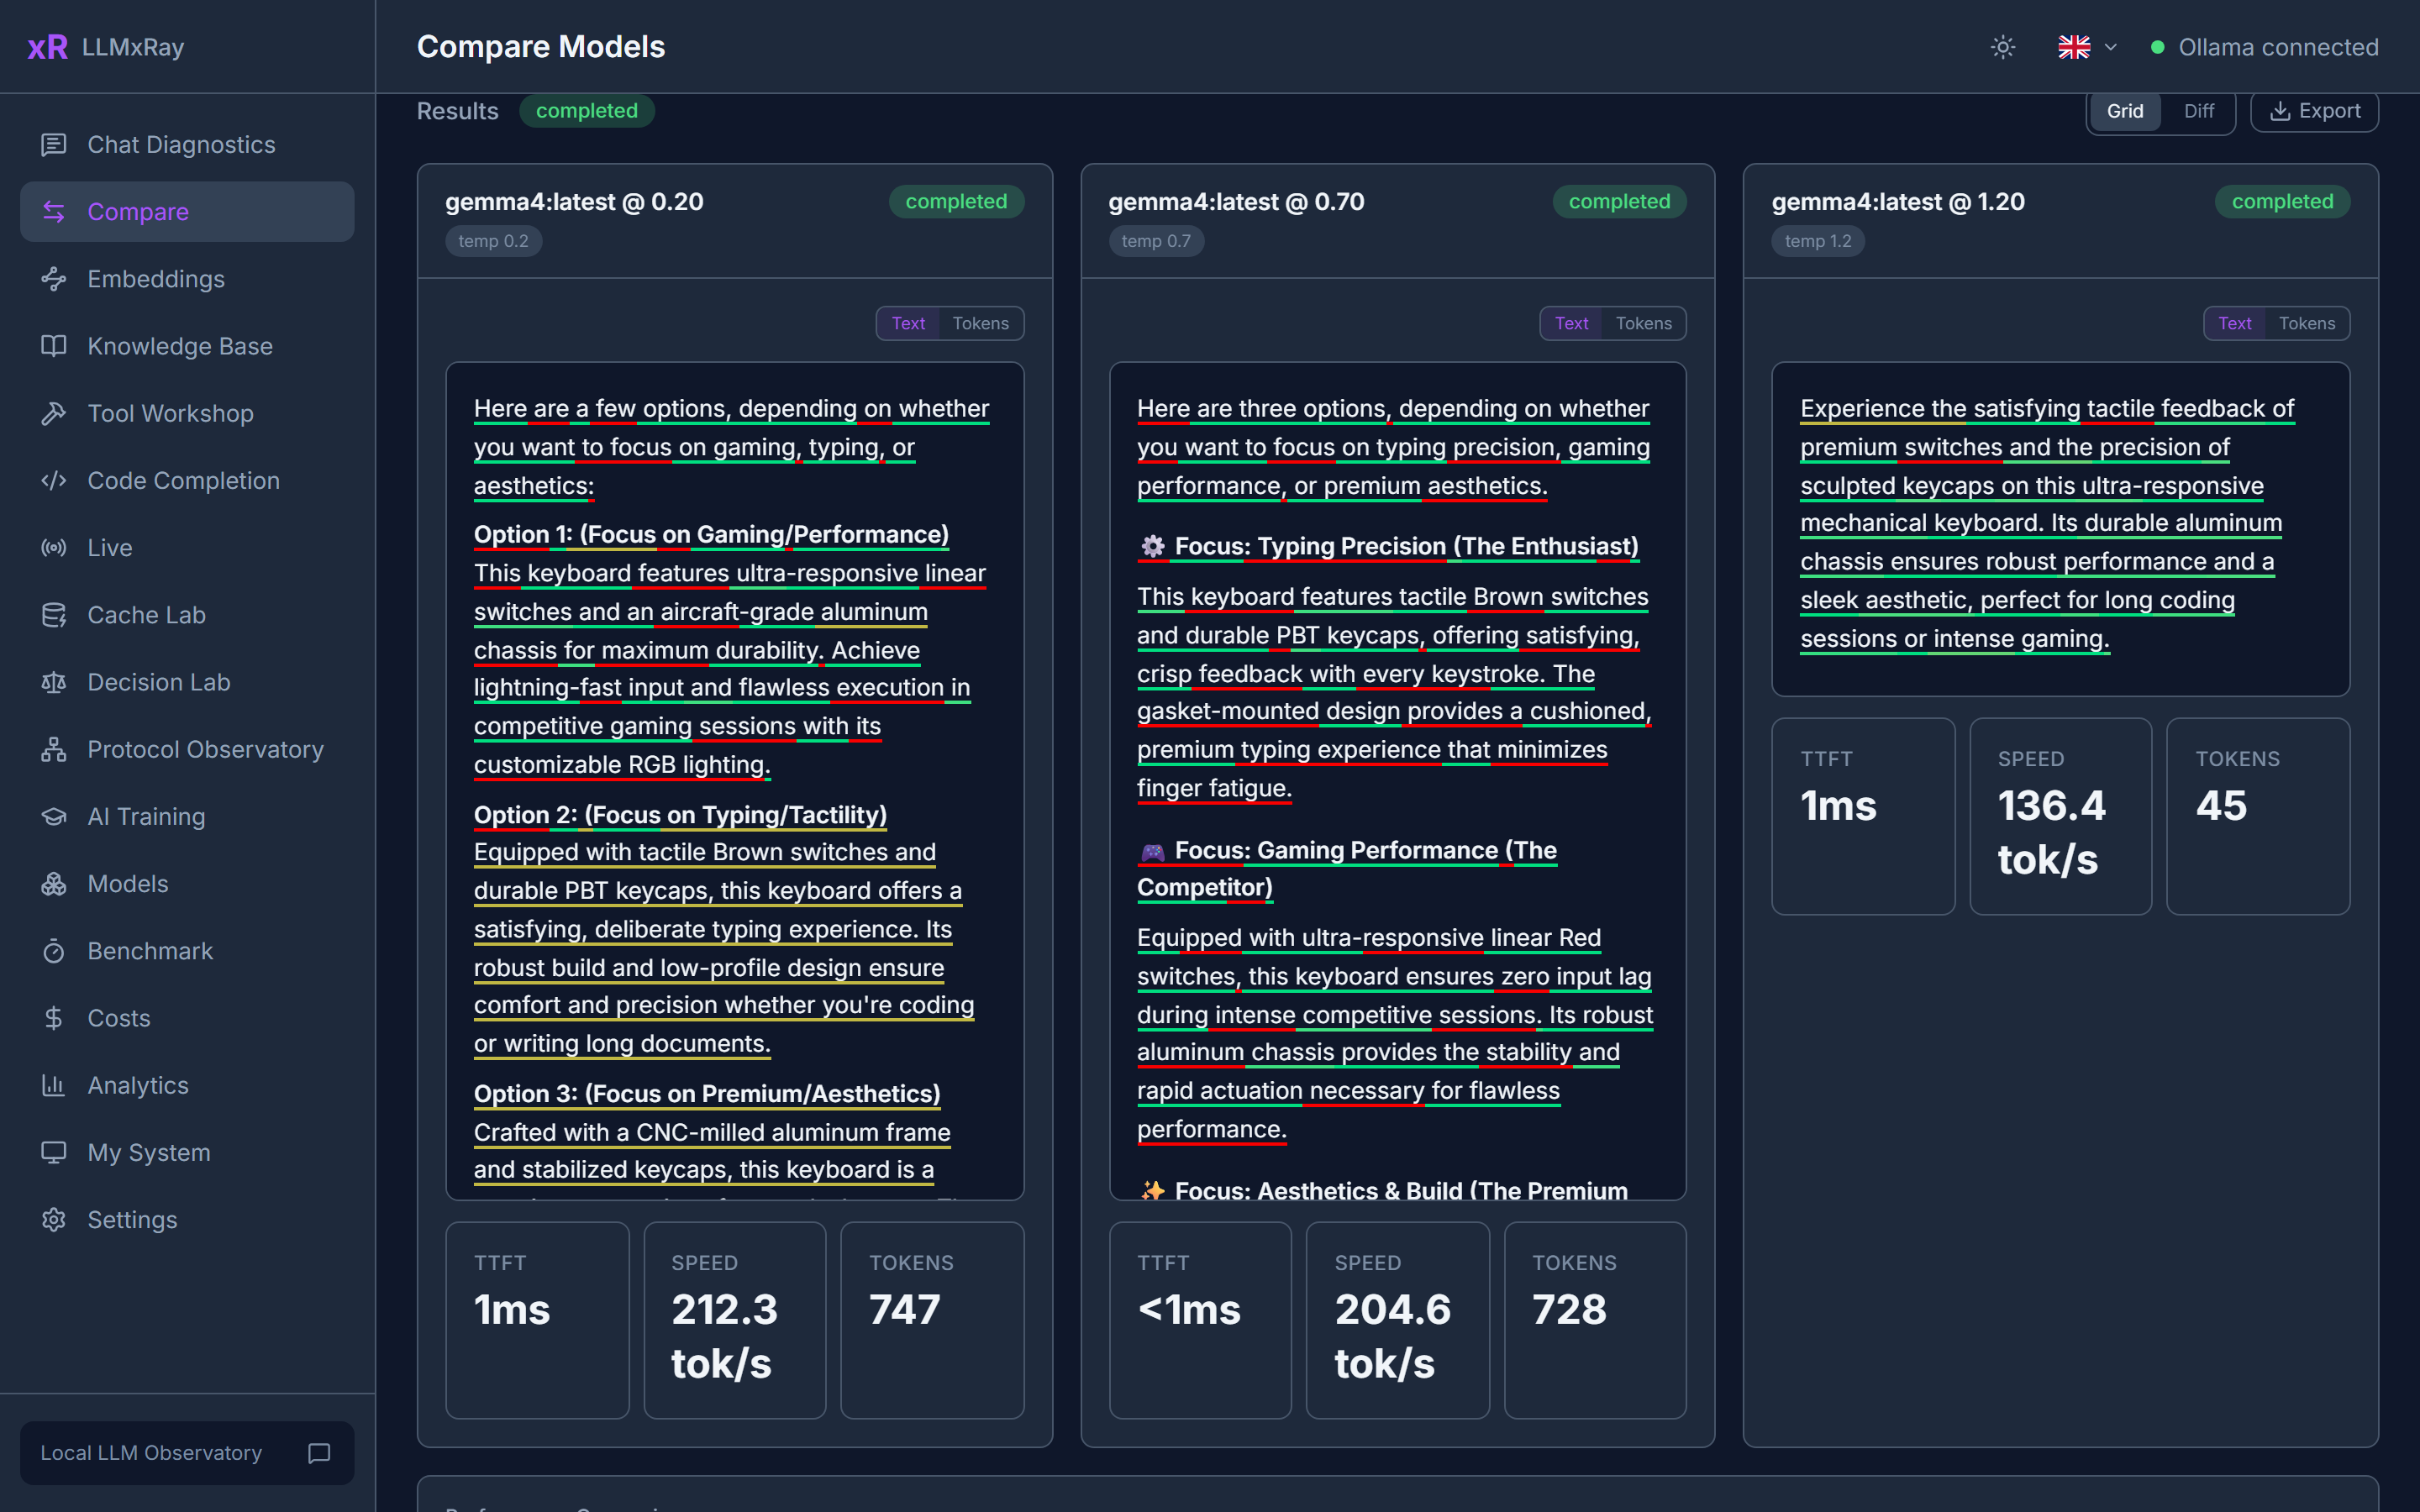
The same prompt against up to four slots, each with its own model, temperature and system prompt, streaming side by side. One-click presets: Temperature Sweep, Deterministic Pair, Language Compare. A word-level diff shows exactly what changed between two answers.
Screenshot
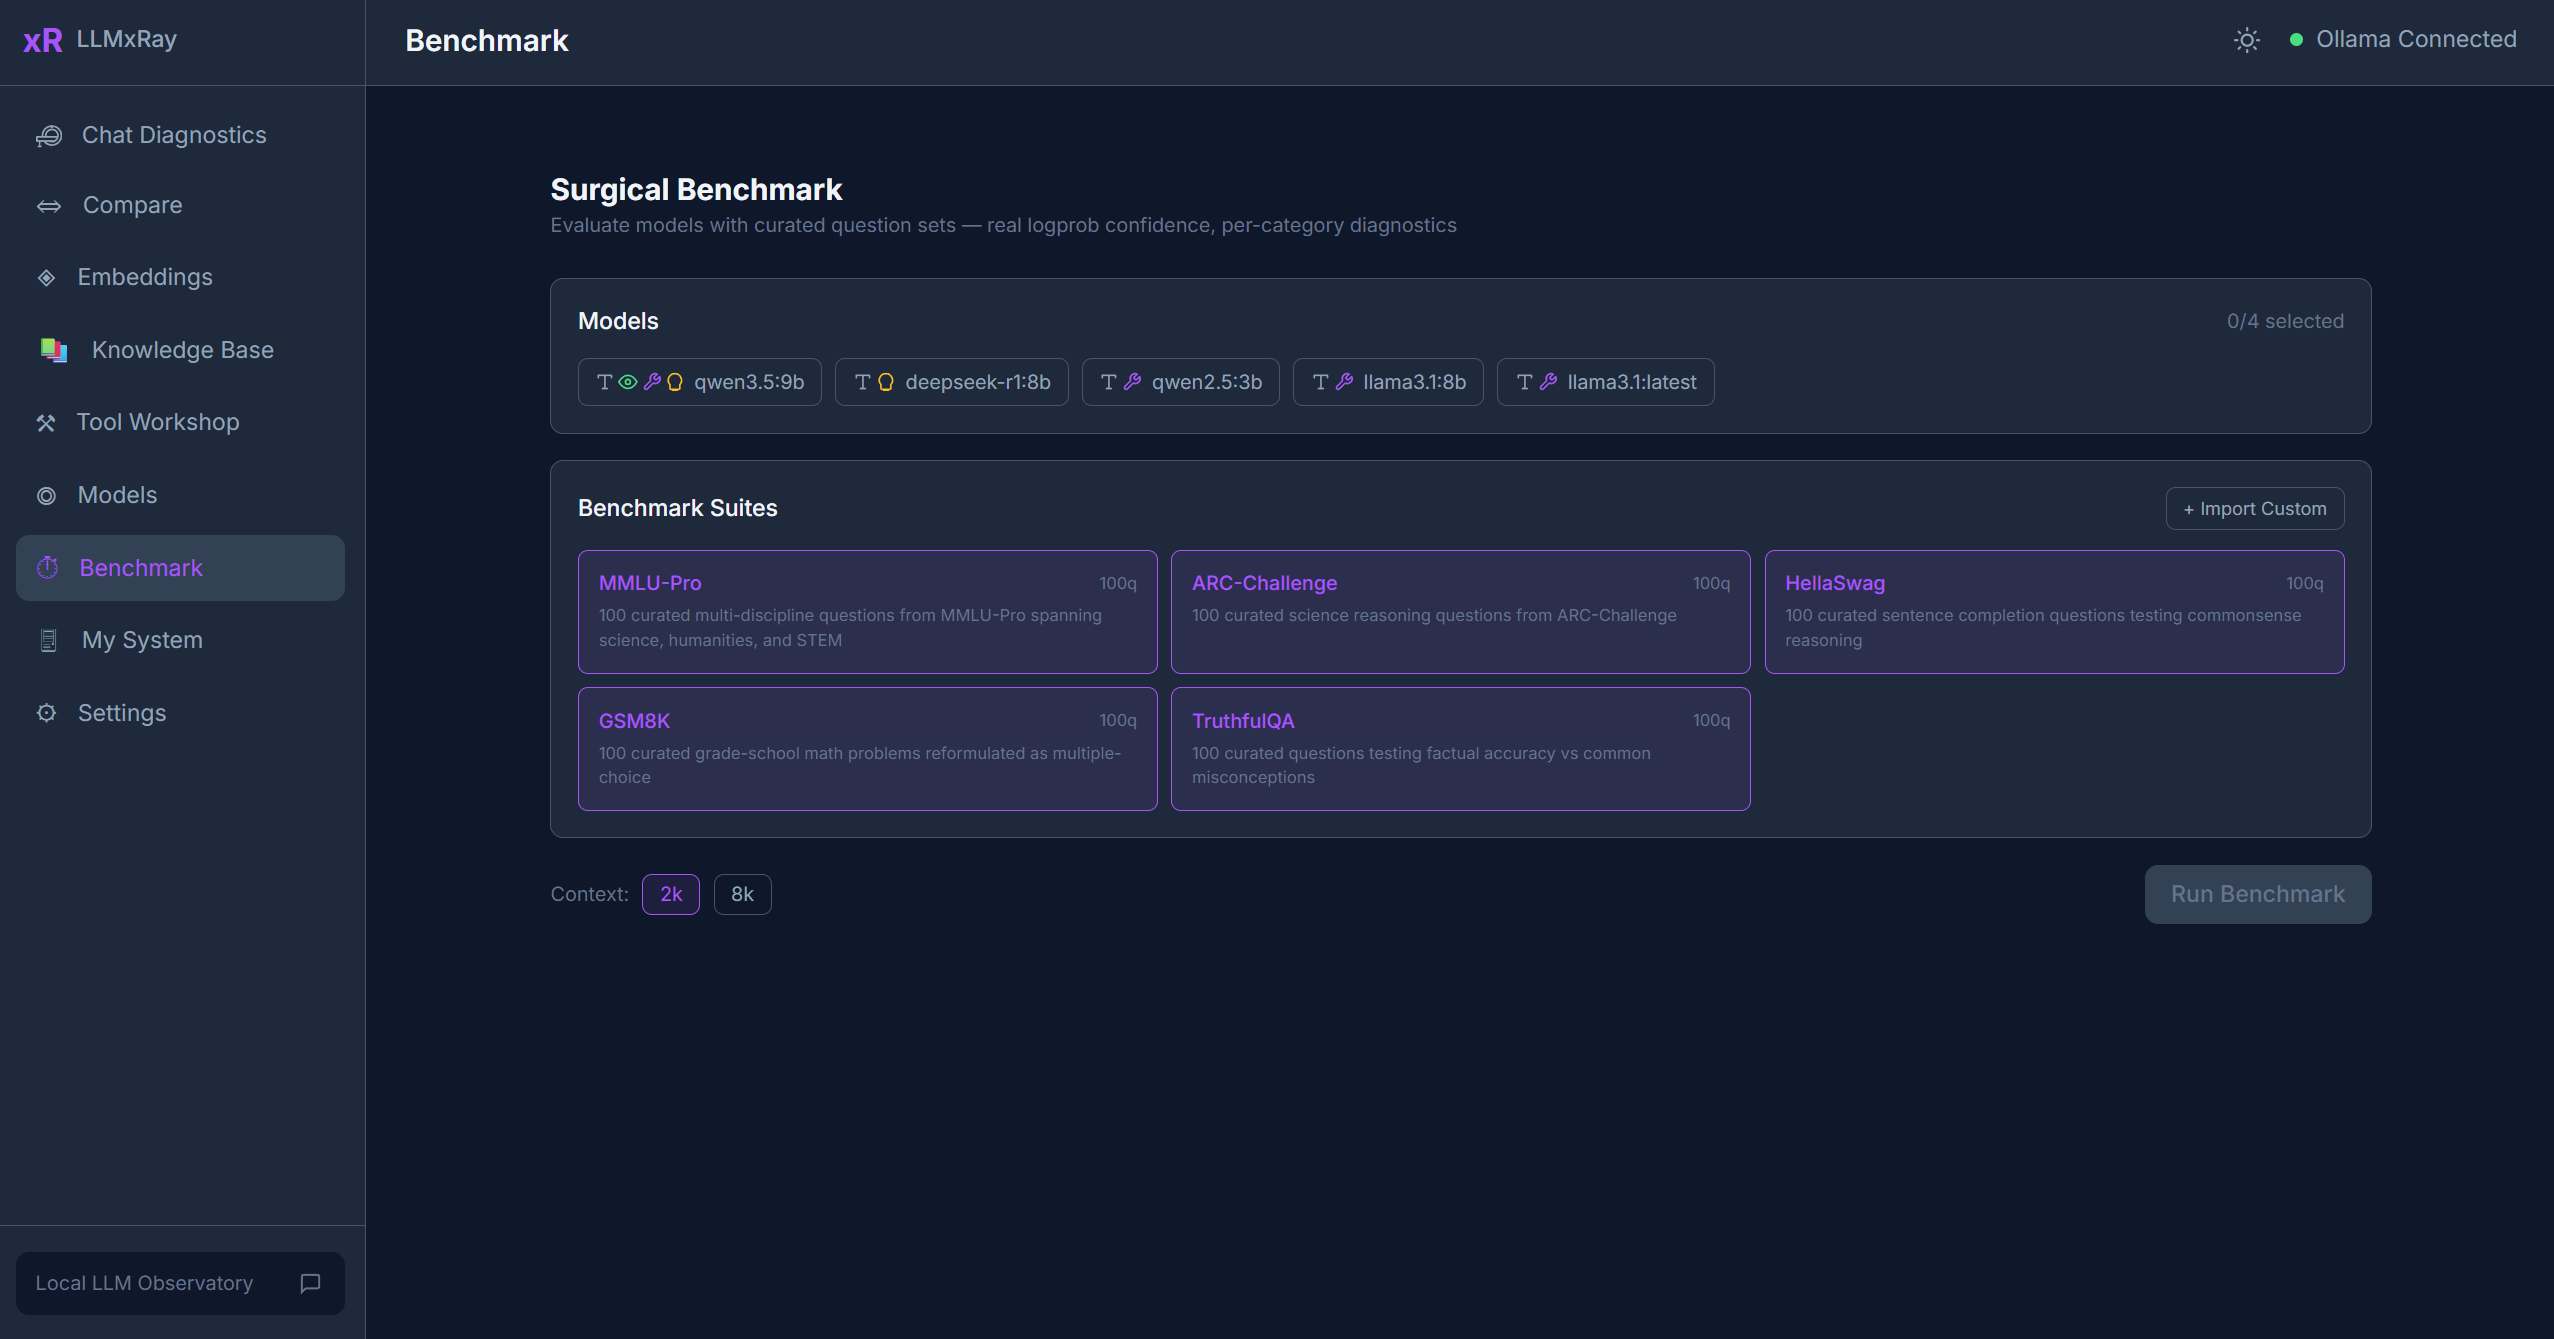
Surgical Benchmark
Score models on curated question suites (MMLU-Pro, ARC-Challenge, HellaSwag, GSM8K, TruthfulQA) using the model's real token logprobs, not whether the answer happened to look right. Confidence versus accuracy per category, so you see where a model is confidently wrong. Import your own suites as JSON.
Screenshot
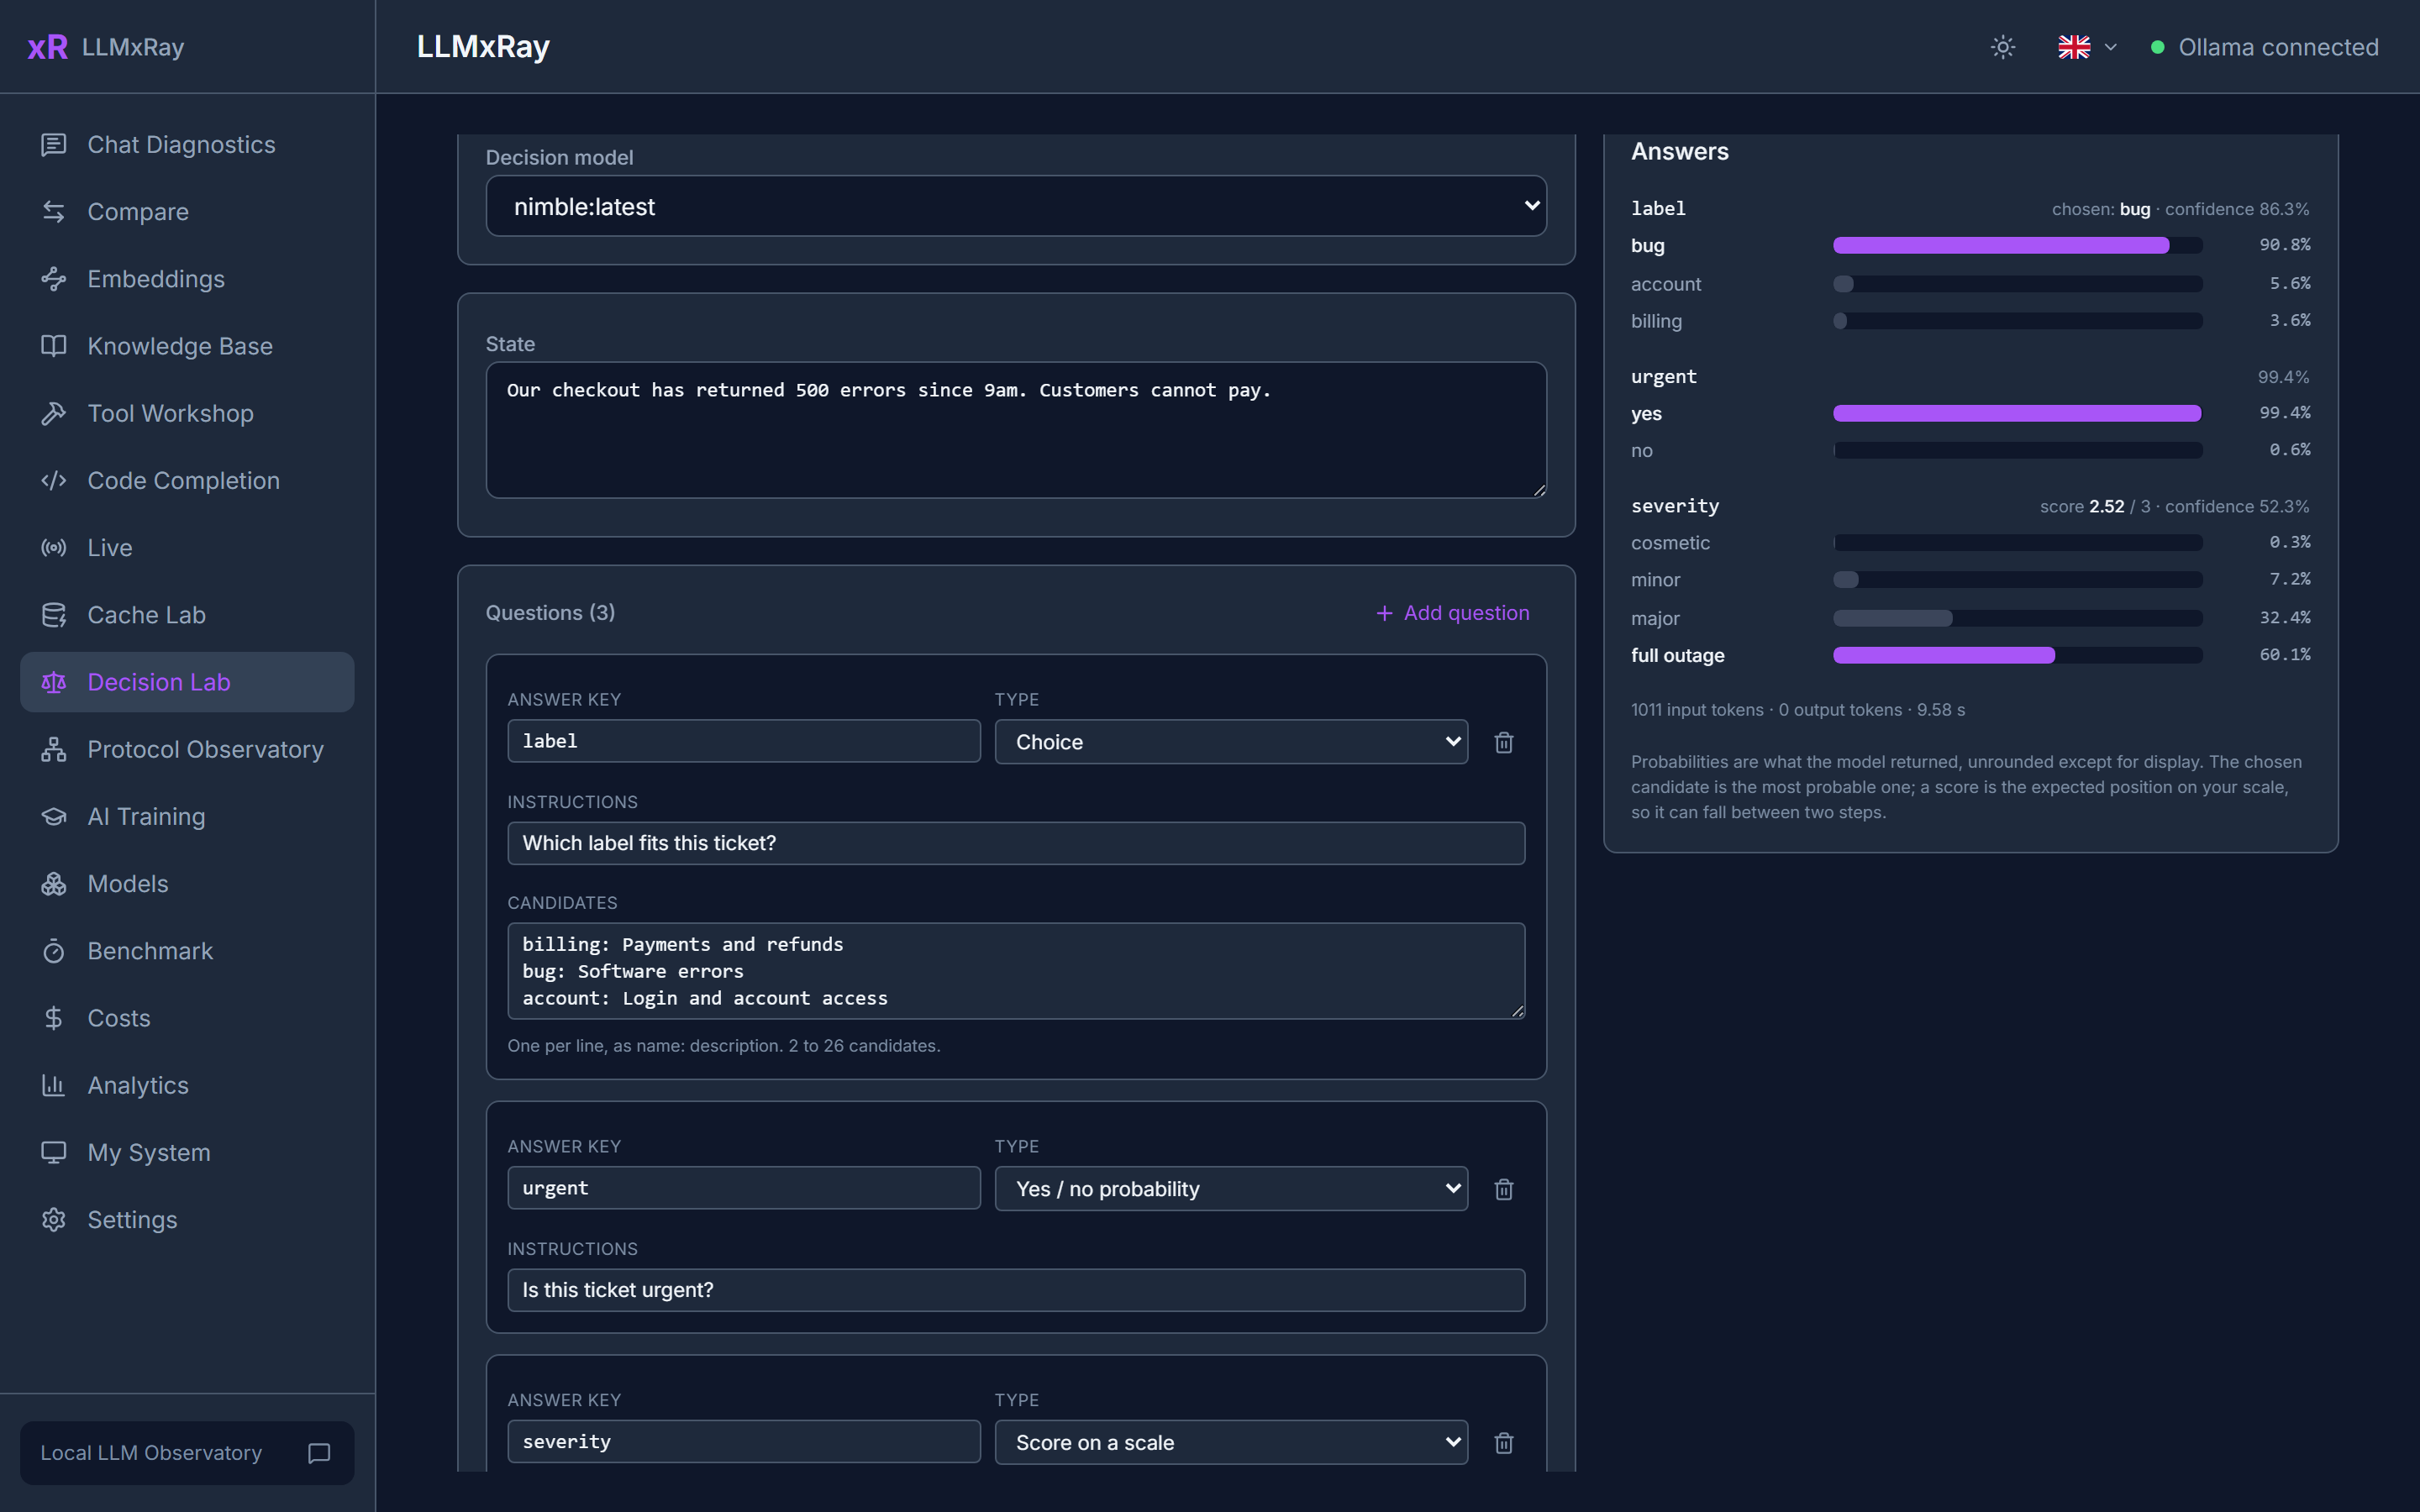
Decision Lab
Decision models (nimble, tev1, clef) answer typed questions with probabilities instead of prose. Give the lab a situation and ask for a choice among candidates, a yes/no probability, or a score on a scale. Every answer comes back as the model's own distribution, drawn as bars.
Screenshot
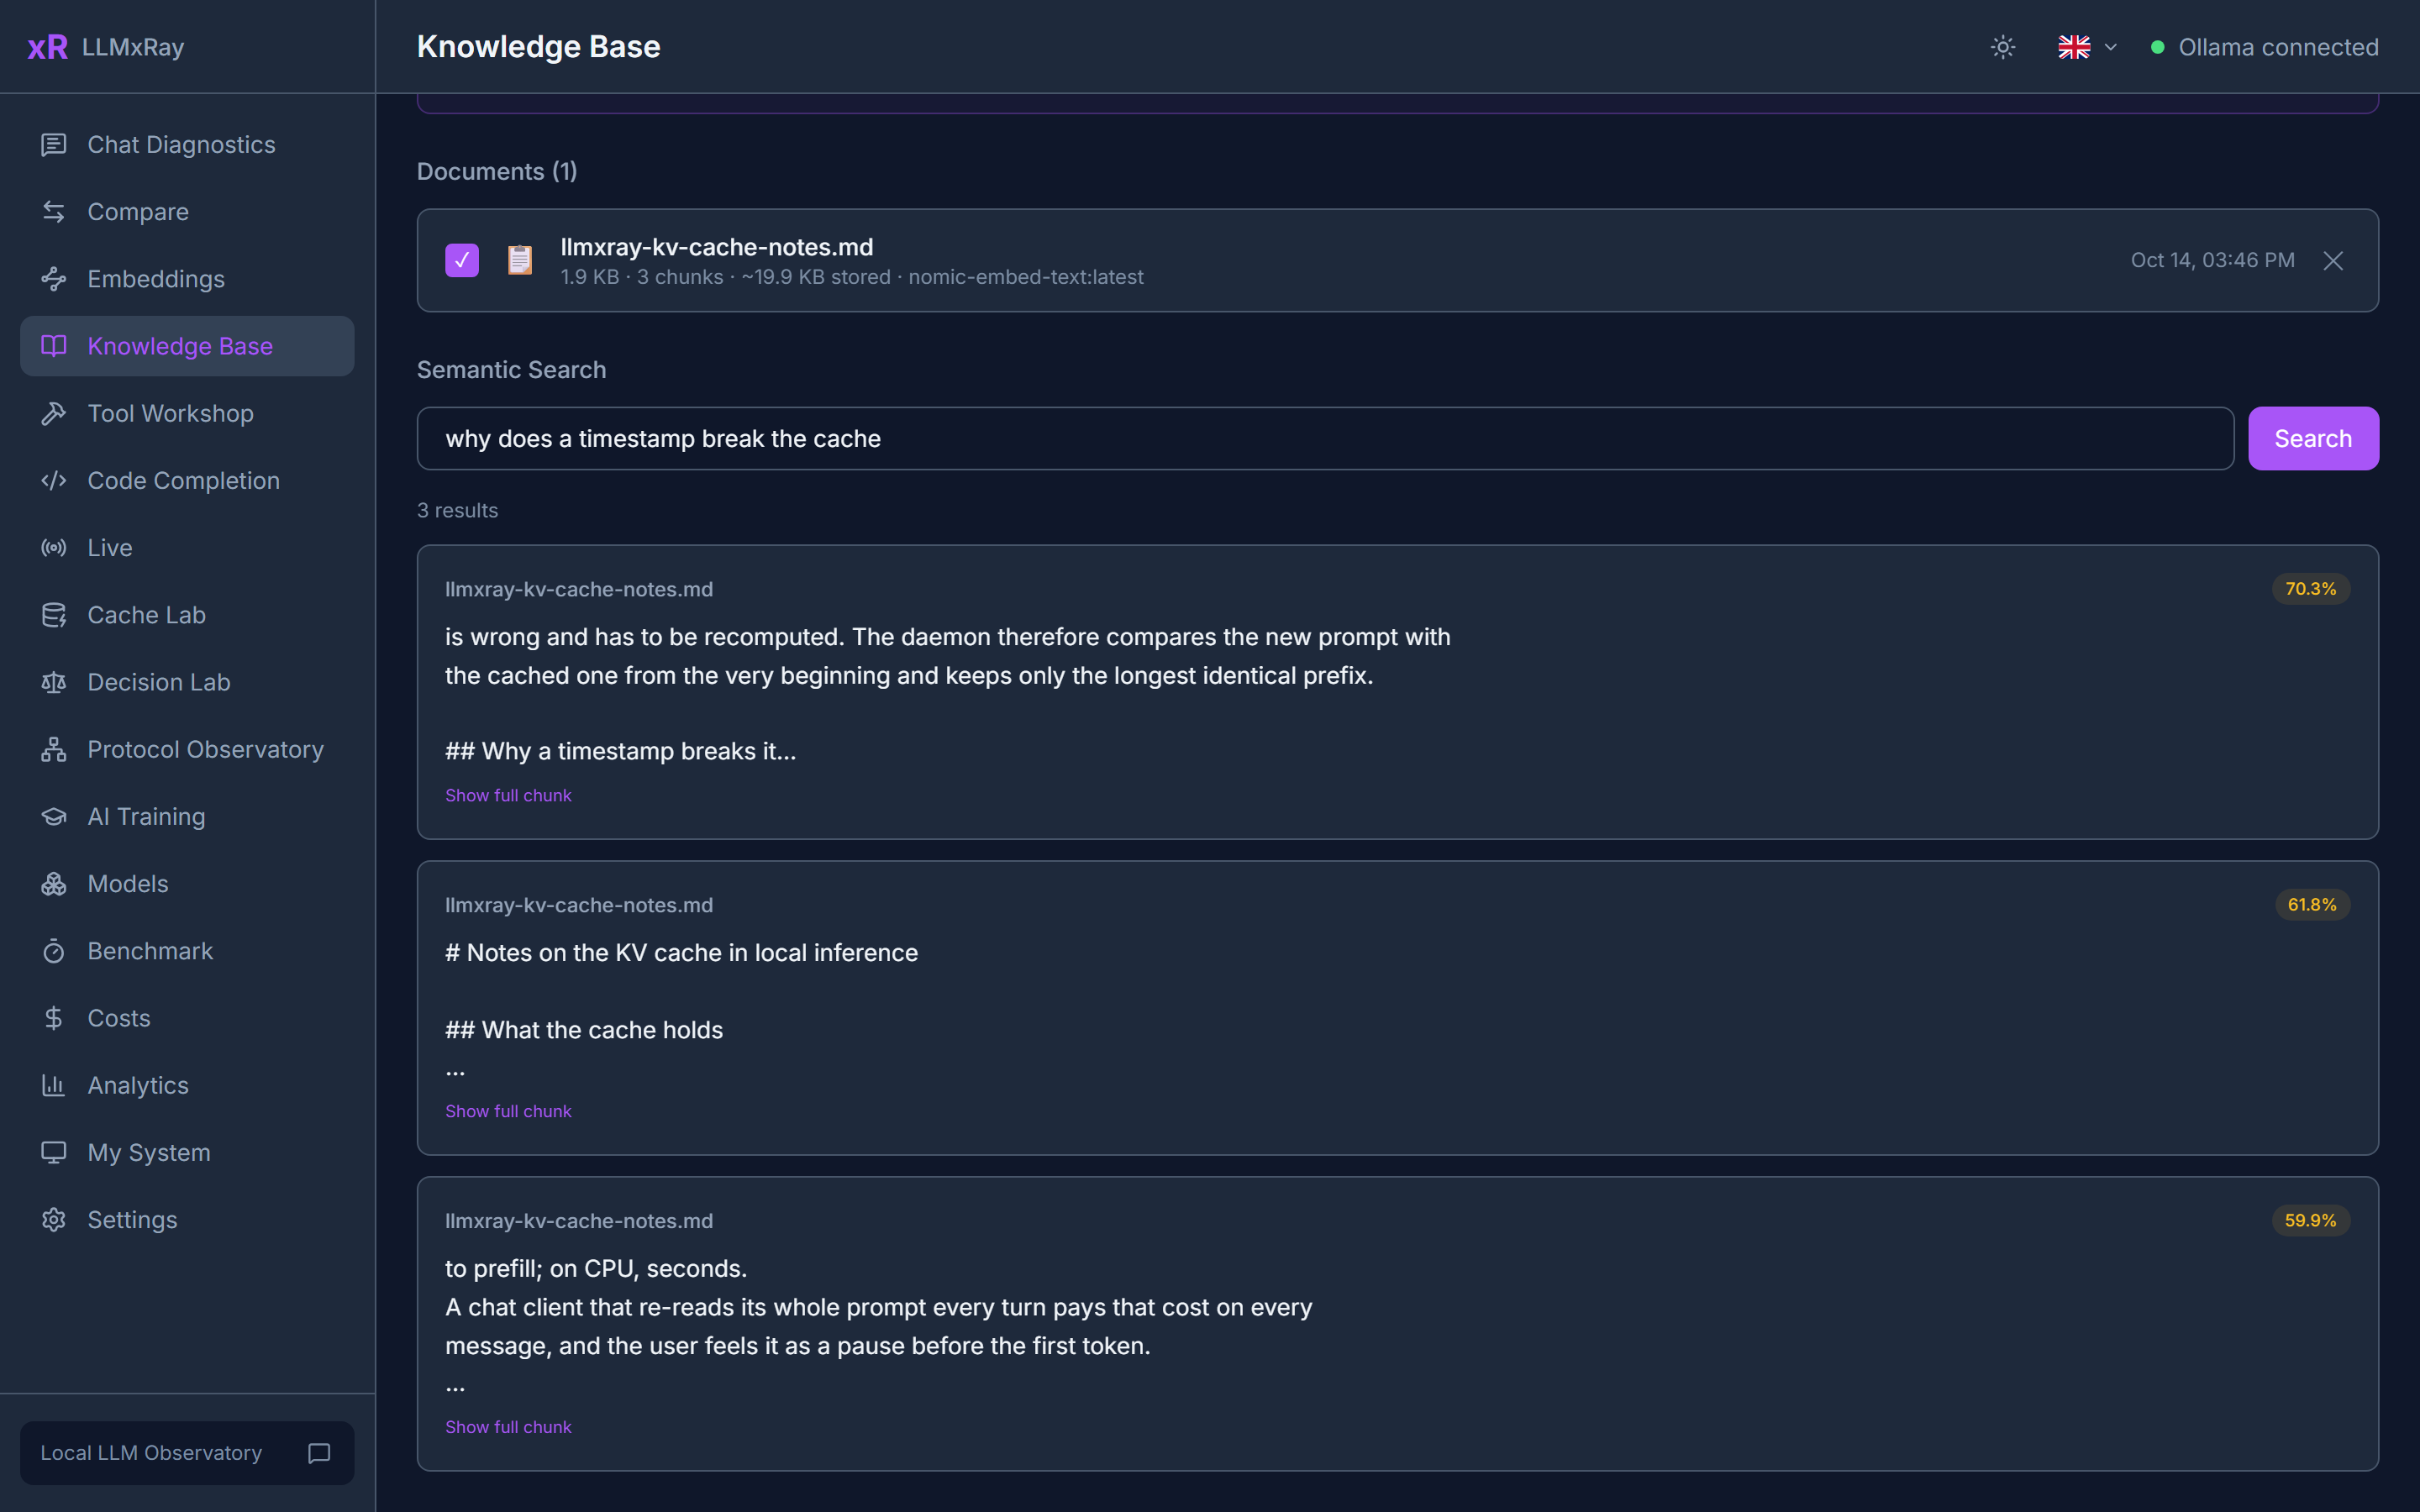
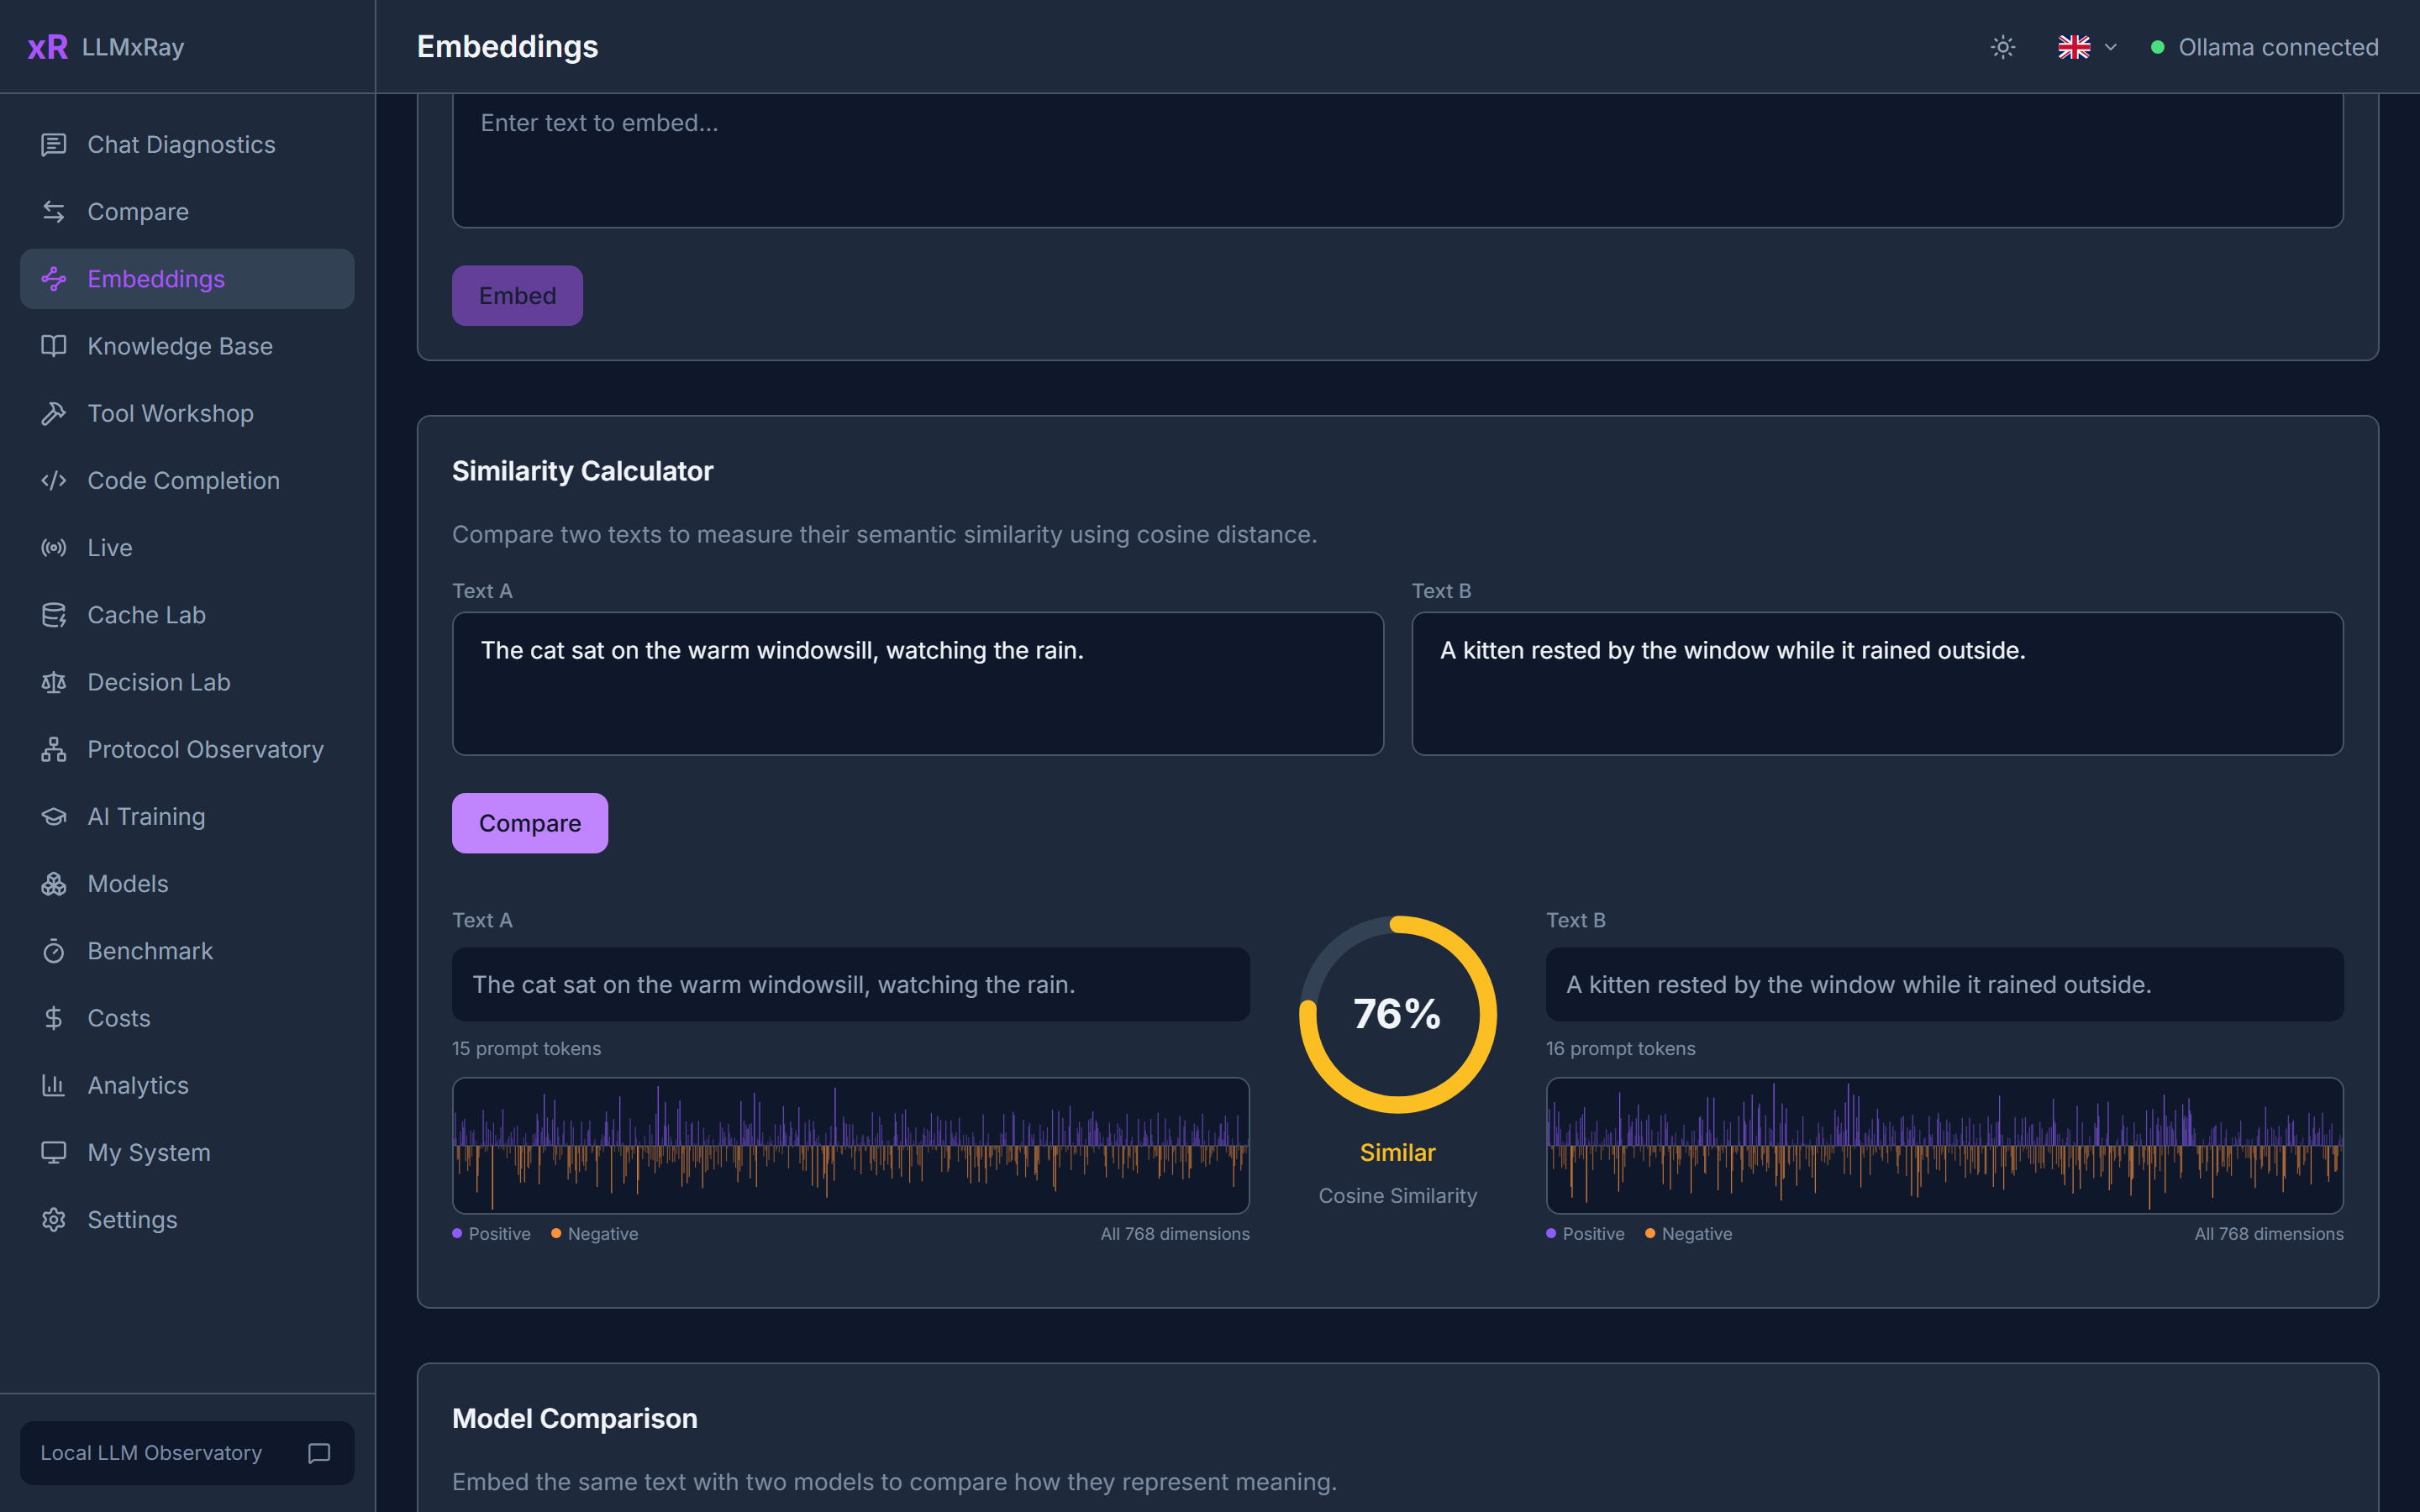
Knowledge Base and Embeddings
Drop in PDF, DOCX, Markdown or CSV files. They are chunked, embedded and searchable, so you see what retrieval actually returns before a model ever sees it. The Embeddings page lets you compare any two texts by cosine similarity, visualise the vectors, and see what Matryoshka truncation costs.
Everything stays in your browser's IndexedDB.
Screenshot
|
|
|
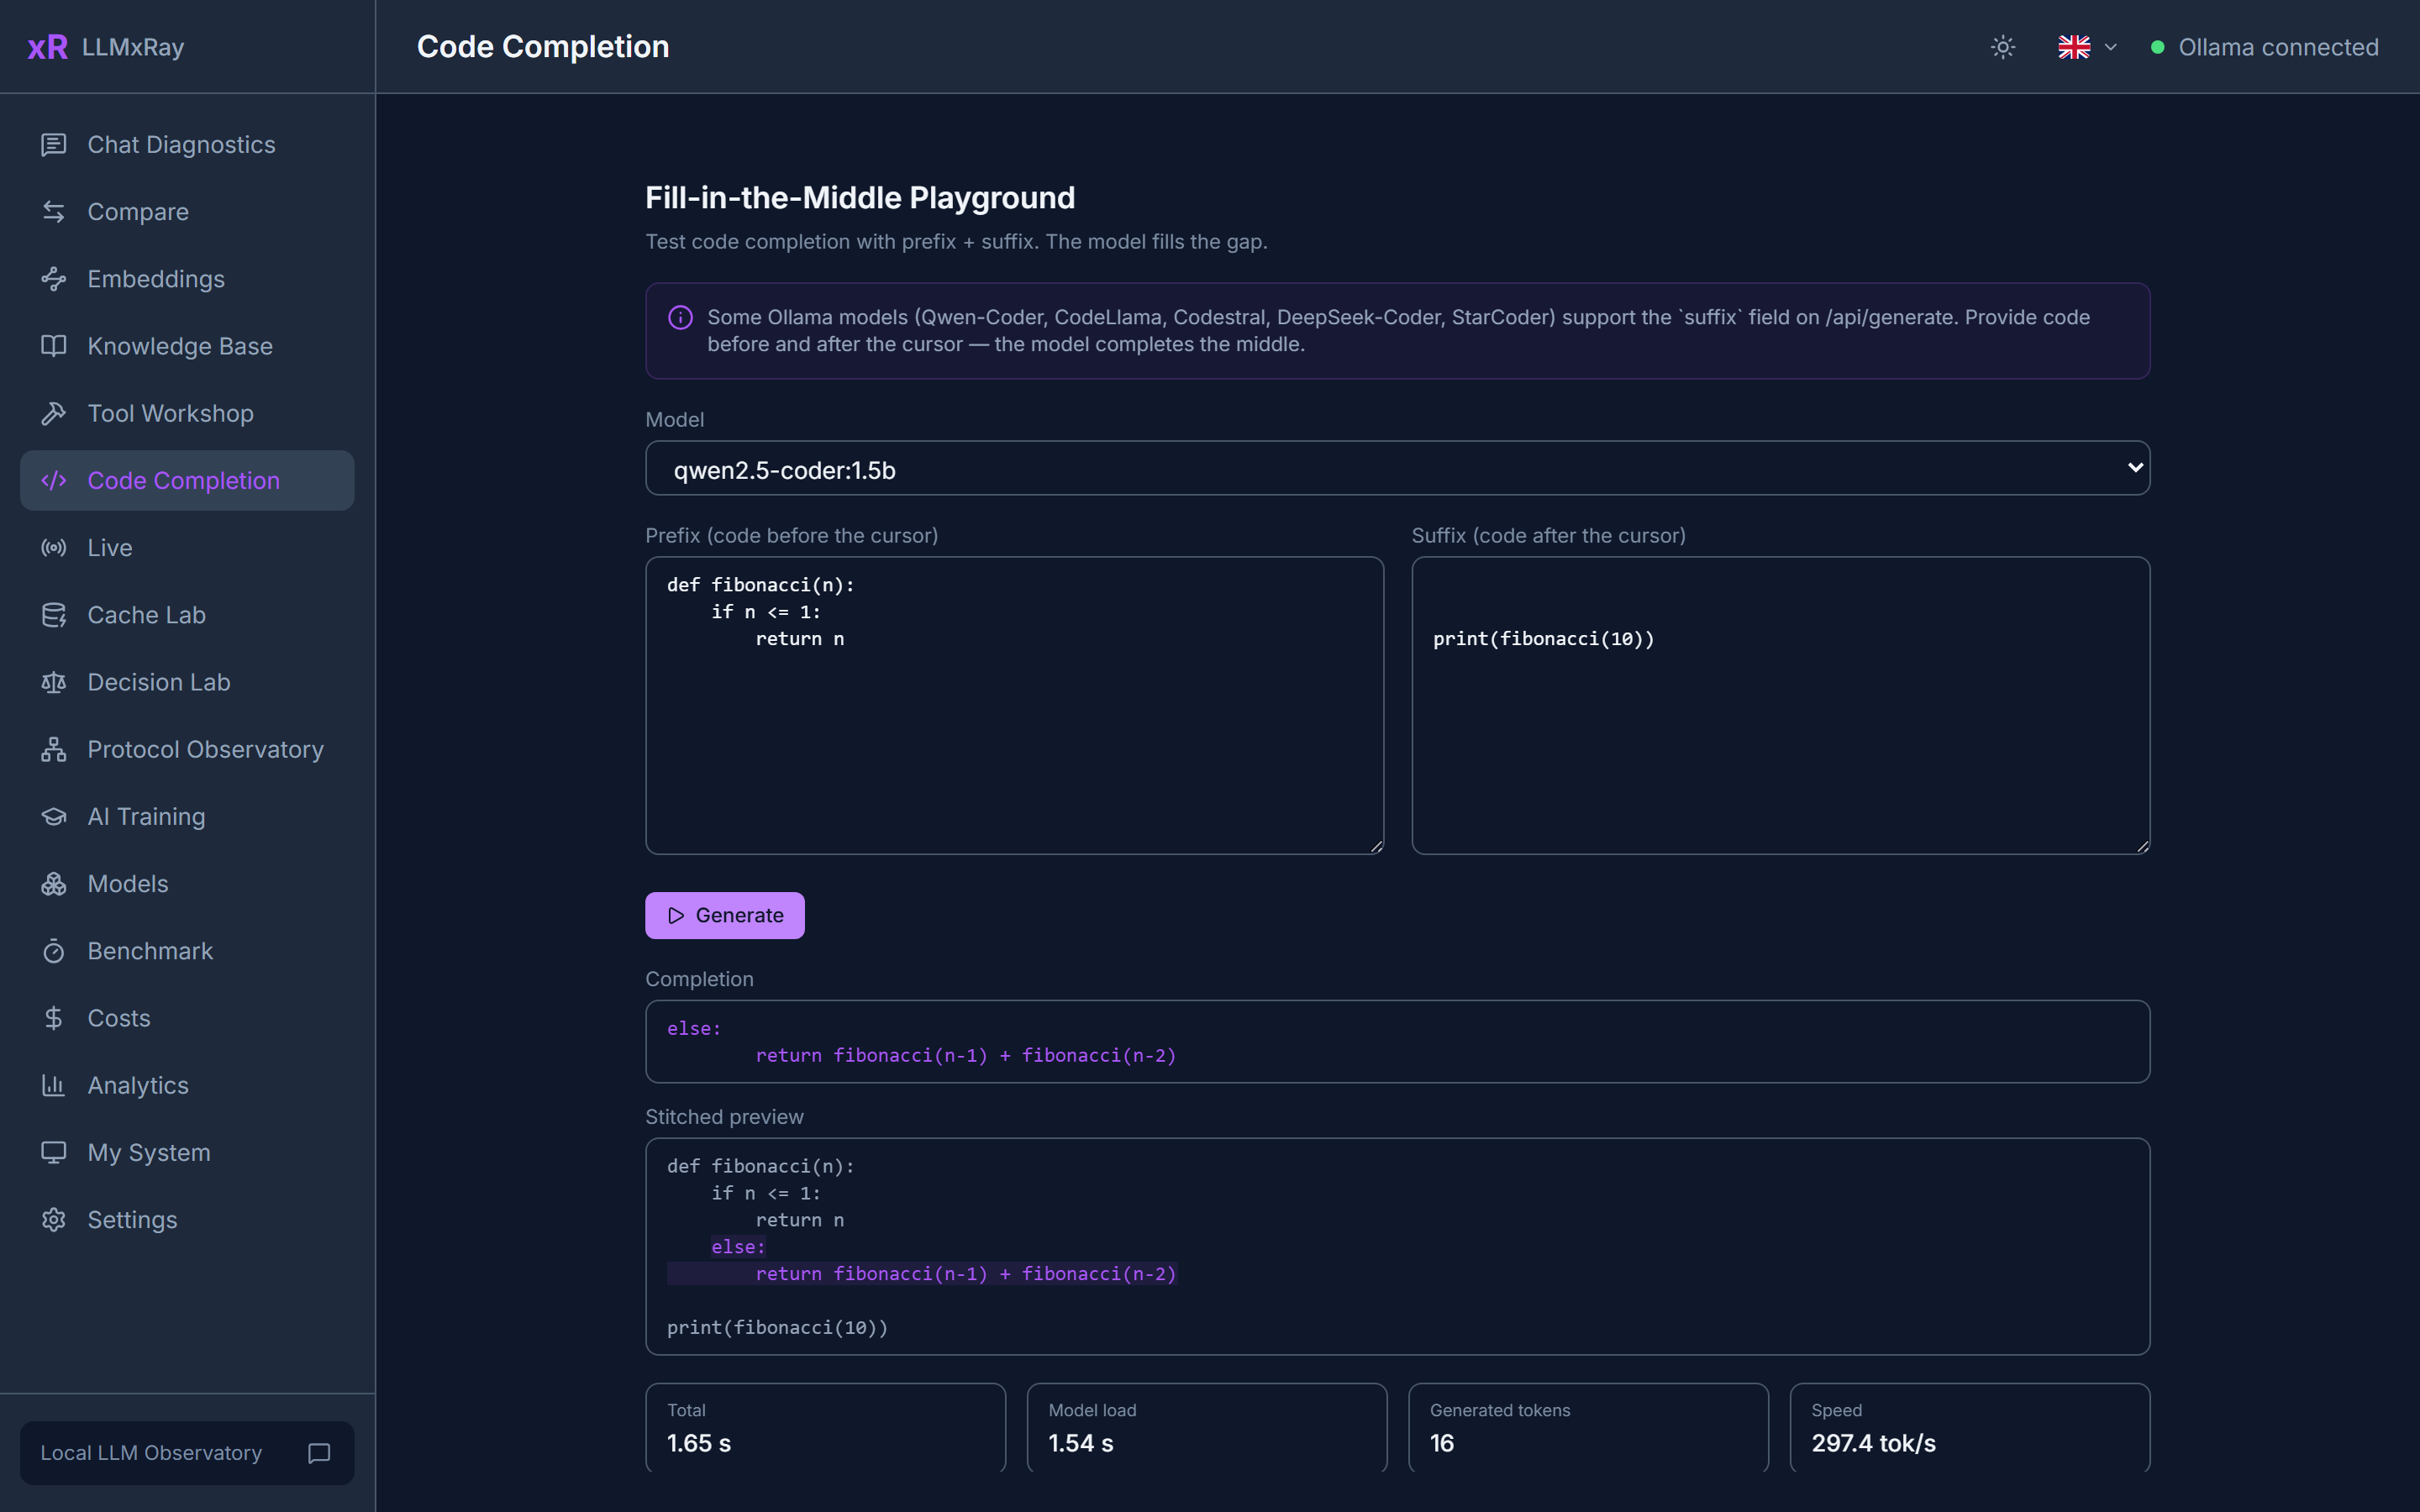
Code Completion
Fill-in-the-middle for Qwen-Coder, CodeLlama, Codestral, DeepSeek-Coder and StarCoder: a prefix, a suffix, and the model fills the gap. The stitched preview shows the result as your editor would.
Screenshot
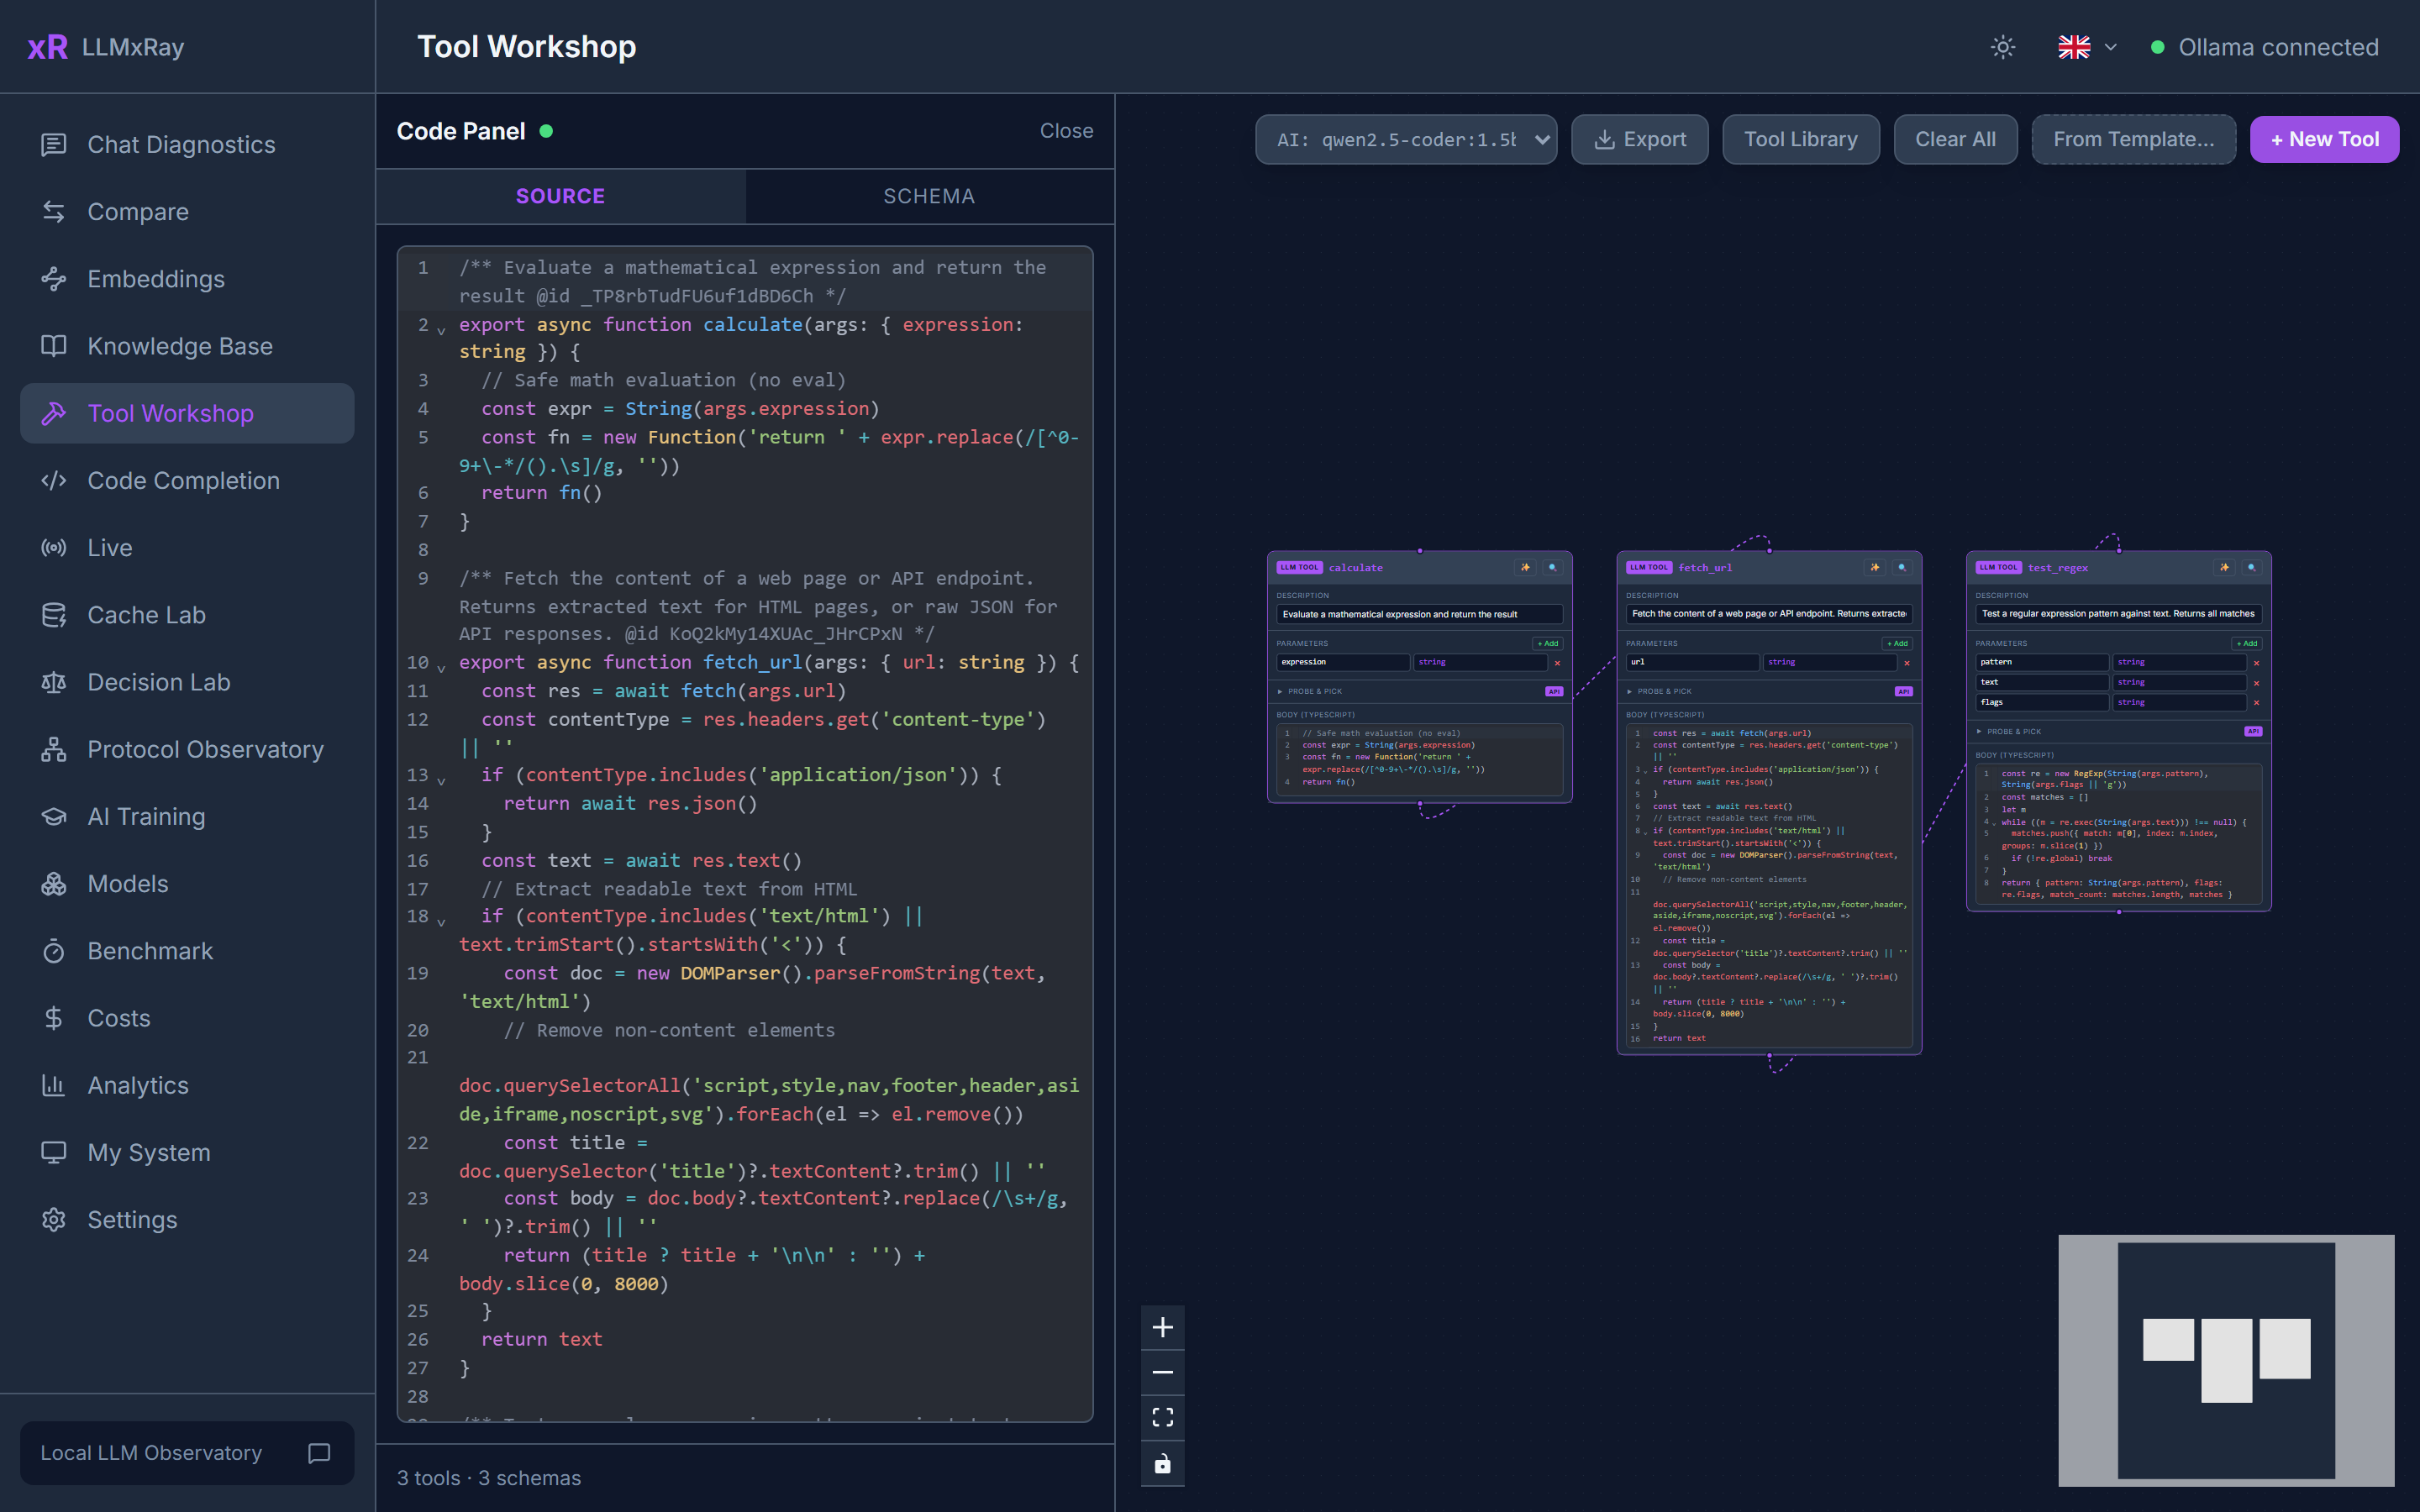
Tool Workshop
A node canvas for building tool definitions, with the TypeScript kept in sync both ways: edit the nodes or edit the code. Probe an API, generate the schema, and test the tool with a live call.
Screenshot
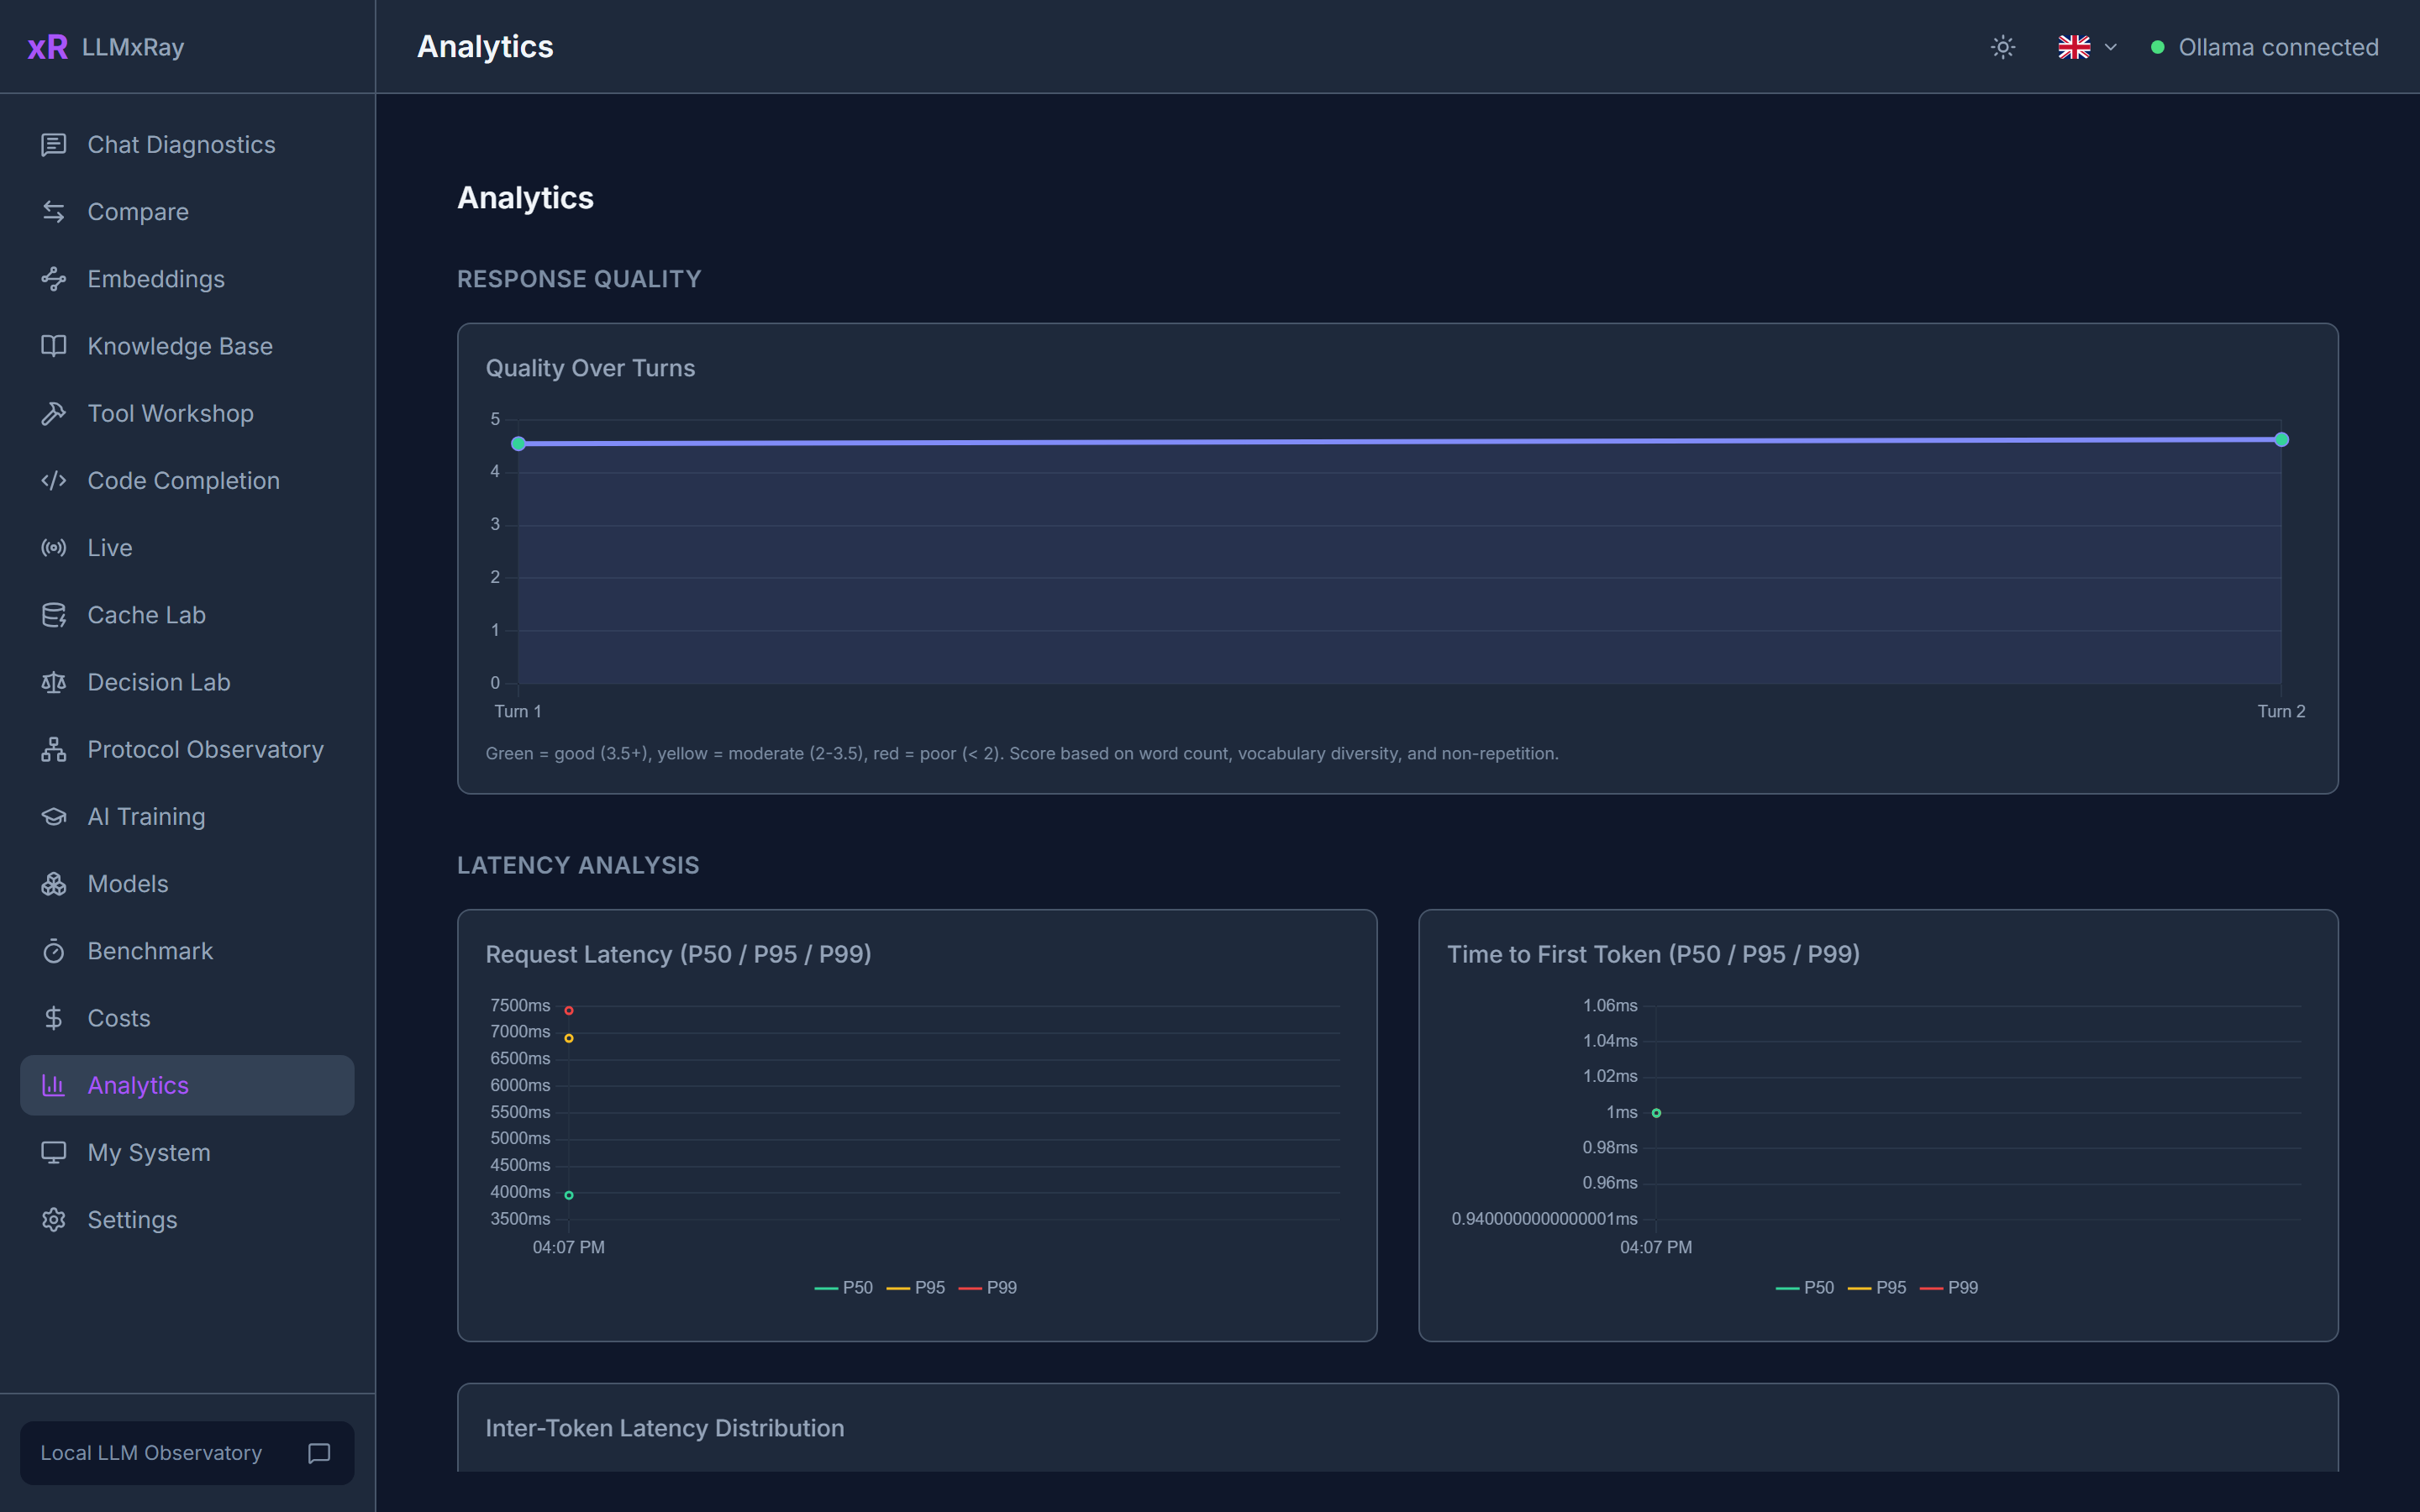
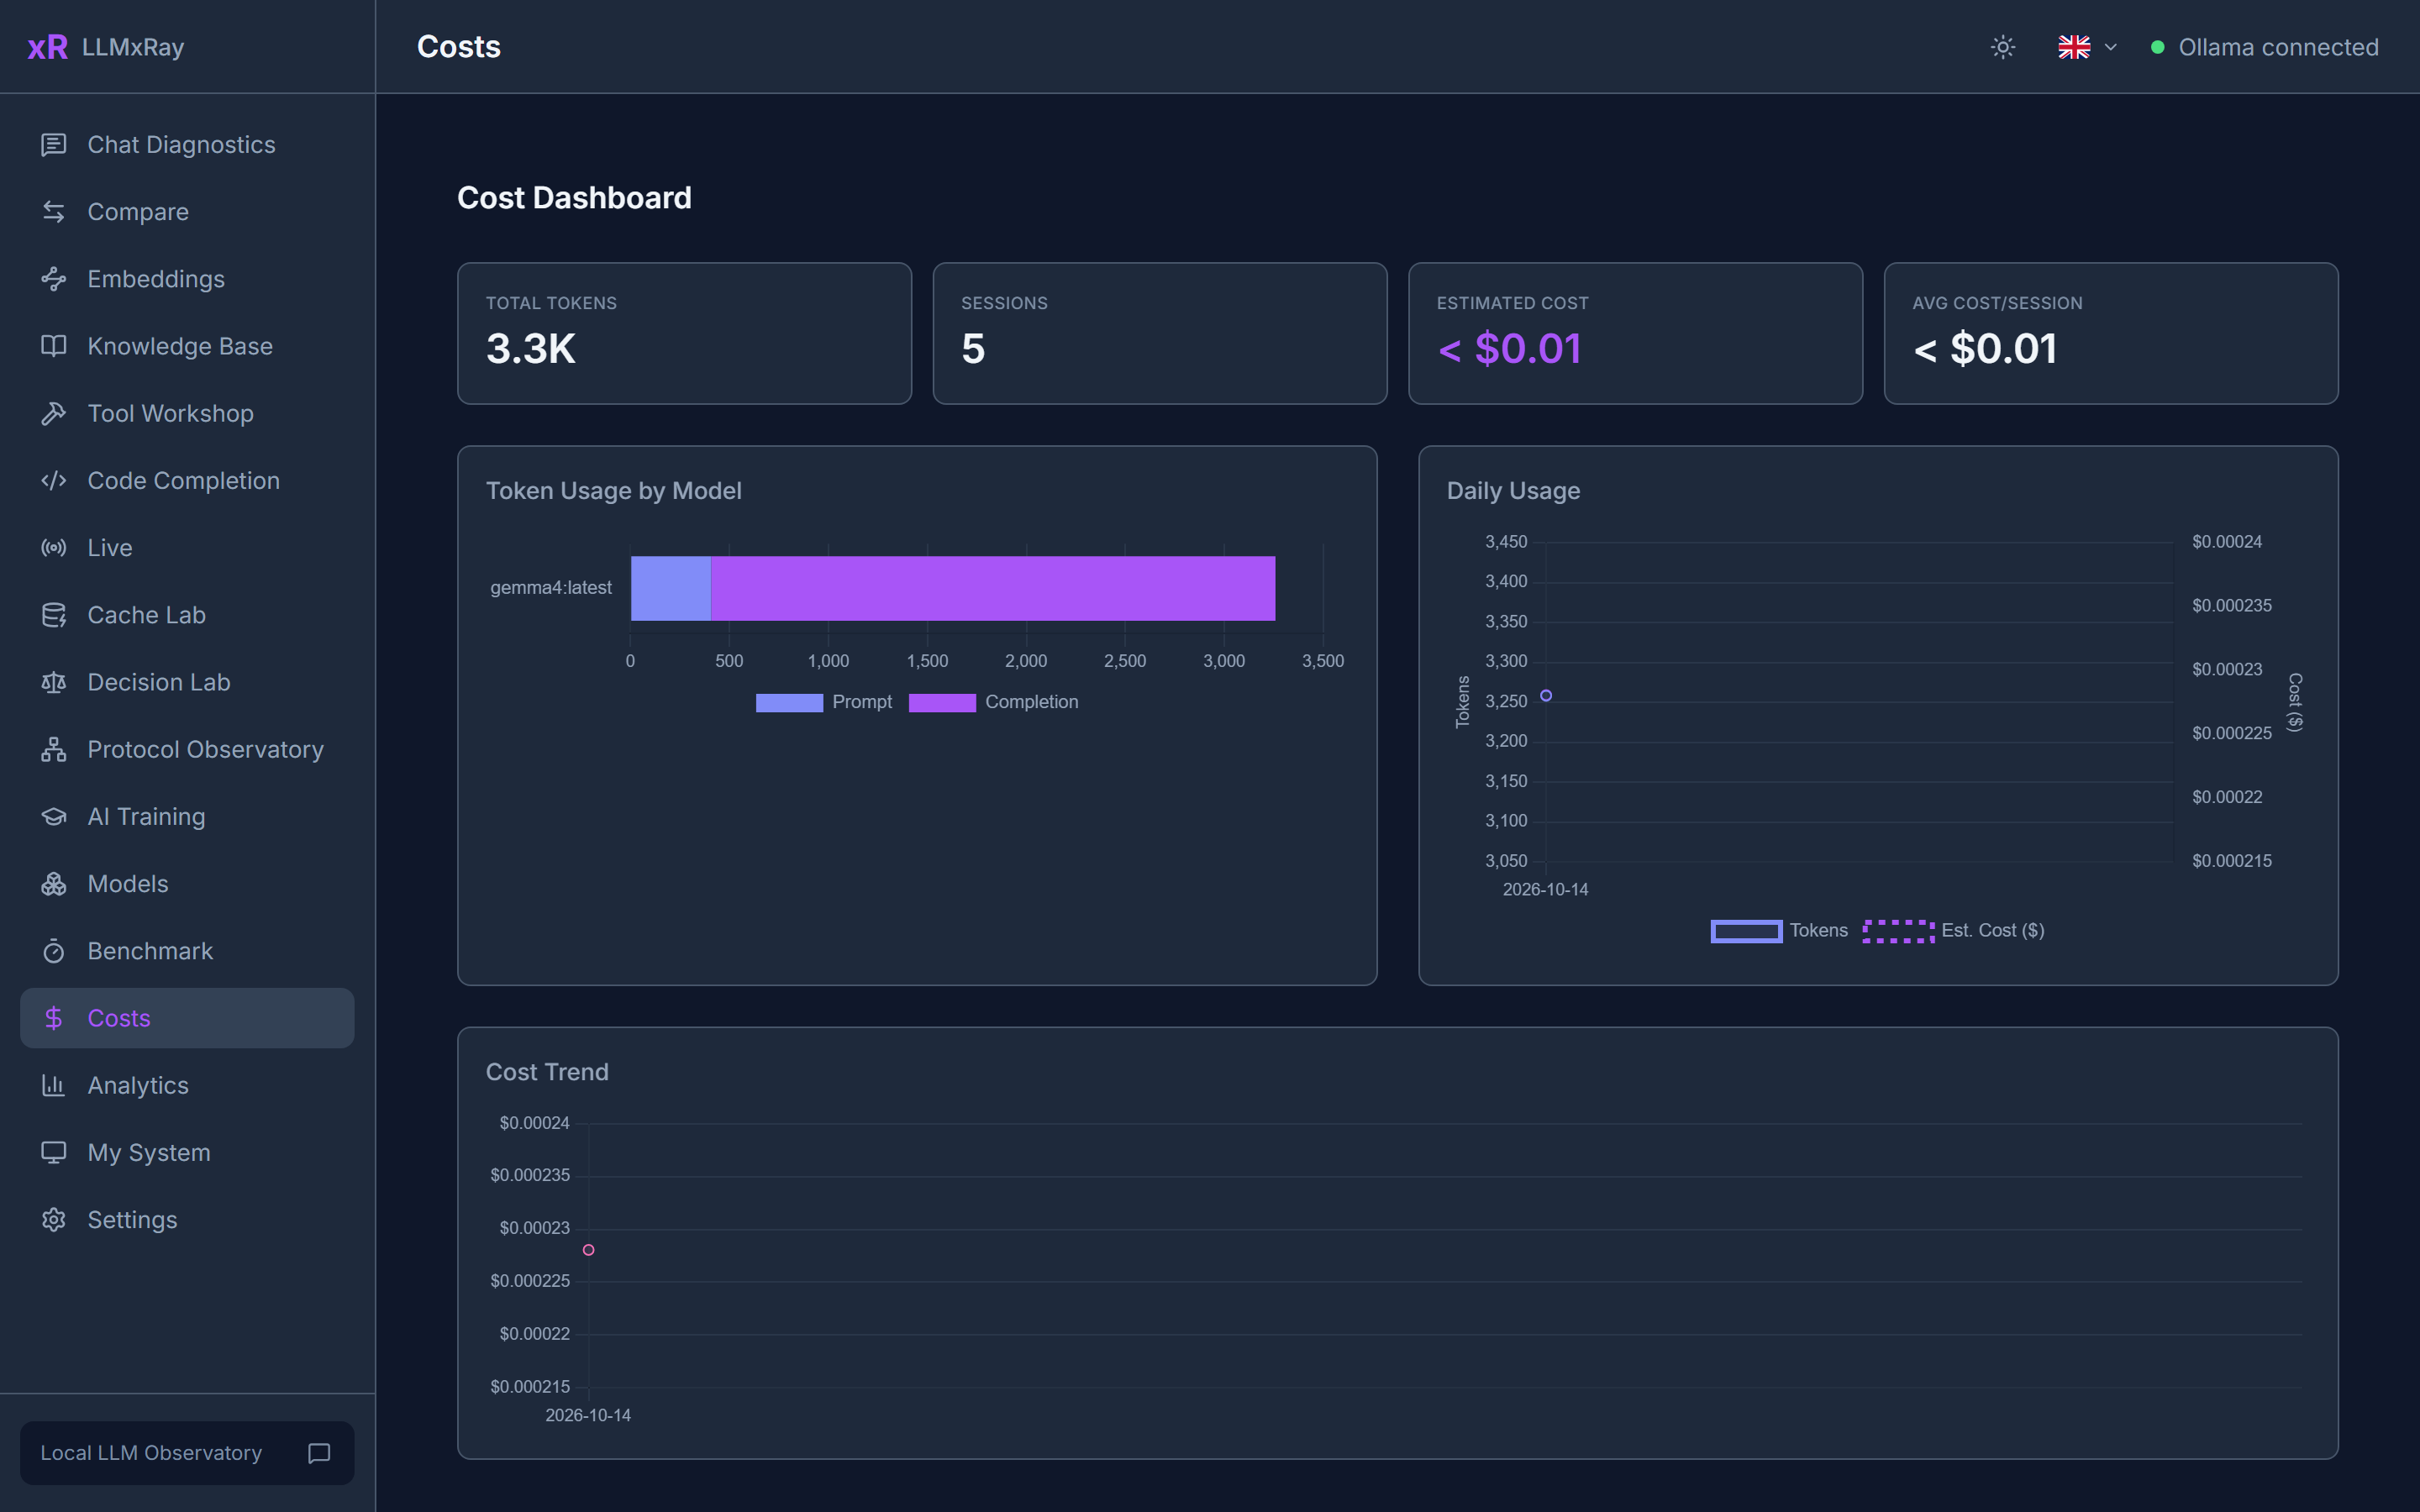
Analytics and Costs
Latency percentiles (P50 / P95 / P99) for requests and first tokens, quality over turns, errors by model, a usage heatmap, and temperature against tokens per second. The cost page prices your local usage at cloud rates, so you see what running locally saves.
Screenshot
|
|
|
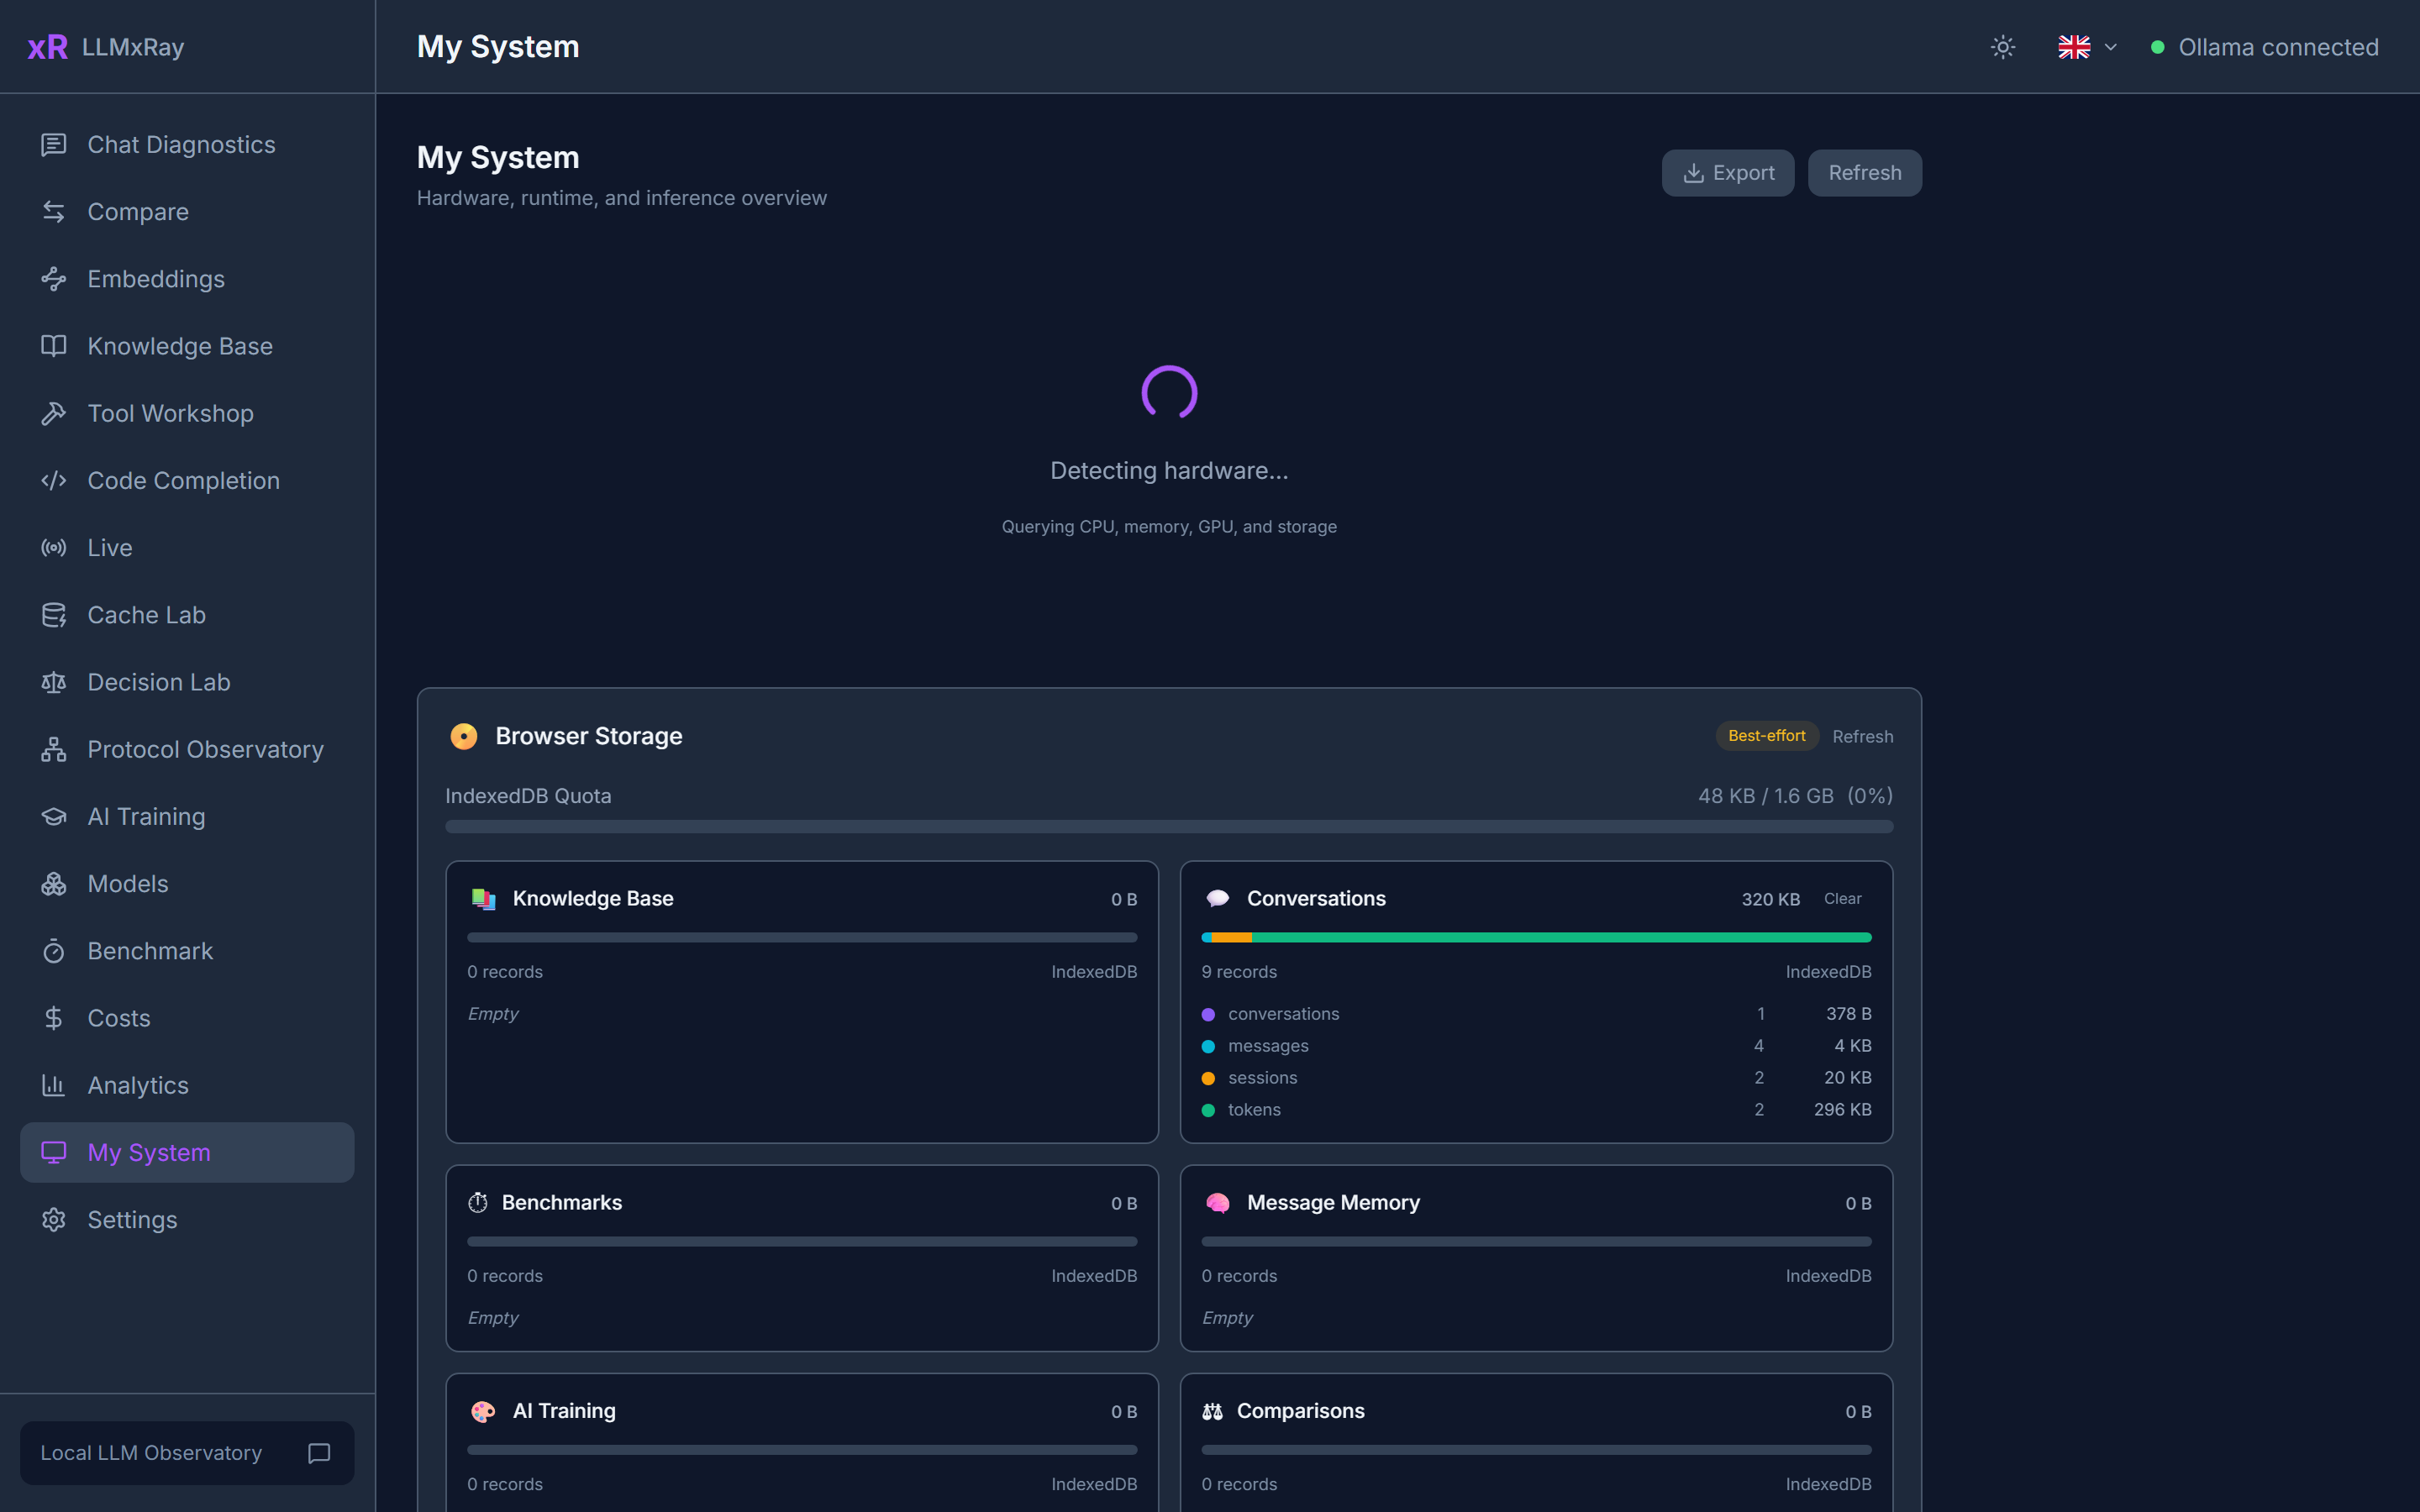
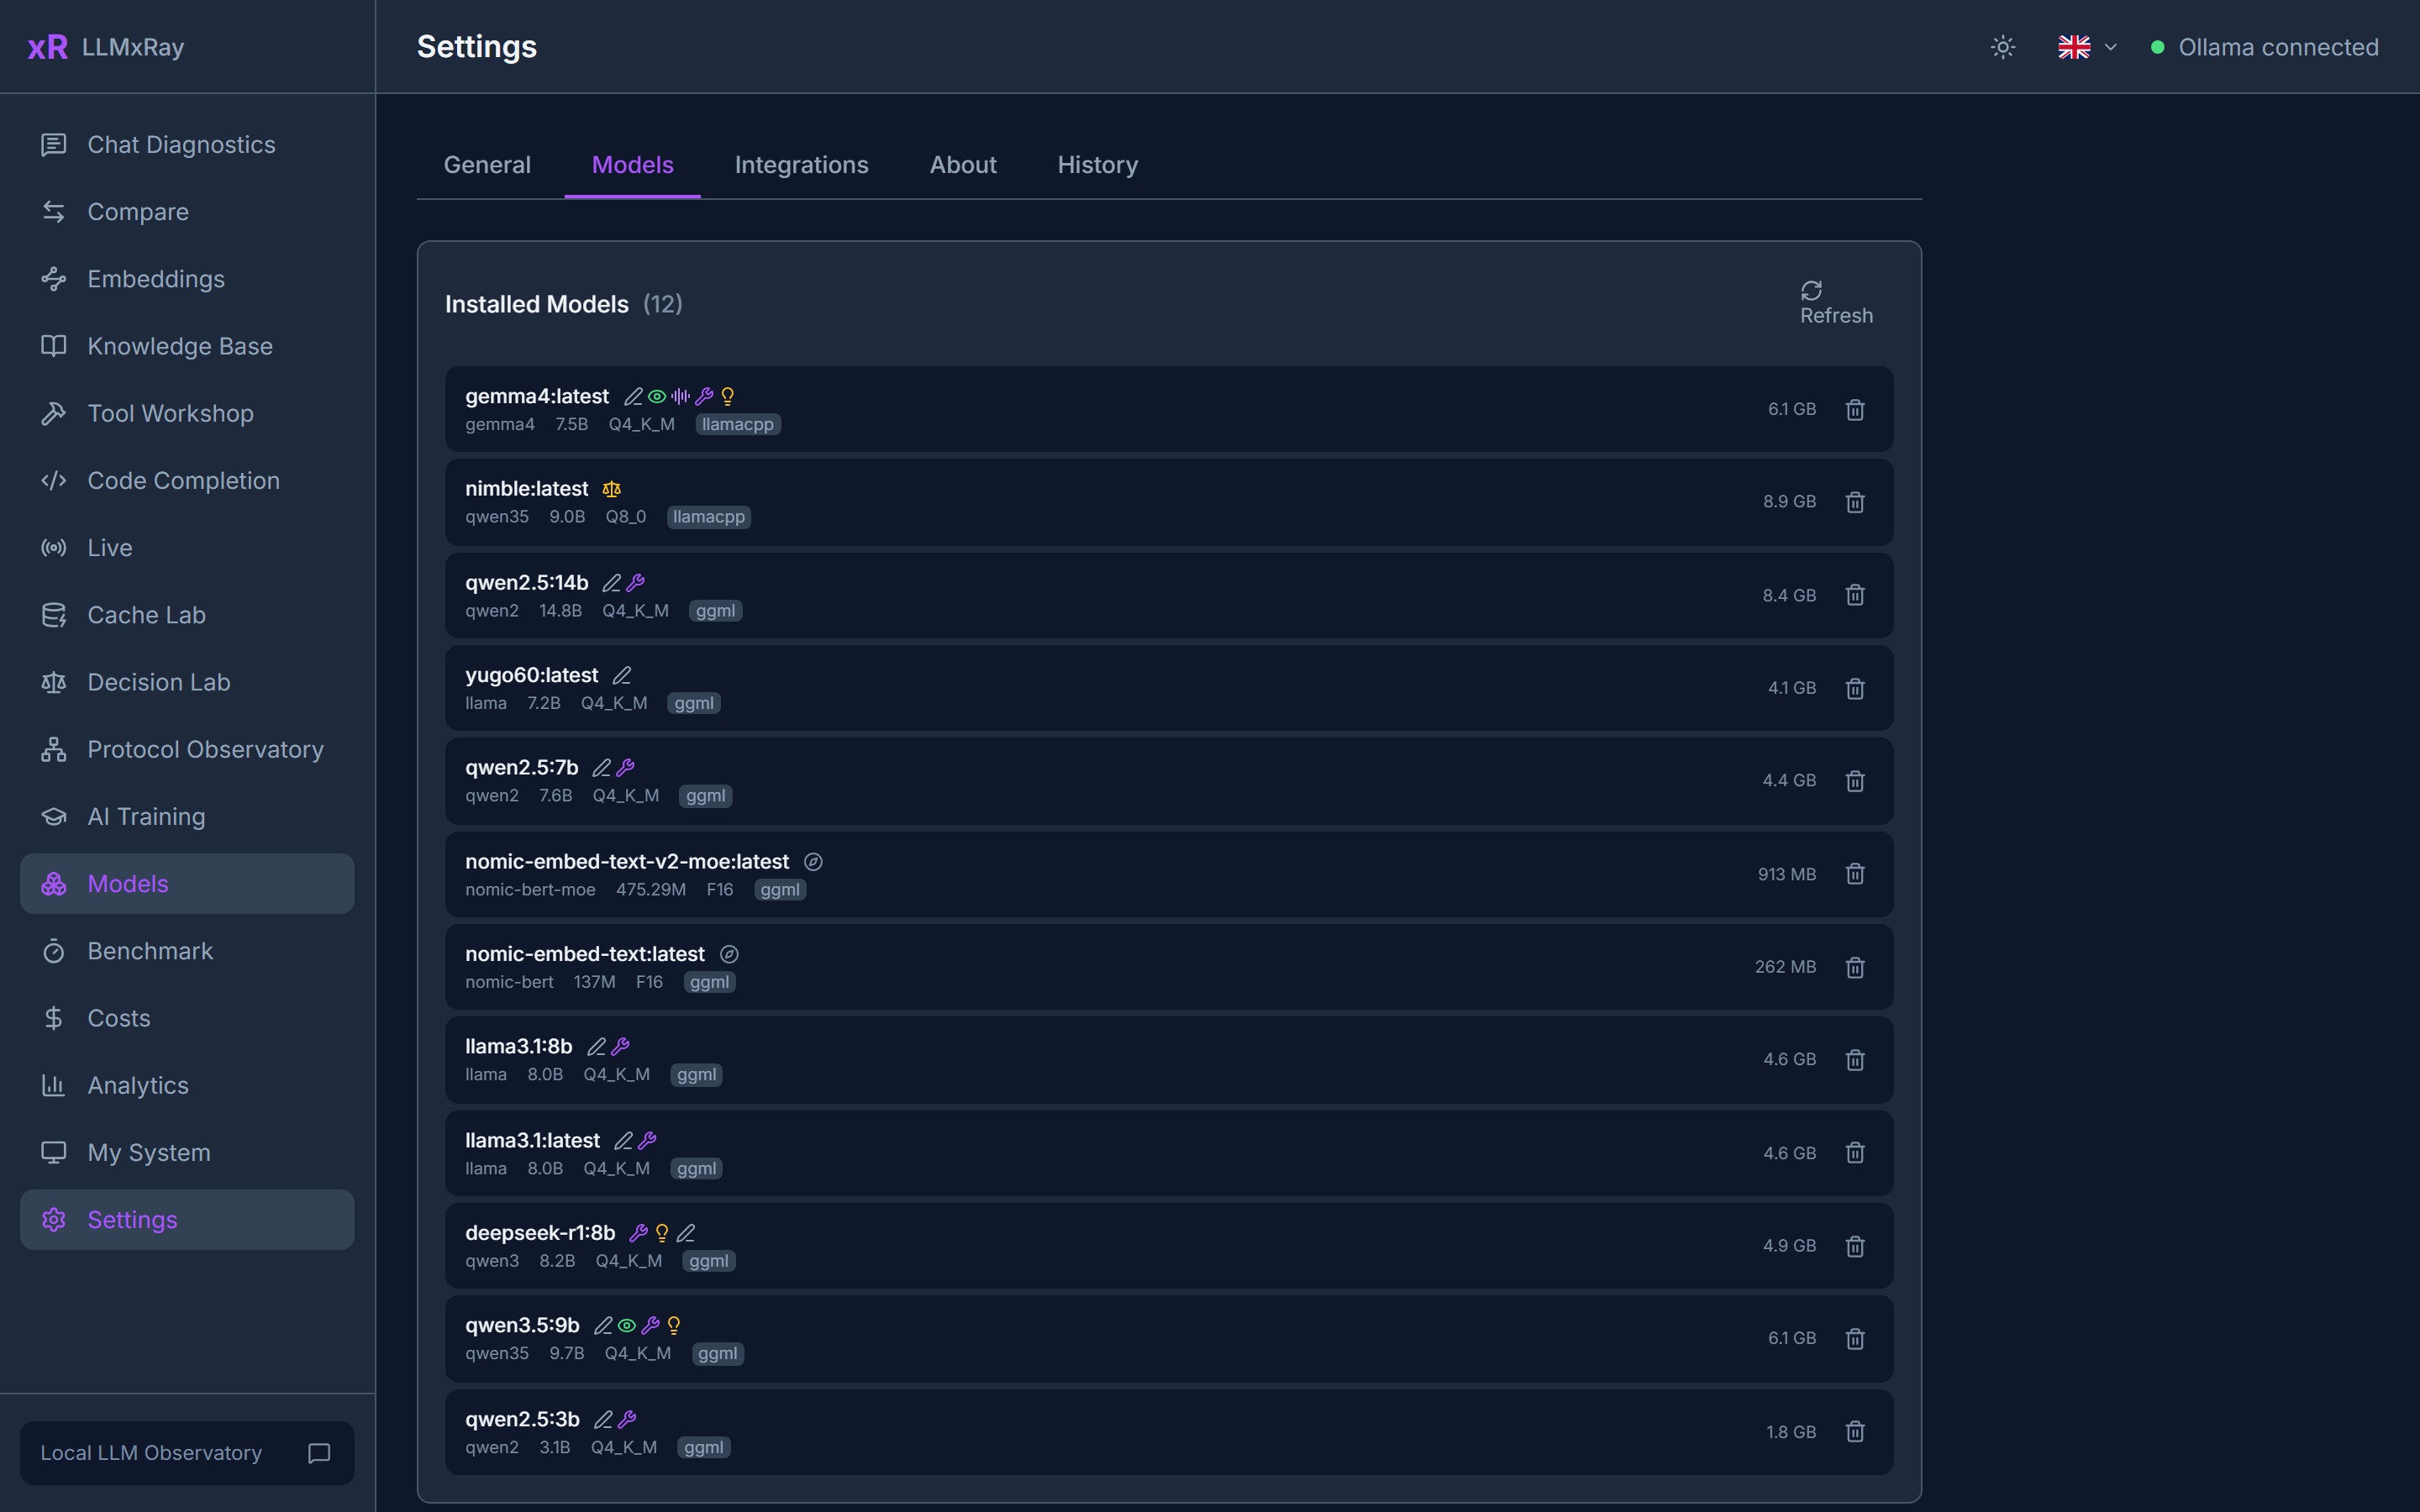
My System and Models
Hardware, runtime and inference overview on one page: CPU, memory, GPU, which models are loaded and where. The Models tab lists every installed model with its parameters, template and runner, and pulls new ones from the catalog.
Screenshot
|
|
|
More
- AI Training Pipeline. Curate pairs from your conversations, tag and review them, export JSONL for fine-tuning.
- Local history database. Every chat, comparison and benchmark is archived in IndexedDB with filters, trends, exports and retention rules.
- Educators Kit. Nine lesson modules on the docs site, each built around an LLMxRay page.
- Five languages. English, French, Serbian (Latin and Cyrillic), Chinese and Arabic, with RTL layout. Scaffolds ready for Hebrew and Japanese.
Who is this for
| You are... | LLMxRay helps you... |
|---|---|
| Developer | Debug prompts, profile latency, compare models, inspect tool calls, see what your editor sends |
| Researcher | Run controlled experiments with the same settings across models and temperatures |
| Student / Educator | Watch model behaviour instead of reading about it, with the nine-module Educators Kit |
| AI team lead | Give every developer the same local setup, and collect the benchmark results and training pairs they export |
Install
npx (recommended)
npx llmxray
npx llmxray --port 3000
npx llmxray --ollama-url http://192.168.1.50:11434
npx llmxray --observe-port 11436     # the Live port, 11435 by default
Docker
docker run -p 5174:5174 -p 11435:11435 djovaneli/llmxray
docker run -p 5174:5174 -p 11435:11435 -e OLLAMA_URL=http://host.docker.internal:11434 djovaneli/llmxray
From source
git clone https://github.com/LogneBudo/llmxray.git
cd llmxray
npm install
npm run dev     # http://localhost:5173
Ollama compatibility
Tested against Ollama 0.40.x (verified on 0.40.6, October 2026). Works with 0.20 and newer; older versions chat but lack think and JSON-schema format. Recommended: 0.33.3 or newer, which reports prompt-cache reuse, so prefill speed is measured over the tokens actually evaluated.
| Endpoint | Used for |
|---|---|
/api/chat | Streaming chat (NDJSON, with tools, think effort levels, format schema) |
/api/generate | Generation and Fill-in-the-Middle via suffix |
/api/tags, /api/show | Model list, capabilities, context length, parameters, template |
/api/embed | Vector embeddings for the Knowledge Base, with optional dimensions truncation |
/api/pull, /api/delete, /api/ps, /api/version | Model management and status |
/v1/chat/completions | OpenAI-compatible path, used by Surgical Benchmark for real logprobs |
/v1/messages | Anthropic-compatible path, used by Protocol Observatory |
/v1/systemone | Decision models, used by Decision Lab |
Under the hood
Vue 3.5, TypeScript 6 (strict), Vite 8, Tailwind CSS 4, Pinia stores per concern, Chart.js and D3 for charts, Vue Flow for the tool canvas, CodeMirror 6 for code. The app keeps its own data (chats, comparisons, benchmarks, the knowledge base) in the browser's IndexedDB; the Live log's turn records live in ~/.llmxray on the machine that runs LLMxRay. The backend is Ollama, local.
Streaming reads Ollama's NDJSON through fetch() and a ReadableStream, and tokens update the UI through Pinia. Chat and Compare colour tokens by the real logprobs Ollama returns; without them a token is left uncoloured, and the token view names timing as pace, never as confidence. Benchmarks use real logprobs too. Hardware detection is a small Vite plugin that asks the OS directly. The Live port is a transparent proxy: it forwards every request to Ollama untouched, translates nothing (Ollama itself serves the OpenAI- and Anthropic-compatible routes), and records counts and timings, kept for 30 days.
| Command | What it does |
|---|---|
npm run dev | Dev server (port 5173) |
npm run build | Type-check and production build |
npm run test | Unit tests (Vitest) |
npm run test:e2e | End-to-end (Playwright) |
Contributing
Contributions welcome. See CONTRIBUTING.md for setup and guidelines. Community translations are especially welcome: scaffold files are ready for Hebrew and Japanese.
License
Trademark
LLMxRay is a trademark of Ivan Stankovic (LogneBudo). See TRADEMARK.md.
If LLMxRay helps you understand your AI better, consider giving it a star.
It helps others discover the project.

Comments
New to MCP?
From what the protocol is to installing your first server, these answers cover most first questions.
An open protocol that defines how AI applications connect to external tools and data in a uniform way. Clients talk to the model; MCP servers provide tools, resources and prompt templates. They exchange standard messages, so one server can be reused by many clients.