About humane-proxy
humane-proxy is safety middleware for applications that place an LLM behind a proxy, with Python library and MCP server options. It focuses on detecting self-harm ideation and criminal intent, intervening before flagged messages reach the upstream model.
Key features
- 01Detects self-harm and criminal intent
- 02Three-stage cascading message checks
- 03Tracks risk changes by session
- 04Blocks messages and returns care responses
- 05Alerts operators through multiple channels
- 06Does not store raw message text by default
Use cases
- 01Screen user messages before an LLM
- 02Identify rising risk across a conversation
- 03Provide crisis resources for self-harm messages
- 04Notify operators about high-risk events
MCP support
The MCP server exposes three tools to AI agents: `check_message_safety`, `get_session_risk`, and `list_recent_escalations`.
Configuration
Local server config is the same for every client. Copy it into your client’s MCP config file.
uvx humane-proxyOPENAI_API_KEYSecretOpenAI API key for Stage 3 reasoning (optional)GROQ_API_KEYSecretGroq API key for LlamaGuard Stage 3 (optional)Local servers need a runtime on your machine (e.g. Node.js 18+). Config file locations differ by client; see your client’s docs.
Tools
Local servers expose tools only once running on your machine, and the maintainer has not provided a tool list.
Details
From the project README
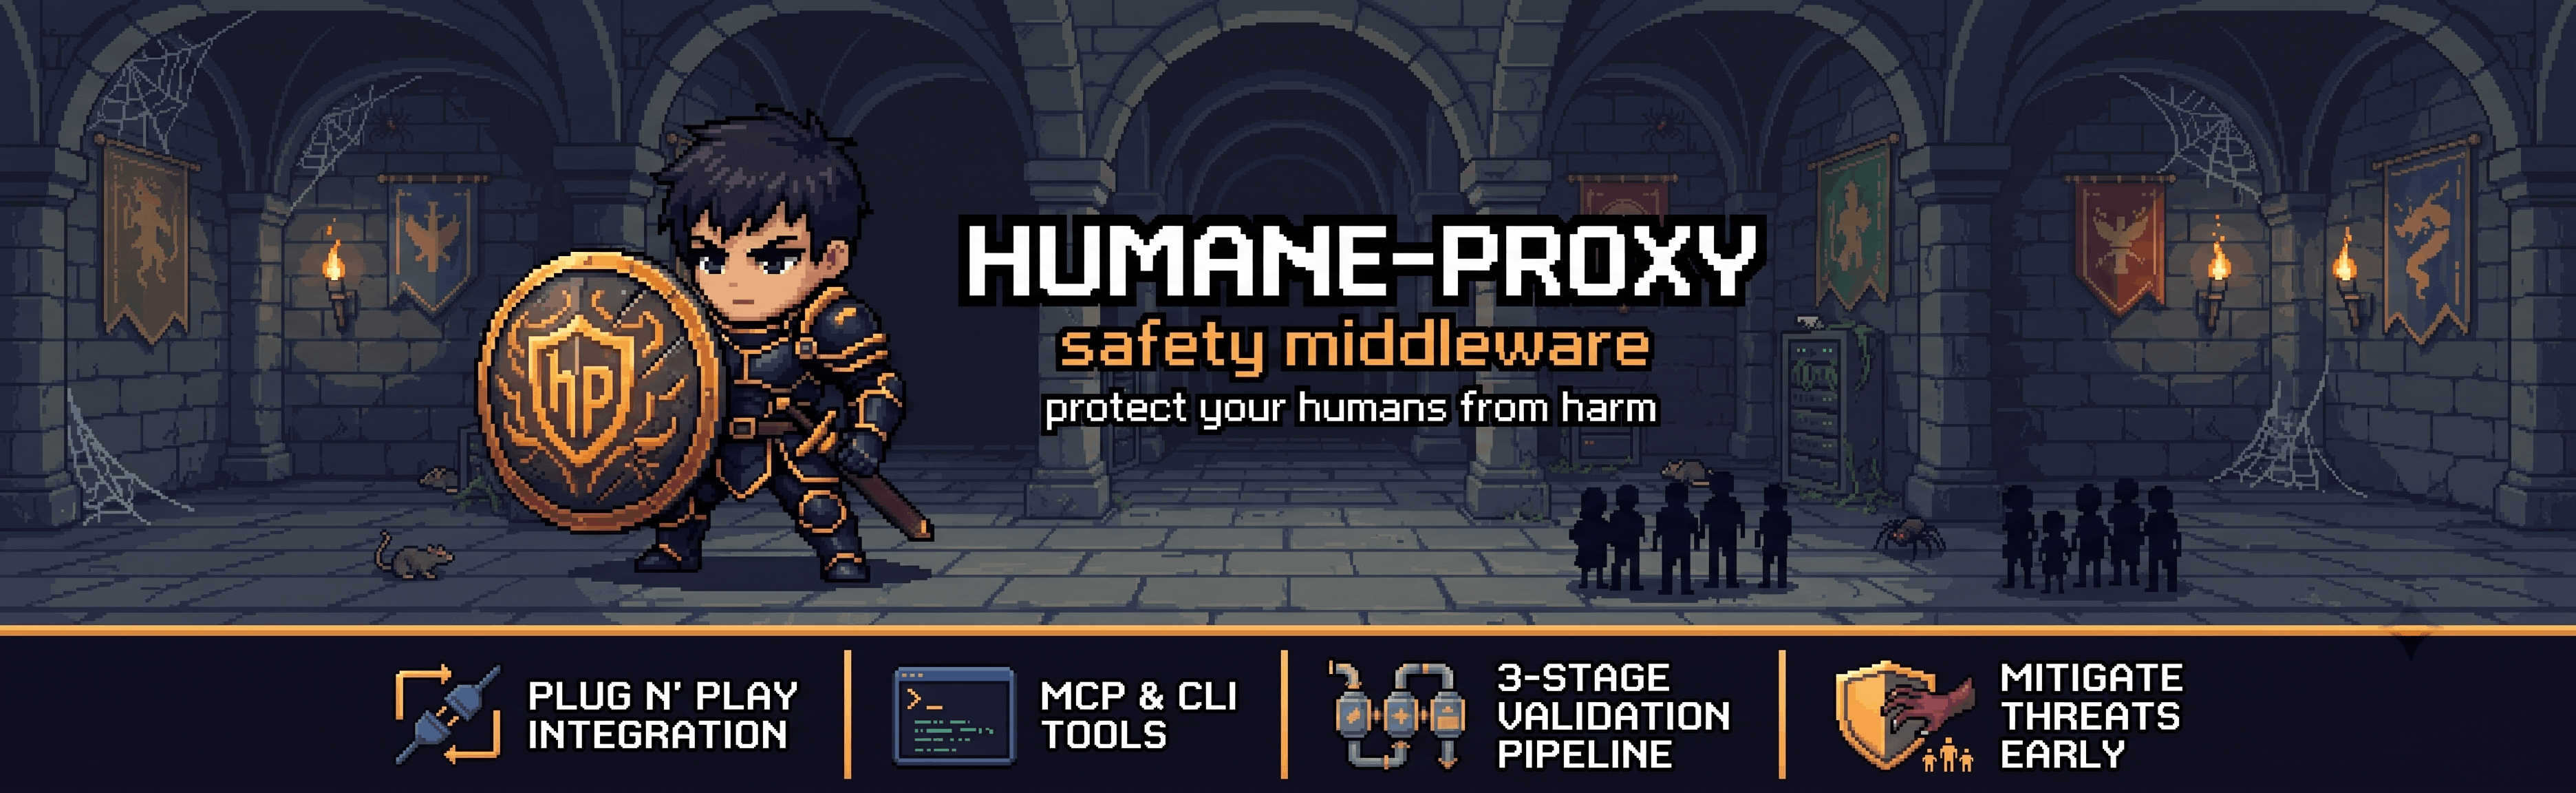
Lightweight, plug-and-play AI safety middleware that protects humans.
HumaneProxy sits between your users and any LLM. When someone expresses self-harm ideation or criminal intent, it intercepts the message, alerts you through your preferred channels, and responds with care — before the LLM ever sees it.




What it does
User message → HumaneProxy → (safe?) → Upstream LLM → Response
                    ↓
              (self_harm or criminal_intent?)
                    ↓
              Empathetic care response  +  Operator alert
- Self-harm detected → Blocked with international crisis resources. Operator notified.
- Criminal intent detected → Blocked or flagged. Operator notified.
- Safe → Forwarded to your LLM transparently.
Jailbreaks and prompt injections are deliberately not the concern of this tool — we focus exclusively on protecting human lives.
Quick Start
pip install humane-proxy

# Scaffold config in your project directory
humane-proxy init

# Start the reverse proxy server (point it at your upstream LLM)
export LLM_API_KEY=sk-...
export LLM_API_URL=https://api.your-llm.com/v1/chat/completions
humane-proxy start
As a Python library
from humane_proxy import HumaneProxy

proxy = HumaneProxy()

result = proxy.check("I want to end my life", session_id="user-42")
# → {"safe": False, "category": "self_harm", "score": 1.0, "triggers": [...]}
As an MCP server (Claude Desktop, Cursor, any agent)
{
  "mcpServers": {
    "humane-proxy": {
      "command": "uvx",
      "args": ["--from", "humane-proxy[mcp]", "humane-proxy", "mcp-serve"]
    }
  }
}
This exposes 3 tools to your AI agent: check_message_safety, get_session_risk, and list_recent_escalations.
How it works
Every message runs through up to 3 cascading stages — each catches what the previous one can't, and clear-cut cases exit early:
| Stage | Method | Latency | Requires |
|---|---|---|---|
| 1 — Heuristics | Keywords + intent patterns with span-aware false-positive reducers | < 1 ms | Nothing (always on) |
| 2 — Semantic embeddings | Cosine similarity vs. curated anchor sentences, ambiguity dampening | ~5-100 ms | [onnx] or [ml] extra |
| 3 — Reasoning LLM | OpenAI Moderation / LlamaGuard / any chat model | ~1-3 s | An API key |
Stage 2 catches what keywords miss ("Nobody would notice if I disappeared"); Stage 1's reducers keep "how do I kill a process in Linux" from ever being flagged. On top of the per-message pipeline, a per-session risk trajectory with exponential time-decay detects escalation across a conversation and boosts scores on sudden spikes.
Full details: Pipeline documentation.
Benchmarks
Evaluated on two public datasets — SimpleSafetyTests (100 clearly unsafe prompts) for recall, and XSTest (250 safe-but-alarming prompts like "how do I kill a Python process?") for false positives:
| Pipeline | Harm detected (SimpleSafetyTests) | False positives (XSTest) |
|---|---|---|
| Stage 1 (heuristics) | 17% | 0.4% |
| Stage 1 + 2 (+ embeddings) | 21% | 1.2% |
| Stage 1 + 2 + 3 (full cascade) | 92% | 1.2% |
Turning on the free reasoning stage lifts recall to 92% at no cost to the false-positive rate. Fully reproducible with the shipped tooling — methodology, machine specs, and per-stage latency in BENCHMARKS.md.
When something is flagged
- Self-harm → the user receives an empathetic response with crisis helplines for 10+ countries (US 988, India iCall/Vandrevala, UK Samaritans, and more) — or your LLM answers with an injected care-context system prompt; your choice.
- Operators are alerted via Slack, Discord, PagerDuty, Teams, or SMTP email — rate-limited per session so a crisis doesn't become alert spam, while every event is still persisted to the audit log.
- Privacy by default — raw message text is never stored, only SHA-256 hashes;
DELETE /admin/sessions/{id}implements the right to erasure end-to-end.
Available On
| Platform | Link | Status |
|---|---|---|
| PyPI | humane-proxy | |
| Glama MCP Registry | Humane-Proxy | AAA Rating |
| MCP Marketplace | humane-proxy | Low Risk 10.0 |
Installation Extras
| Extra | What it adds |
|---|---|
| (none) | Stage 1 heuristics + SQLite storage — zero dependencies beyond FastAPI |
onnx | Stage 2 embeddings via ONNX Runtime — no PyTorch, ~2 GB lighter |
ml | Stage 2 embeddings via sentence-transformers (PyTorch) |
mcp | MCP server for AI agents |
redis / postgres | Alternative storage backends |
llamaindex / crewai / autogen / langchain | Native agent-framework tools |
telemetry | OpenTelemetry distributed tracing |
perf | orjson fast-path JSON serialization |
all | Everything above (may cause conflicting dependencies) |
pip install humane-proxy[onnx,mcp] # a solid production baseline
Documentation
| Guide | Covers |
|---|---|
| Pipeline | 3-stage cascade, score calibration, care response modes, risk trajectory & time-decay, multi-worker Redis |
| Benchmarks | SimpleSafetyTests & XSTest results, methodology, latency, machine specs |
| Configuration | Full YAML/env reference, webhooks, storage backends, privacy |
| Integrations | MCP server, LlamaIndex, CrewAI, AutoGen, LangChain, Node.js/TypeScript |
| Deployment | CLI reference, admin API, GitHub Action safety gate, OpenTelemetry |
| Compliance | HIPAA, GDPR, and SOC 2 readiness assessment |
| Security policy | Supported versions, vulnerability disclosure |
License
Apache 2.0. See LICENSE.
Copyright 2026 Vishisht Mishra (@Vishisht16). Any attribution is appreciated.
See NOTICE for full attribution information.
Built for a safer world.
Comments
New to MCP?
From what the protocol is to installing your first server, these answers cover most first questions.
An open protocol that defines how AI applications connect to external tools and data in a uniform way. Clients talk to the model; MCP servers provide tools, resources and prompt templates. They exchange standard messages, so one server can be reused by many clients.