Skills
97,501 packaged capabilities and playbooks for agents. Install any of them with one command.

Testing & quality

Reviews DAST tool configurations against OWASP Top 10:2021 and OWASP Testing Guide v4.2. Auto-invoked when reviewing OWASP ZAP configurations, DAST CI/CD integration, scan policies, or authenticated scanning setups. Produces a DAST maturity assessment covering scan policy configuration, active vs passive scanning, API scanning, authentication handling, and results deduplication.


Systematically evaluates existing designs against cognitive science principles using repeatable checklists, scoring rubrics, and severity-classified fix recommendations. Use when conducting design reviews or critiques, evaluating designs for cognitive alignment, performing quality assurance before launch, diagnosing usability issues, or choosing between design alternatives with objective criteria.


Disciplined diagnosis loop for hard bugs and performance regressions. Reproduce → minimise → hypothesise → instrument → fix → regression-test. Use when user says "diagnose this" / "debug this", reports a bug, says something is broken/throwing/failing, or describes a performance regression.


Lint a Figma node tree for WCAG 2.2 accessibility AND design-system quality — contrast, target size, focus indicators, color-only signaling, hardcoded colors, missing text styles, detached components, and more. Use when the user wants a design-side audit BEFORE handoff: triggers 'lint this frame', 'check accessibility', 'WCAG audit', 'is my design accessible', 'find contrast issues', 'check color contrast', 'find hardcoded colors', 'are my components using tokens', 'design QA', 'a11y check on this page', 'audit my design for issues'. Walks the tree from a node (or the whole page) and returns findings with severity (critical/warning/info) and WCAG level (A/AA/AAA/best-practice). The native Figma MCP has NO design-side linting — this is unique to this collection. For the deep per-component a11y scorecard use audit-accessibility-figma; for CODE-side (HTML) checks use scan-code-accessibility-figma.

Guide maintainable, resilient, test-double-friendly code: clear names, decomposition, safe defaults, idempotency, bounded retries, observability, and quality gates. Use for production code, jobs, queues, webhooks, APIs, refactors, reviews, plans, CI, config, or dependency-heavy code and tests. Skip disposable work.

Run MassGen experiments and analyze logs using automation mode, logfire tracing, and SQL queries. Use this skill for performance analysis, debugging agent behavior, evaluating coordination patterns, and improving the logging structure, or whenever an ANALYSIS_REPORT.md is needed in a log directory.
Fix the errors reported by MegaLinter. Use after megalinter-check found errors, or when the user pastes MegaLinter/CI lint errors and wants them fixed. Applies safe fixes automatically (auto-fix linters first, then guided manual fixes using per-linter fix guides), asks the user when fixing is ambiguous, and can disable rules or linters with user confirmation. Never pushes to the default branch.


General-purpose generation template for OpenHarmony XTS test cases. Supports test case generation for various subsystems, API definition parsing, test coverage analysis, and code standard checks. Trigger keywords: XTS, test generation, case generation, test case.

Surface the Opik traces worth a developer's attention, ranked by signal — Diagnostics issues first, then errors, failed tool calls, latency, regressions, and low online-eval scores. With the Opik MCP connected it lists the project's agent_insights_issue entities, offers to turn Diagnostics on when the project has it switched off, then fills the gaps with list (filters, sort, a time window); without the MCP it reads the same via the SDK (agent_insights and search_traces), so it works with no MCP. Returns a ranked shortlist, each item ready to hand to the explain skill. Use for "what is broken in production", "which traces need attention", "find failing or slow traces", "which tool calls are failing", "triage my agent". Not for offline experiment results (use evaluate or compare) and not for root-causing one trace (use explain).
Root-cause a specific Opik trace, or a pattern across traces, and return a grounded explanation. Uses the hosted Opik MCP when it is connected, and falls back to SDK scripting otherwise. Returns the root cause, the evidence spans as clickable Opik UI links, and one suggested next step. Use for "why did this trace fail", "explain this trace", "debug this trace", "why is my agent slow or wrong". Not for adding tracing to an app (use the instrument skill) or for changing code.





Map test cases — manual (markdown) and automated e2e (Playwright, Cypress, WebdriverIO, CodeceptJS, Puppeteer, Appium) — to source code files and produce a `coverage.tests.yml` mapping consumed by `@testomatio/reporter --filter "coverage:..."`. Use this skill when the user wants to run only the tests affected by a code change, generate a coverage file (manual, e2e, or both), build a traceability matrix between tests and source code, or set up change-aware regression.

Injects controlled faults (network partition, latency, process kill, disk pressure) into distributed systems and validates recovery behavior. Use when testing circuit breakers, failover paths, retry logic, or building confidence in system resilience through chaos engineering.
Orchestrates test suite execution with parallel sharding, intelligent retry, and real-time reporting across Jest, Vitest, and Playwright. Use when running test suites, optimizing execution time, handling flaky tests, configuring CI test pipelines, or analyzing test run results.

Evaluate how well a codebase supports autonomous AI development. Analyzes repositories across eight technical pillars (Style & Validation, Build System, Testing, Documentation, Dev Environment, Debugging & Observability, Security, Task Discovery) and five maturity levels. Use when users request `/readiness-report` or want to assess agent readiness, codebase maturity, or identify gaps preventing effective AI-assisted development.

RGAA 4.1.2 compliance audit tool for websites and React/HTML components. Use this skill to audit the RGAA compliance of a site or component: when the user asks for an accessibility audit, an RGAA compliance report, when they want to know whether their code/site complies with RGAA, when they mention "audit RGAA", "conformité RGAA", "non-conformités", "déclaration d'accessibilité", or when they share HTML/React code for a posteriori checking.


Use when a Roblox experience is slow, laggy, stuttering, crashing or out of memory, or before shipping or updating one: my game lags on mobile, low FPS, frame spikes, server lag or low heartbeat, physics lag, network lag or high KB/s, memory leaks or memory that keeps growing, crashes on phones, long join or load times, too many parts, instances, draw calls or triangles, MicroProfiler, Script Profiler, Luau heap, Developer Console memory, Scene Analysis, StreamingEnabled tuning, performance budgets, and publishing, releasing an update, restarting servers or rolling back a version.
Use when setting up or repairing a Roblox team project outside Studio: Rojo or Script Sync, Wally packages, Rokit pins, luau-lsp type checking, Selene, StyLua, unit tests in Lune or the engine, GitHub Actions CI on pull requests, Open Cloud place publishing, Luau Execution or API key scopes, merging builders' Team Create map with code from files, Studio plugins, or proving a pipeline works. Also when users say "set up Rojo", "CI for my Roblox game", "run tests in CI", "publish from GitHub", "Script Sync stopped syncing", "Rojo deleted my parts", "wally packages not found", "luau-lsp can't find ReplicatedStorage", "selene errors on types", "the release wiped the map" or "my LocalScript doesn't run".

Provides comprehensive guidance for Selenium WebDriver including browser automation, element location, waits, and test frameworks. Use when the user asks about Selenium, needs to automate web browsers, write Selenium tests, or work with Selenium WebDriver.

Reads user-visible copy the way a United Nations editor would — language, wording, tone, grammar, hate speech, spelling, terminology, dates, numbers, claims and register — and reports what fails. Use when reviewing web pages, dashboards, blog posts, page titles, meta descriptions, copy baked into JavaScript by a coding agent, or the text of a PDF document. Checks HTML, Markdown, plain text, rendered JavaScript string literals, PDF text and Word or OpenDocument document text only; it is not a code-quality, accessibility, security or SEO linter (those run only as explicit opt-in audits) and it does not judge whether a claim is true.


ALWAYS use after design/implement for screenshot QA: capture, contrast, fix, document. Mandatory after handoff. Fast widths 375/768/1440; before flagship done use --preset done (375/430/768/1024/1440/1920). Auto-fix — never report-only unless user says audit-only. Edges must read on the plane.

Provides comprehensive guidance for Vitest testing framework including fast test execution, Vite integration, component testing, mocking, and configuration. Use when the user asks about Vitest, needs to write fast unit tests, test Vue/React components, or configure Vitest with Vite projects.
Health-check the wiki: scan all pages for broken wikilinks, orphaned pages, stale index entries, missing connections, em-dash violations, orphaned assets, and schema errors. Produces a dated lint report. Always use this skill when the user says /wiki-lint, mentions broken links, dead wikilinks, orphaned pages, 'what's broken in my wiki', 'are my links working', 'which pages have no connections', or asks for a wiki health check. Also use when the user notices a link that doesn't resolve, suspects the index is out of date, or asks whether the wiki is in good shape - even if they don't say 'lint'. Never auto-fixes anything; reports only. When in doubt whether a wiki health check is being requested, use this skill. Requires filesystem read access and write access to archive/.

Use when the user says 'analyze my wordpress site', 'what is running on my site', 'site dna', or 'what plugins are on my site'. Detects every page builder, audits active versus dead-weight plugins, maps content structure, finds orphaned shortcodes, and checks performance and security posture.

WordPress ACF and content modeling review. Use when reviewing Advanced Custom Fields usage, field group architecture, CPT and taxonomy design, options pages, repeaters, flexible content, block-bound field groups, meta storage patterns, or when user mentions "ACF", "field groups", "flexible content", "repeater", "custom post type design", "taxonomy design", "content model", "relationship fields", "ACF JSON", "options page", or "meta query performance". Detects schema drift, weak content modeling, brittle field naming, and performance issues in meta-heavy WordPress builds.
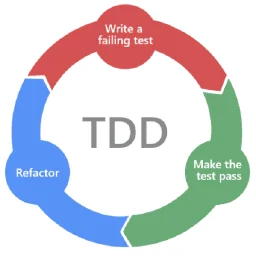
End-to-end ticket implementation with a multi-agent team using TDD. Retrieves JIRA ticket details and Figma designs, spawns a PO to write requirements, gets developer approval, then proposes a test plan for review. Once tests are approved, implements tests first (red), then production code to pass them (green). Use --no-jira to skip JIRA retrieval and use inline instructions instead. Use --headless for fully autonomous execution where a reviewer agent replaces human approval.
Run pre-flight submission checks for an App Store version using the `asc` CLI tool. Use this skill when: (1) Checking if a version is ready to submit to App Store review (2) Diagnosing why a version cannot be submitted (missing build, no pricing, wrong state) (3) Running a CI/CD gate before calling `asc versions submit` (4) User asks "is my version ready?", "check readiness", "why can't I submit?", "run pre-flight checks", "check submission requirements", or any submission-readiness task (5) Building an automated pipeline that conditionally submits based on readiness
Manage power and performance metrics and diagnostic logs using the `asc` CLI tool. Use this skill when: (1) Listing performance metrics for an app: "asc perf-metrics list --app-id <id>" (2) Listing performance metrics for a build: "asc perf-metrics list --build-id <id>" (3) Filtering metrics by type: "asc perf-metrics list --app-id <id> --metric-type LAUNCH" (4) Listing diagnostic signatures for a build: "asc diagnostics list --build-id <id>" (5) Filtering diagnostics: "asc diagnostics list --build-id <id> --diagnostic-type HANGS" (6) Viewing diagnostic logs: "asc diagnostic-logs list --signature-id <id>" Also trigger when the user mentions: performance metrics, launch time, hang rate, disk writes, memory usage, battery life, termination, animation hitches, diagnostic signatures, call stacks, power metrics, app performance monitoring, "why is my app slow", "check hangs", "check launch time"
Manage TestFlight beta groups and testers using the `asc` CLI tool. Use this skill when: (1) Listing beta groups for an app (`asc testflight groups list`) (2) Creating internal or external beta groups (`asc testflight groups create --internal`) (3) Listing testers in a group (`asc testflight testers list --group-id <id>`) (3) Adding a single tester by email (`asc testflight testers add`) (4) Removing a tester from a group (`asc testflight testers remove`) (5) Bulk-importing testers from a CSV file (`asc testflight testers import`) (6) Exporting testers to CSV for re-use (`asc testflight testers export`) (7) User says "add beta tester", "invite tester", "remove tester", "import testers", "export testers", "list beta groups", or any TestFlight tester management task

Configure ATC clean core and Cloud Readiness checks using the SAP Cloudification Repository, and map ATC findings to clean core levels (A, B, C, D). Use when users ask about ATC check variants for cloud readiness, clean core compliance, clean core levels, released/classic/internal/noAPI object classification, cloudification repository setup, objectReleaseInfo or objectClassifications JSON files, ATC exemptions, changelog for SAP objects, SAP Cloud ERP or SAP Cloud ERP Private API validation, or migrating custom code to ABAP Cloud. Triggers include "configure ATC cloud readiness", "set up clean core check", "cloudification repository URL", "released APIs check", "which level is this ATC finding", "ATC priority 1 clean core", "ATC exemption", "changelog for SAP objects", or "which JSON file for my S/4HANA version".


Reviews axum web framework code for routing patterns, extractor usage, middleware, state management, and error handling. Use when reviewing Rust code that uses axum, tower, or hyper for HTTP services. Covers axum 0.7+ patterns including State, Path, Query, Json extractors.

Use when the user asks "what can Cekura do", "what commands are available", "help me with Cekura", "what skills do I have", "show me Cekura features", "what's available", "how do I use Cekura", or needs guidance on which Cekura skill to use for their task. Also relevant as the entry point when a user has just installed cekura-skills for the first time.


Deterministic CI/CD interaction patterns with structured evidence output. Push-and-wait discipline (one pending run at a time), five-category failure triage (test-failure, lint-failure, build-failure, flaky-test, infra-failure) with classification-specific fix strategies, self-healing for lint/format/infra failures, flaky test detection, and CI_RESULT JSON evidence packets for every run. Use when pushing code to CI, triaging CI failures, waiting for pipeline results, classifying build errors, dealing with flaky tests, or producing CI evidence for quality gates. Triggers on: "CI failed", "push and wait for CI", "triage build failure", "flaky test", "CI pipeline", "build broke", "CI evidence". NOT for: individual test debugging (use debugging-protocol), code review (use code-review).
Use when reviewing Spring Boot 4 / Java 17+ code with concrete files or diffs — pull requests, modules, or pasted Java/Spring sources — for migration risks, architecture boundary leaks, JSpecify null-safety gaps, security flaws, performance regressions, or Spring Data pitfalls. Not for Kotlin-only code, non-Spring frameworks, or generic review advice without code context.

Tunes an existing Codacy Cloud repository's configuration directly on the cloud, without local analysis, by importing the current config, suggesting higher-signal tools and patterns, reanalyzing, and iteratively reducing noise across two tuning passes. Requires the repository to already be on Codacy with at least one finished analysis. Uses the Codacy Analysis CLI only for config-file operations and the Codacy Cloud CLI for everything else. Produces a machine-readable JSON summary of pattern, tool, category, and severity changes plus conflicts and recommended path ignores. Use when the user wants to configure or tune Codacy directly on the cloud, reduce noise on a repository already analyzed by Codacy, optimize cloud patterns and tools, or improve the signal of cloud issues without running local analysis.
Refactor code to reduce cyclomatic complexity so it stays readable, maintainable, and aligned with the long-term vision of the codebase, not just optimized for AI comprehension. Use whenever the user asks to refactor, simplify, clean up, or review code quality; mentions complexity, maintainability, readability, spaghetti code, deeply nested logic, or god functions; or asks to check AI-generated code before merging. Also use proactively after writing any nontrivial function with heavy branching.

New to MCP?
From what the protocol is to installing your first server, these answers cover most first questions.
An open protocol that defines how AI applications connect to external tools and data in a uniform way. Clients talk to the model; MCP servers provide tools, resources and prompt templates. They exchange standard messages, so one server can be reused by many clients.