
关于 yandex-per-result
yandex-per-result 是托管的 MCP 服务和 API,可将 Yandex 搜索结果作为结构化 JSON 返回。它支持地区域名、语言和地区定位、分页及多种结果类型,并按页面计费。
主要功能
- 01搜索六个 Yandex 域名
- 02指定语言和地区
- 03独立选择结果类型
- 04按日期或排序方式筛选
- 05使用可配置的页数上限分页
适用场景
- 01比较不同地区的搜索结果
- 02研究俄语搜索结果
- 03检查广告和知识图谱条目
- 04收集图片和视频搜索结果
MCP 相关
托管的 MCP 服务将 Yandex Search API 作为工具提供给助手及其他 MCP 客户端。可通过 Apify MCP URL 连接,并使用 OAuth 或 Apify API token 验证。
配置
远程服务无需本地安装。选择你使用的客户端,复制配置或使用一键安装。
https://mcp.apify.com/?tools=johnvc/yandex-scrape-yandex-search-results-at-scale---per-resultclaude mcp add --transport http johnisanerd-yandex-per-result https://mcp.apify.com/?tools=johnvc/yandex-scrape-yandex-search-results-at-scale---per-result{"mcpServers":{"johnisanerd-yandex-per-result":{"type":"http","url":"https://mcp.apify.com/?tools=johnvc/yandex-scrape-yandex-search-results-at-scale---per-result"}}}在 Cursor 中打开{"servers":{"johnisanerd-yandex-per-result":{"type":"http","url":"https://mcp.apify.com/?tools=johnvc/yandex-scrape-yandex-search-results-at-scale---per-result"}}}在 VS Code 中打开{"mcpServers":{"johnisanerd-yandex-per-result":{"type":"http","url":"https://mcp.apify.com/?tools=johnvc/yandex-scrape-yandex-search-results-at-scale---per-result"}}}{"mcpServers":{"johnisanerd-yandex-per-result":{"serverUrl":"https://mcp.apify.com/?tools=johnvc/yandex-scrape-yandex-search-results-at-scale---per-result"}}}命令在终端中运行;JSON 粘贴到对应客户端的 MCP 配置后重启。需要授权的服务会在首次连接时提示登录。
工具
详细介绍
English | Русский
🔍 Yandex Search API:以整洁的 JSON 获取搜索结果,按页计费
每页搜索结果统一收取固定费用,包含所有结果类型。以开发者友好的方式使用 Yandex Search API。
Actor 页面: apify.com/johnvc/yandex-scrape-yandex-search-results-at-scale---per-result 输入架构: apify.com/johnvc/yandex-scrape-yandex-search-results-at-scale---per-result/input-schema
此 Yandex Search API 每次运行收取一次性的 Search Start 费用,此外每页搜索结果收取固定费用,因此费用随抓取的页数变化,而不受启用的结果类型数量影响。它会查询 Yandex——俄罗斯以及东欧和中亚多个市场占主导地位的搜索引擎,并返回整洁、结构化的 JSON,每页中每种结果类型对应一项。每项都包含搜索参数、结果数量,以及自然搜索结果、广告、知识图谱、内嵌图片和内嵌视频的数组。支持地区域名、语言和地区定位,以及分页。
此 Actor 最初按结果计费,并在 URL 和此仓库名称中保留了“per-result”,以确保现有链接继续有效。现在它按页计费,价格与我们的其他 Yandex 项目 Scrape Yandex 相同。
视频演示
快速开始
前提条件
- Python 3.11 或更高版本
- Apify 账户和 API 密钥(在此免费获取密钥)
-
克隆仓库
git clone https://github.com/johnisanerd/Apify-Yandex-Pay-Per-Result.git cd Apify-Yandex-Pay-Per-Result -
使用 UV 安装依赖项
# Install UV if you do not have it: curl -LsSf https://astral.sh/uv/install.sh | sh # Install project dependencies: uv sync -
配置 API 密钥
cp .env.example .env # Edit .env and add your Apify API key # Get your free API key at: https://apify.com?fpr=9n7kx3 -
运行示例
uv run python yandex-pay-per-result-scraper.py
替代方式:直接设置 API 密钥
export APIFY_API_TOKEN="your_api_key_here"
uv run python yandex-pay-per-result-scraper.py
为什么使用此 Yandex Search API?
每页一个价格。 无论一页返回多少种结果,都只计费一次;如果该页未返回所选结果,则不计费。因此它适用于探索性研究、关键词测试,以及不同查询的结果密度各异的工作负载。
独立的搜索索引。 Yandex 维护着自己的网络索引,其排名、地区内容和西里尔语覆盖范围均有独特之处,无法在其他地方找到。对于俄语研究、东欧市场或对比 SEO,它是独特的数据来源。
支持多个域名。 可定位 yandex.ru、yandex.com、yandex.com.tr、yandex.by、yandex.kz 和 yandex.uz,再搭配 lang 和 lr,精确控制地区索引和语言变体。
丰富的结果类型。 除了自然搜索结果,每页还会以结构化输出返回广告、知识图谱条目、内嵌图片块和内嵌视频轮播。
价格可预测,按使用量付费。 按页计费,每次运行另收一次性的 Search Start 费用,无需订阅;max_pages 上限可让你控制成本。
易于自动化。 只需几行 Python 代码即可调用,也可以将其加载为 MCP 工具,让 Claude 和 Cursor 等助手按需为你执行 Yandex 搜索。
功能
核心功能
- Yandex 搜索,支持 6 个地区域名
- 按需选择结果类型:可分别启用或停用自然搜索结果、广告、知识图谱、内嵌图片和内嵌视频;启用更多类型不会提高每页价格
- 使用
lang和lr控制语言和地区 - 排序和时效筛选:
sort_mode(相关性或日期)和period(全部、当天、最近两周、一个月) - 并行抓取多页,可配置
max_pages上限 - 按页计费:每次运行收取一次 Search Start 费用,之后按交付的页数收取固定费用
数据质量
- 每个结果类型每页一个条目,并标记
item_type和result_count - 包含位置、标题、链接、摘要和显示链接的
organic_results数组 - 每个条目都会回显结果数量和元数据
- 广告、知识图谱、图片和视频分别使用独立数组
- 所有查询的 JSON 结构保持一致
使用示例
基本搜索
{
  "text": "machine learning tutorial",
  "max_pages": 1
}
使用语言和区域定位的地区域名
{
  "text": "машинное обучение учебник",
  "yandex_domain": "yandex.ru",
  "lang": "ru",
  "lr": "213",
  "max_pages": 1
}
输入参数
| 参数 | 类型 | 必填 | 默认值 | 描述 |
|---|---|---|---|---|
text | string | 是 | - | 搜索查询。支持 Yandex 支持的任意运算符,例如 site:wikipedia.org python。 |
include_organic_results | boolean | 否 | true | 返回自然搜索结果(item_type 为 organic)。 |
include_ads | boolean | 否 | false | 存在付费广告时返回这些广告(item_type 为 ads)。 |
include_knowledge_graph | boolean | 否 | false | 存在知识图谱卡片时返回该卡片(item_type 为 knowledge_graph)。 |
include_inline_images | boolean | 否 | false | 返回内嵌图片栏(item_type 为 inline_images)。 |
include_inline_videos | boolean | 否 | false | 返回内嵌视频轮播(item_type 为 inline_videos)。 |
yandex_domain | string | 否 | yandex.com | Yandex 域名,例如 yandex.ru、yandex.com.tr(支持 6 个)。 |
lang | string | 否 | (域名默认值) | 语言代码,例如 en、ru。多种语言用逗号分隔。 |
lr | string | 否 | (域名默认值) | 国家或地区 ID,例如 84(美国)、213(莫斯科)、225(俄罗斯)。 |
max_pages | integer | 否 | 2 | 要获取的最大页数;0 = 不限。适用于每种选定的结果类型。 |
sort_mode | string | 否 | relevance | 结果排序方式:relevance 或 date(最新优先)。 |
period | string | 否 | all | 时间范围:all、day、last_two_weeks、month。 |
output_file | string | 否 | - | 用于保存结果的可选文件名。 |
输出格式
页面上出现的每种选定结果类型都会作为独立的数据集条目返回,并标记 item_type(organic、ads、knowledge_graph、inline_images 或 inline_videos)和 result_count;每个条目计为一个结果。下面展示了 machine learning tutorial 的代表性 organic 条目(此处的 organic_results 数组已精简为仅包含一个结果)。
{
  "item_type": "organic",
  "result_count": 10,
  "text": "machine learning tutorial",
  "yandex_domain": "yandex.com",
  "lang": "en",
  "lr": "84",
  "max_pages": 1,
  "search_timestamp": "2026-05-29T11:51:33",
  "total_results_found": 10,
  "pages_processed": 1,
  "page_number": 1,
  "search_domain_description": "United States",
  "search_language_description": "English",
  "results_per_page": 10,
  "organic_results": [
    {
      "position": 2,
      "title": "Machine Learning Tutorial - GeeksforGeeks",
      "link": "https://www.geeksforgeeks.org/machine-learning/machine-learning/",
      "snippet": "Machine Learning is mainly divided into three core types: Supervised Learning: Trains models on labeled data to predict or classify new, unseen data.",
      "displayed_link": "geeksforgeeks.org > machine-learning > machine"
    }
  ],
  "ads_results": [],
  "knowledge_graph": [],
  "inline_images": [],
  "inline_videos": []
}
每个页面条目都会回显搜索参数和结果数量,在 organic_results 中列出所有自然搜索结果(包含位置、标题、链接、摘要和显示链接;视频和新闻结果还可能包含 duration 和 date),并分别返回 ads_results、knowledge_graph、inline_images 和 inline_videos 数组。
用作 MCP 工具
你可以将 Yandex Search API 加载为 MCP 工具,让助手代你调用。MCP 服务 URL 会预加载这一个 Actor:
https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result
出现提示时,可在浏览器中使用 OAuth 进行身份验证,也可以使用你的 Apify API 令牌(与 Python 示例中使用的 APIFY_API_TOKEN 相同)。可在 https://console.apify.com/settings/integrations 获取令牌,并在 https://apify.com?fpr=9n7kx3 注册免费的 Apify 账户。
在 Claude Cowork Desktop 中安装
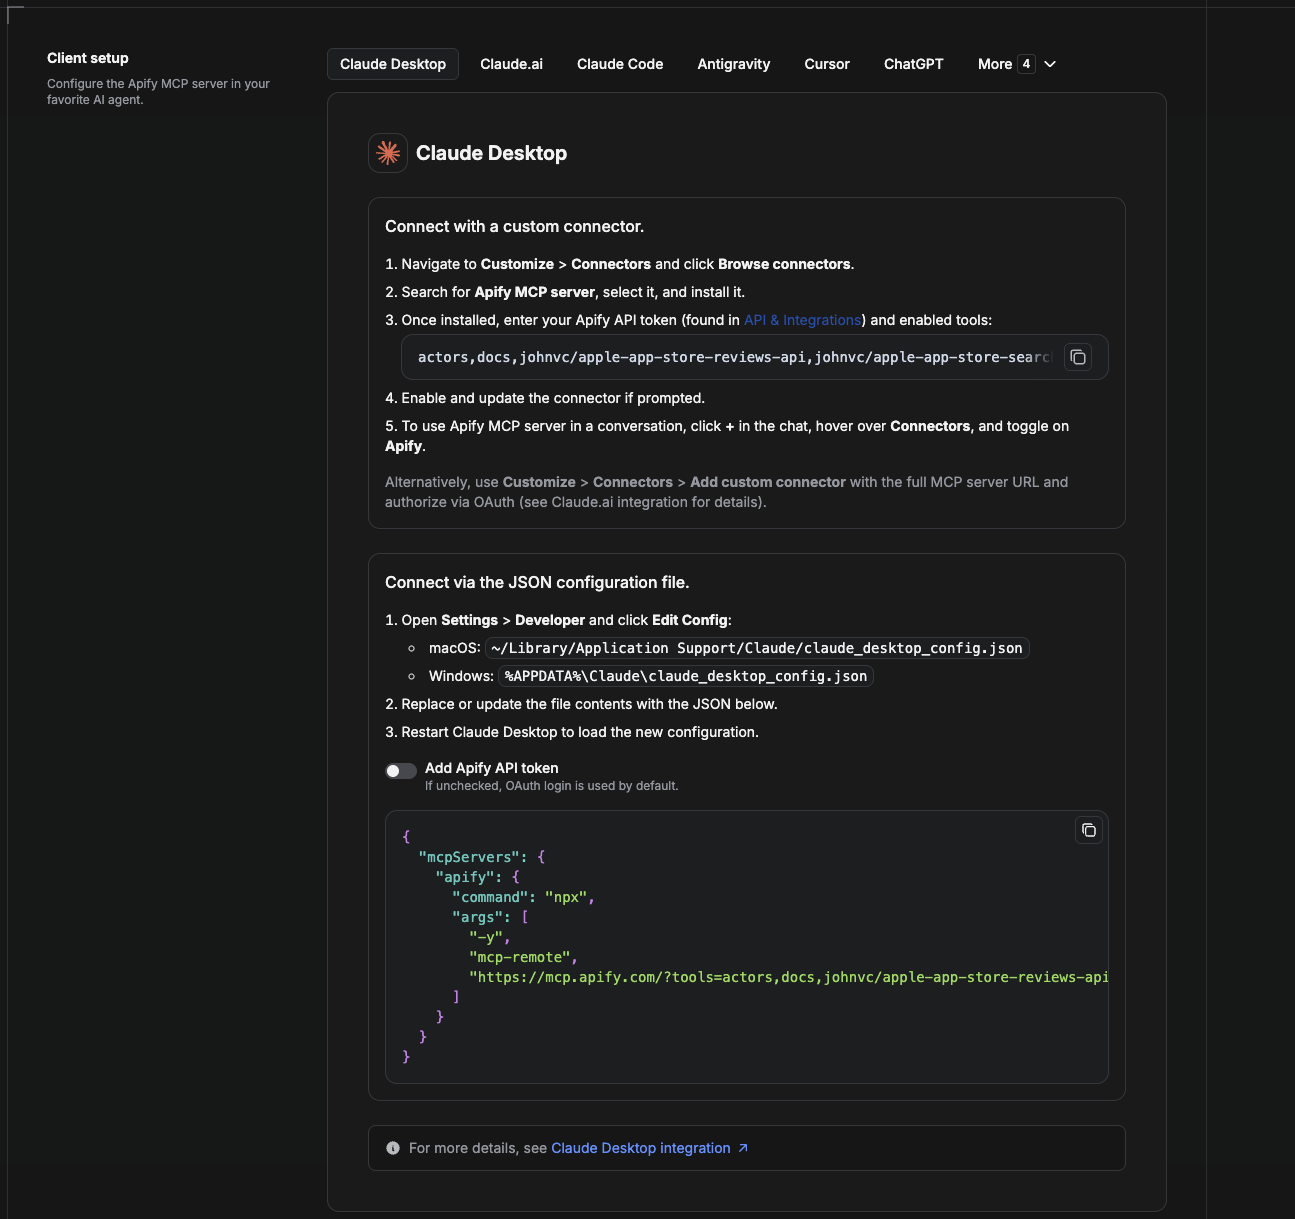
Cowork 是桌面应用的自动化模式。要将 Yandex Search API 用作工具,请添加 Apify MCP 服务作为连接器。
- 打开 Claude 桌面应用,然后前往 Settings → Connectors(或前往 Settings → Developer → Edit Config,直接编辑
claude_desktop_config.json)。- macOS:
~/Library/Application Support/Claude/claude_desktop_config.json - Windows:
%APPDATA%\Claude\claude_desktop_config.json
- macOS:
- 添加 Apify MCP 服务,并且只预加载此 Actor:
{
  "mcpServers": {
    "apify": {
      "command": "npx",
      "args": [
        "-y",
        "mcp-remote",
        "https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result"
      ]
    }
  }
}
- 重启应用。当 Cowork 首次调用该工具时,请在浏览器中完成 OAuth 提示,或在连接器设置中添加 Apify API 令牌以跳过 OAuth。
- 在 Cowork 聊天中,确认该工具可用,并让它运行 Yandex Search API。
下载桌面应用并开始免费试用:https://claude.ai/referral/uIlpa7nPLg 更多帮助:https://docs.apify.com/platform/integrations/claude-desktop
在 Claude Code 中安装
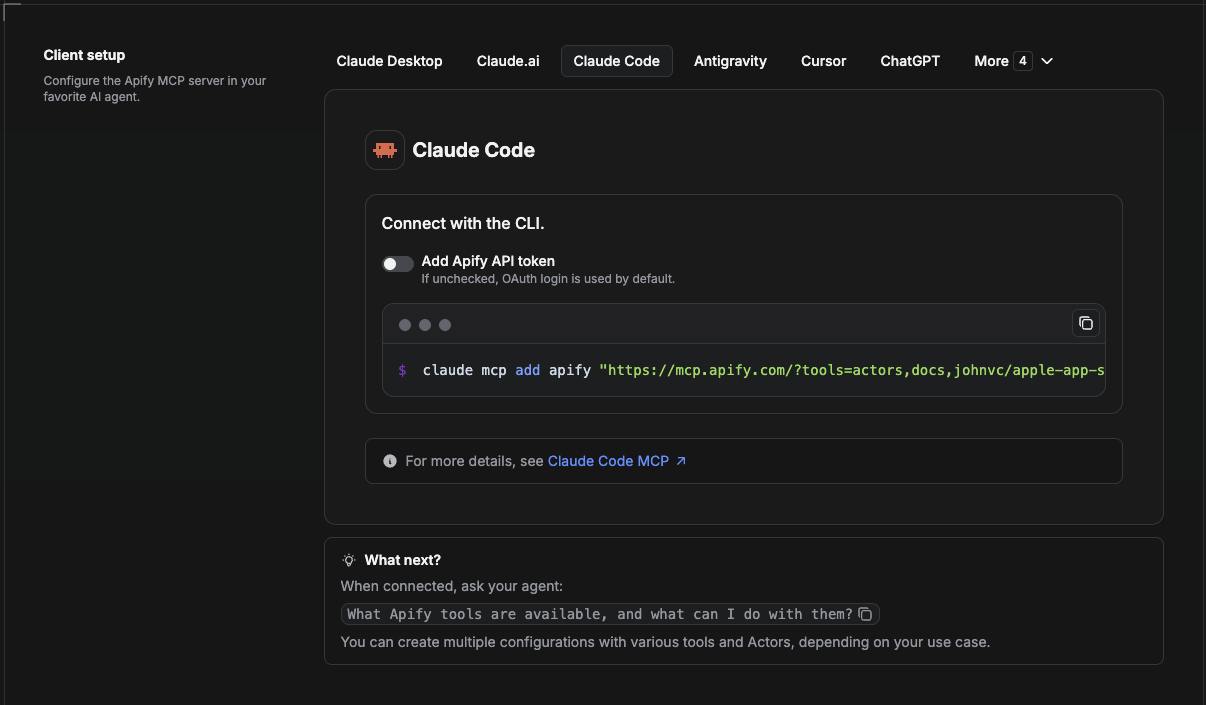
Claude Code 是命令行工具。只需运行一条命令,即可添加 Actor 的 MCP 服务:
claude mcp add --transport http apify \
  "https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result"
要使用令牌而非浏览器 OAuth:
claude mcp add --transport http apify \
  "https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result" \
  --header "Authorization: Bearer YOUR_APIFY_TOKEN"
然后使用 claude mcp list 验证,或在会话中运行 /mcp。让 Claude Code 调用 Yandex Search API。
免费试用 Claude Code:https://claude.ai/referral/uIlpa7nPLg Claude Code MCP 文档:https://code.claude.com/docs/en/mcp
在 Claude(网站版)中安装
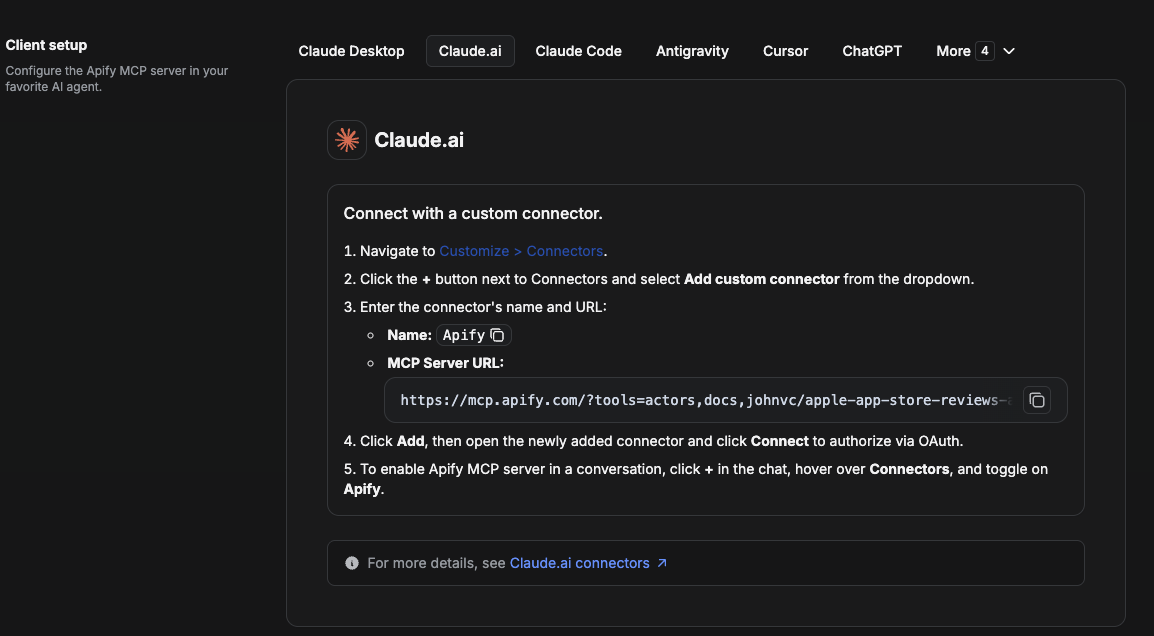
在 claude.ai 上,先将 Apify 添加为连接器,然后仅启用此 Actor 的工具。
- 前往 Settings → Connectors → Browse connectors,搜索 Apify MCP server。安装它(如果出现提示,则启用或更新)。
- 连接时,使用 Apify API 令牌进行身份验证,并启用工具
johnvc/yandex-scrape-yandex-search-results-at-scale---per-result。 - 在任意聊天中,打开 + → Connectors,然后开启 Apify。
- 或者,选择 Add custom connector,粘贴完整的 MCP URL
https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result,并在出现提示时使用 OAuth。 - 让 Claude 运行 Yandex Search API。
在网页上打开 Claude:https://claude.ai/referral/uIlpa7nPLg
在 Cursor 中安装
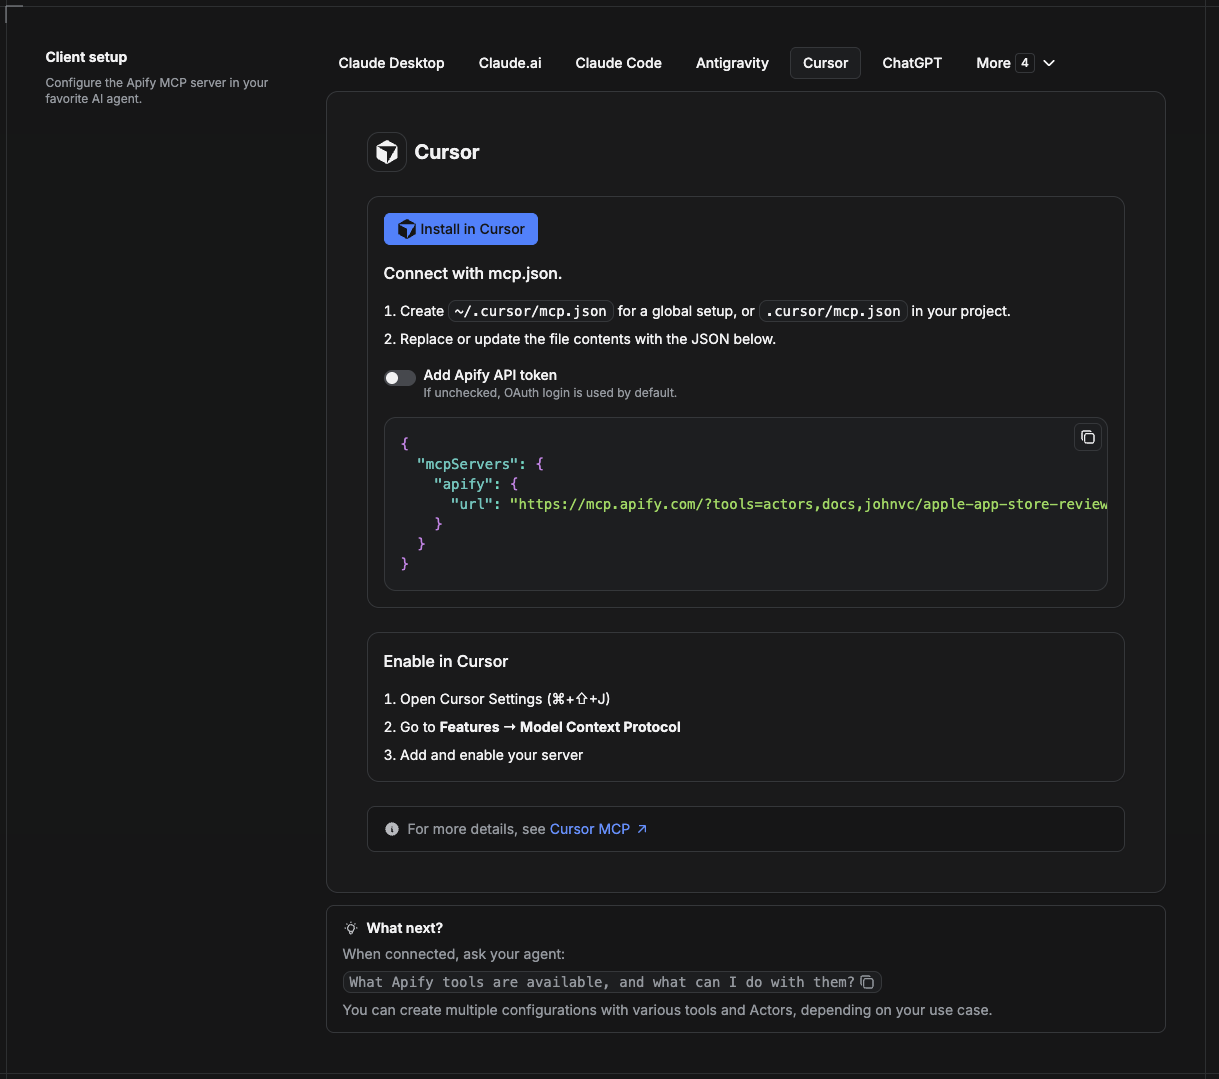
Cursor 从项目文件 .cursor/mcp.json 中读取 MCP 服务。
- 在项目中创建
.cursor/mcp.json:
{
  "mcpServers": {
    "apify": {
      "url": "https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result"
    }
  }
}
- 如果你希望使用令牌身份验证,而非浏览器 OAuth,请添加一个标头:
{
  "mcpServers": {
    "apify": {
      "url": "https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result",
      "headers": { "Authorization": "Bearer YOUR_APIFY_TOKEN" }
    }
  }
}
- 打开 Cursor → Settings → MCP,确认 apify 服务已连接(显示绿点)。
- 在 Composer 或 Chat 中,让 Cursor 调用 Yandex Search API。
刚开始使用 Cursor?在这里获取:https://cursor.com/referral?code=XQP4VBLI3NNX
在 ChatGPT 中安装
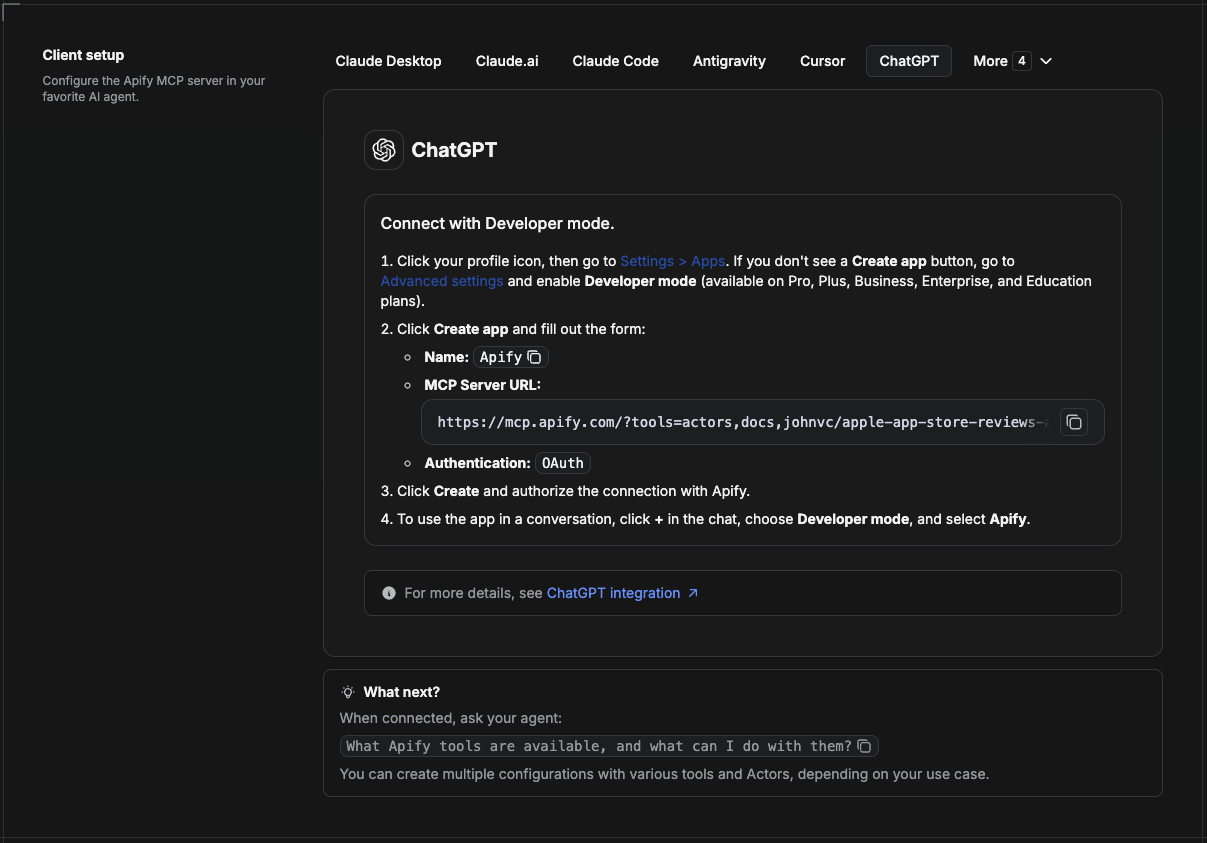
ChatGPT 通过开发者模式连接到 Apify MCP 服务(适用于 ChatGPT Pro、Plus、Business、Enterprise 和 Education 套餐)。
- 点击个人资料图标,然后进入 设置 > 应用。如果看不到 创建应用 按钮,请打开 高级设置 并启用 开发者模式。
- 点击 创建应用 并填写表单:
- 名称: Apify
- MCP 服务 URL:
https://mcp.apify.com/?tools=actors,docs,johnvc/yandex-scrape-yandex-search-results-at-scale---per-result - 身份验证: OAuth
- 点击 创建,并通过 Apify 授权连接。
- 要在对话中使用该应用,请点击聊天中的 +,选择 开发者模式,然后选择 Apify。
更多帮助:https://docs.apify.com/platform/integrations/mcp
使用 Yandex Search API 获取 SEO 研究、市场情报和多语言内容分析所需的可靠结构化结果。
精选任务
Apify Store 中可直接运行的示例。
🤖 向 AI 助手咨询此 Actor
在你选择的 AI 中打开一条关于 Yandex Search API 的现成提示词:
- 💬 ChatGPT
- 🧠 Claude
- 🔍 Perplexity
- 🅒 Copilot
最后更新:2026.10.27
评论
一个开放协议,规定了 AI 应用如何以统一方式连接外部工具与数据源。客户端负责与模型对话,MCP 服务负责提供工具、资源和提示模板,两者通过标准消息通信,同一个服务可以被不同客户端复用。